llm-compression
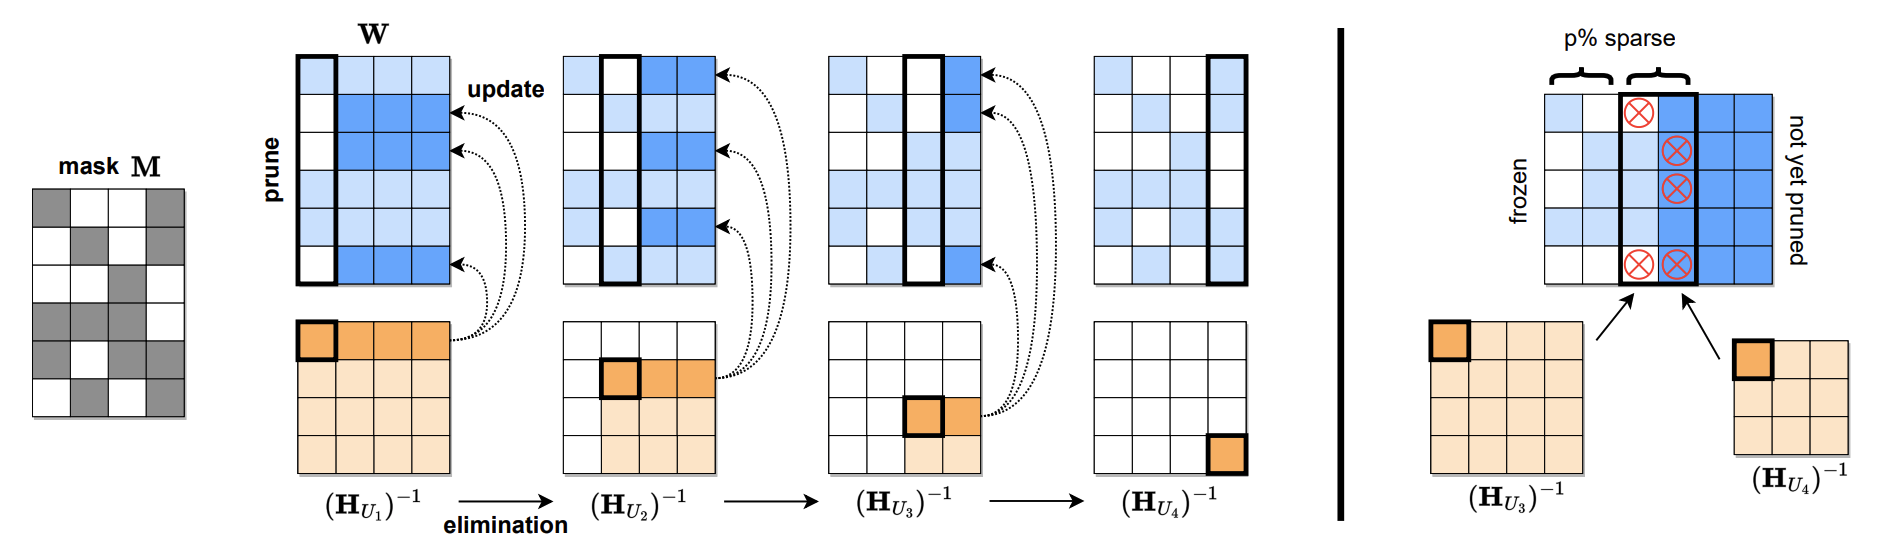


claw-compactor
14-stage Fusion Pipeline for LLM token compression — reversible compression, AST-aware code analysis, intelligent content routing. Zero LLM inference cost. MIT licensed.
- 2k
- Python
- MIT
- 8 mo ago


AngelSlim
Model compression toolkit engineered for enhanced usability, comprehensiveness, and efficiency.
- 1.8k
- Python
- 3 d ago

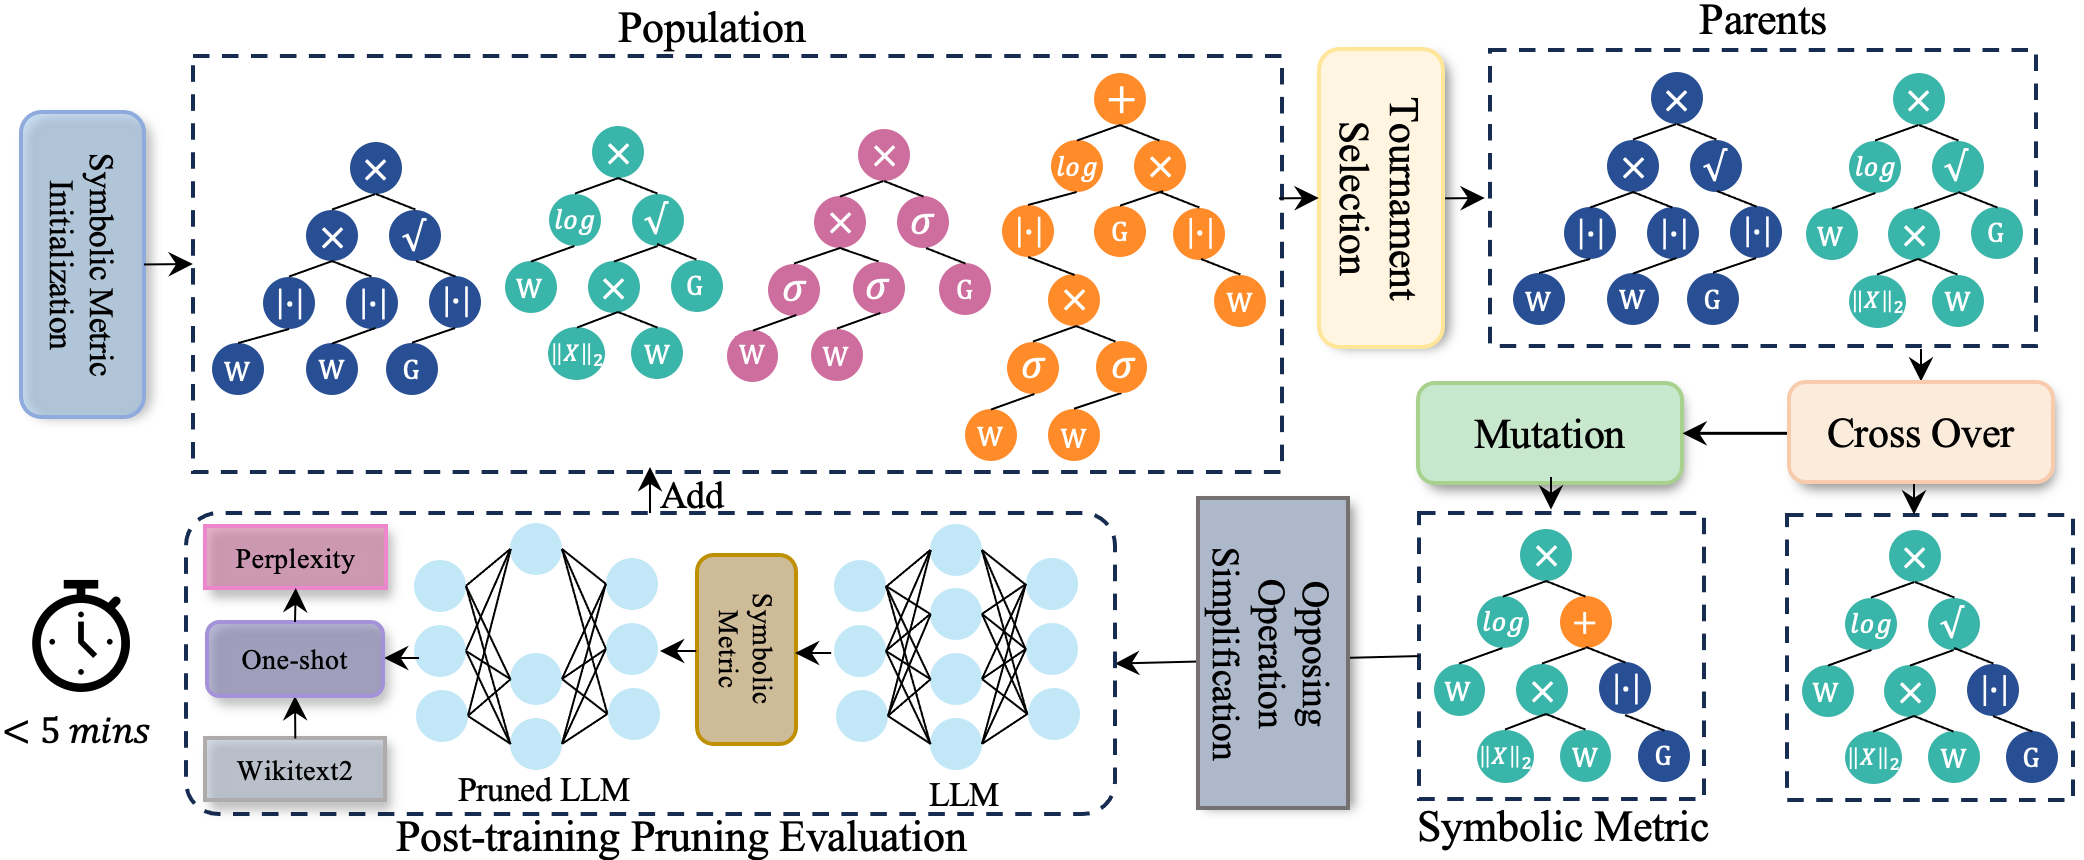
Pruner-Zero
[ICML24] Pruner-Zero: Evolving Symbolic Pruning Metric from scratch for LLMs
- 100
- Python
- MIT
- 24 mo ago

llm-kick
[ICLR 2024] Jaiswal, A., Gan, Z., Du, X., Zhang, B., Wang, Z., & Yang, Y. Compressing llms: The truth is rarely pure and never simple.
- 27
- Python
- 19 mo ago

GLVQ
[NeurIPS 2025] Official PyTorch reimplementation of paper "Learning Grouped Lattice Vector Quantizers for Low-Bit LLM Compression".
- 18
- Python
- Apache-2.0
- 3 d ago

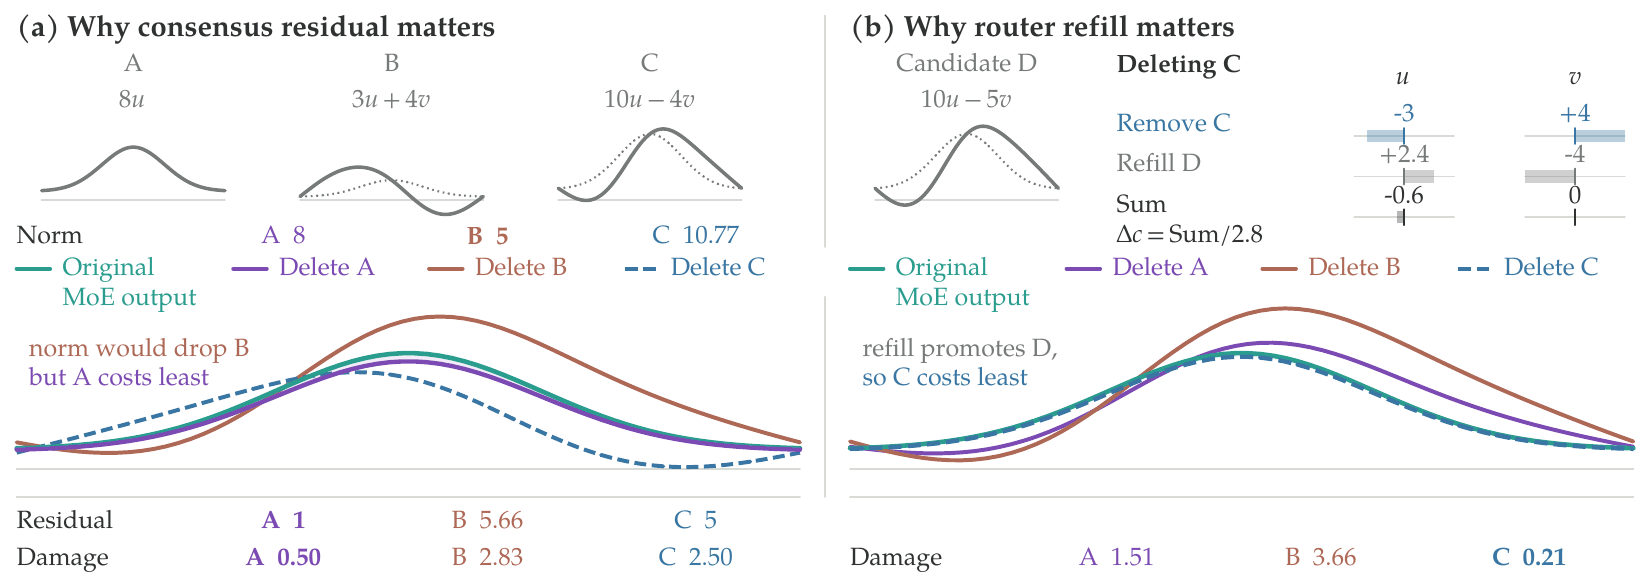
RAZOR
RAZOR: Pruning Replaceable Experts in LLMs — training-free expert pruning for Mixture-of-Experts (MoE) models, with the MoECal calibration corpus
- 7
- Python
- Apache-2.0
- 7 wk ago

Less-is-MoE
Less is MoE (EMNLP 2026 Main); Fisher-MoE: intra-expert structured pruning and compression for Mixture-of-Experts (MoE) LLMs. Prunes FFN intermediate dimensions by Fisher importance instead of dropping whole experts. Official code.
- 4
- Python
- Apache-2.0
- 8 wk ago

vq-llm-compression
- 0
- 0
- apache-2.0
- 5 mo ago