awesome-computer-vision-resources
a collection of computer vision projects&tools. 计算机视觉方向项目和工具集合。
- 369
- 2 y ago
a collection of computer vision projects&tools. 计算机视觉方向项目和工具集合。
A curated collection of AI, data engineering, and DevOps projects featuring real-world applications, advanced techniques, and tutorials—ideal for learners and practitioners exploring data science and machine learning.
This repository contains notebooks that show the usage of TensorFlow Lite for quantizing deep neural networks.
Official code for the Manning book on structural LLM optimization: depth/width pruning, knowledge distillation, and attention optimization, runnable on free Colab GPUs.
TinyML & Edge AI: On-device inference, model quantization, embedded ML, ultra-low-power AI for microcontrollers and IoT devices.
A Systems View of Efficient Machine Learning, from Silicon to Agents. Fourteen parts, from roofline analysis and vector units up through kernels, compilers, quantisation, compression, vision, on-device language models, robotics, profiling, serving and agents.
NCNN Framework: High-performance neural network inference for mobile, embedded, and edge AI deployment.
This repository includes code for the paper "Towards Zero Touch Networks: Cross-Layer Automated Security Solutions for 6G Wireless Networks" published in IEEE TCOM, focusing on autonomous cybersecurity (physical-layer authentication and cross-layer intrusion detection) using AutoML techniques.
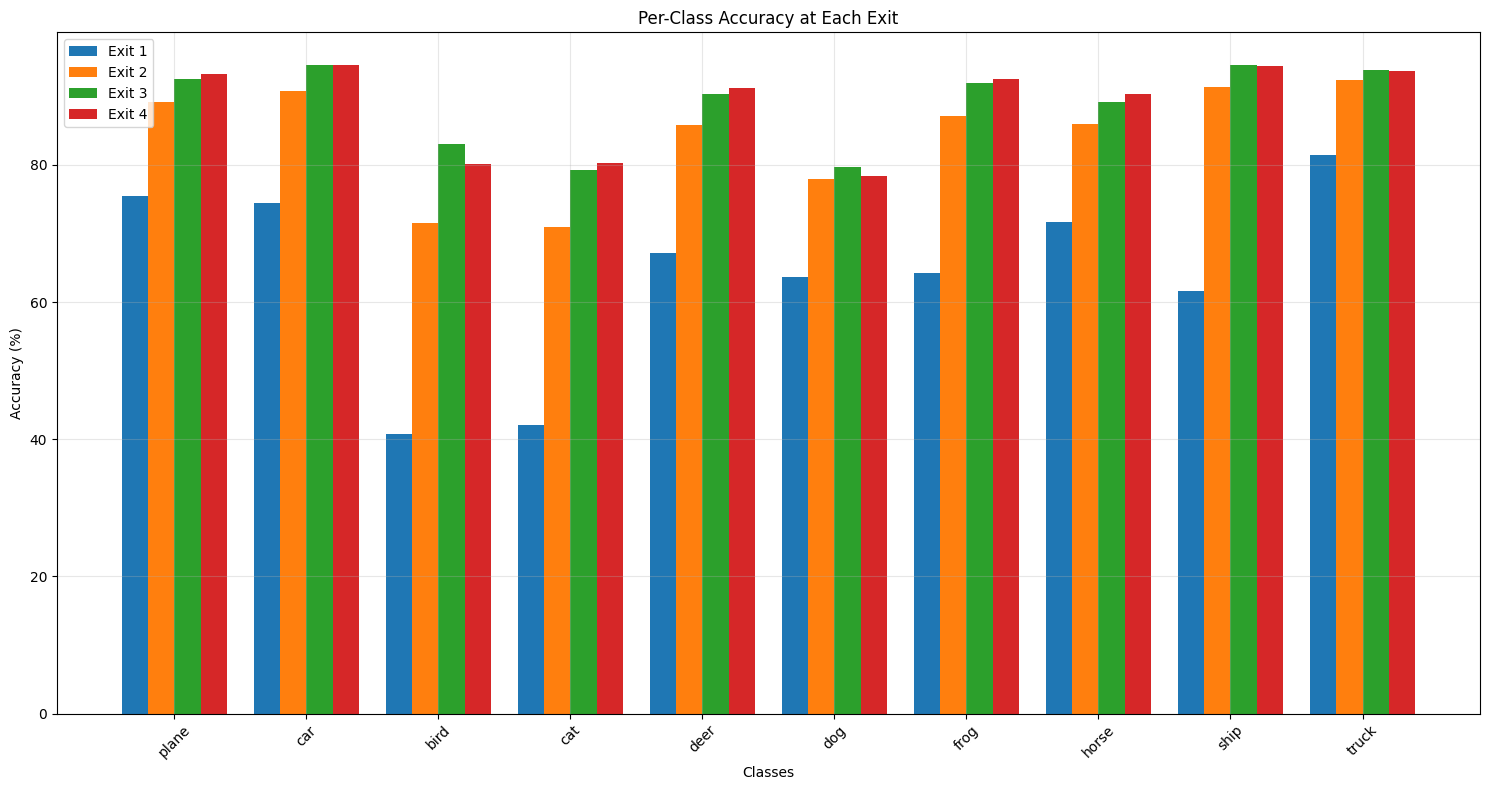
A deep learning framework that implements Early Exit strategies in Convolutional Neural Networks (CNNs) using Deep Q-Learning (DQN). This project enhances computational efficiency by dynamically determining the optimal exit point in a neural network for image classification tasks on CIFAR-10.
Convert and optimize BirdNET models for ONNX Runtime inference on GPUs, CPUs, and embedded devices
Mobile AI: iOS CoreML, Android TFLite, on-device inference, ONNX, TensorRT, and ML deployment for smartphones.
40x faster AI inference: ONNX to TensorRT optimization with FP16/INT8 quantization, multi-GPU support, and deployment
A curated list of awesome open source tools and commercial products for autoML hyperparameter tuning 🚀
Learn linear quantization techniques using the Quanto library and downcasting methods with the Transformers library to compress and optimize generative AI models effectively.
Comprehensive performance analysis of DeepSeek V3 quantization levels (FP16, Q8_0, Q4_0) on 16GB GPU environments.
A practical Large Language Model (LLM) full fine-tuning repository featuring end-to-end implementations of dataset preparation, tokenization, supervised fine-tuning (SFT), transformer model training, loss optimization, evaluation, and model checkpoint management using Python, PyTorch, and Hugging Face Transformers.
Step-by-step implementation of next-generation LLM components. Deep dive into Quantization, TTT layers, Differentiable Logic, FlashAttention tiling, and context extension, culminating in an end-to-end hardware-friendly Mini-LLM.
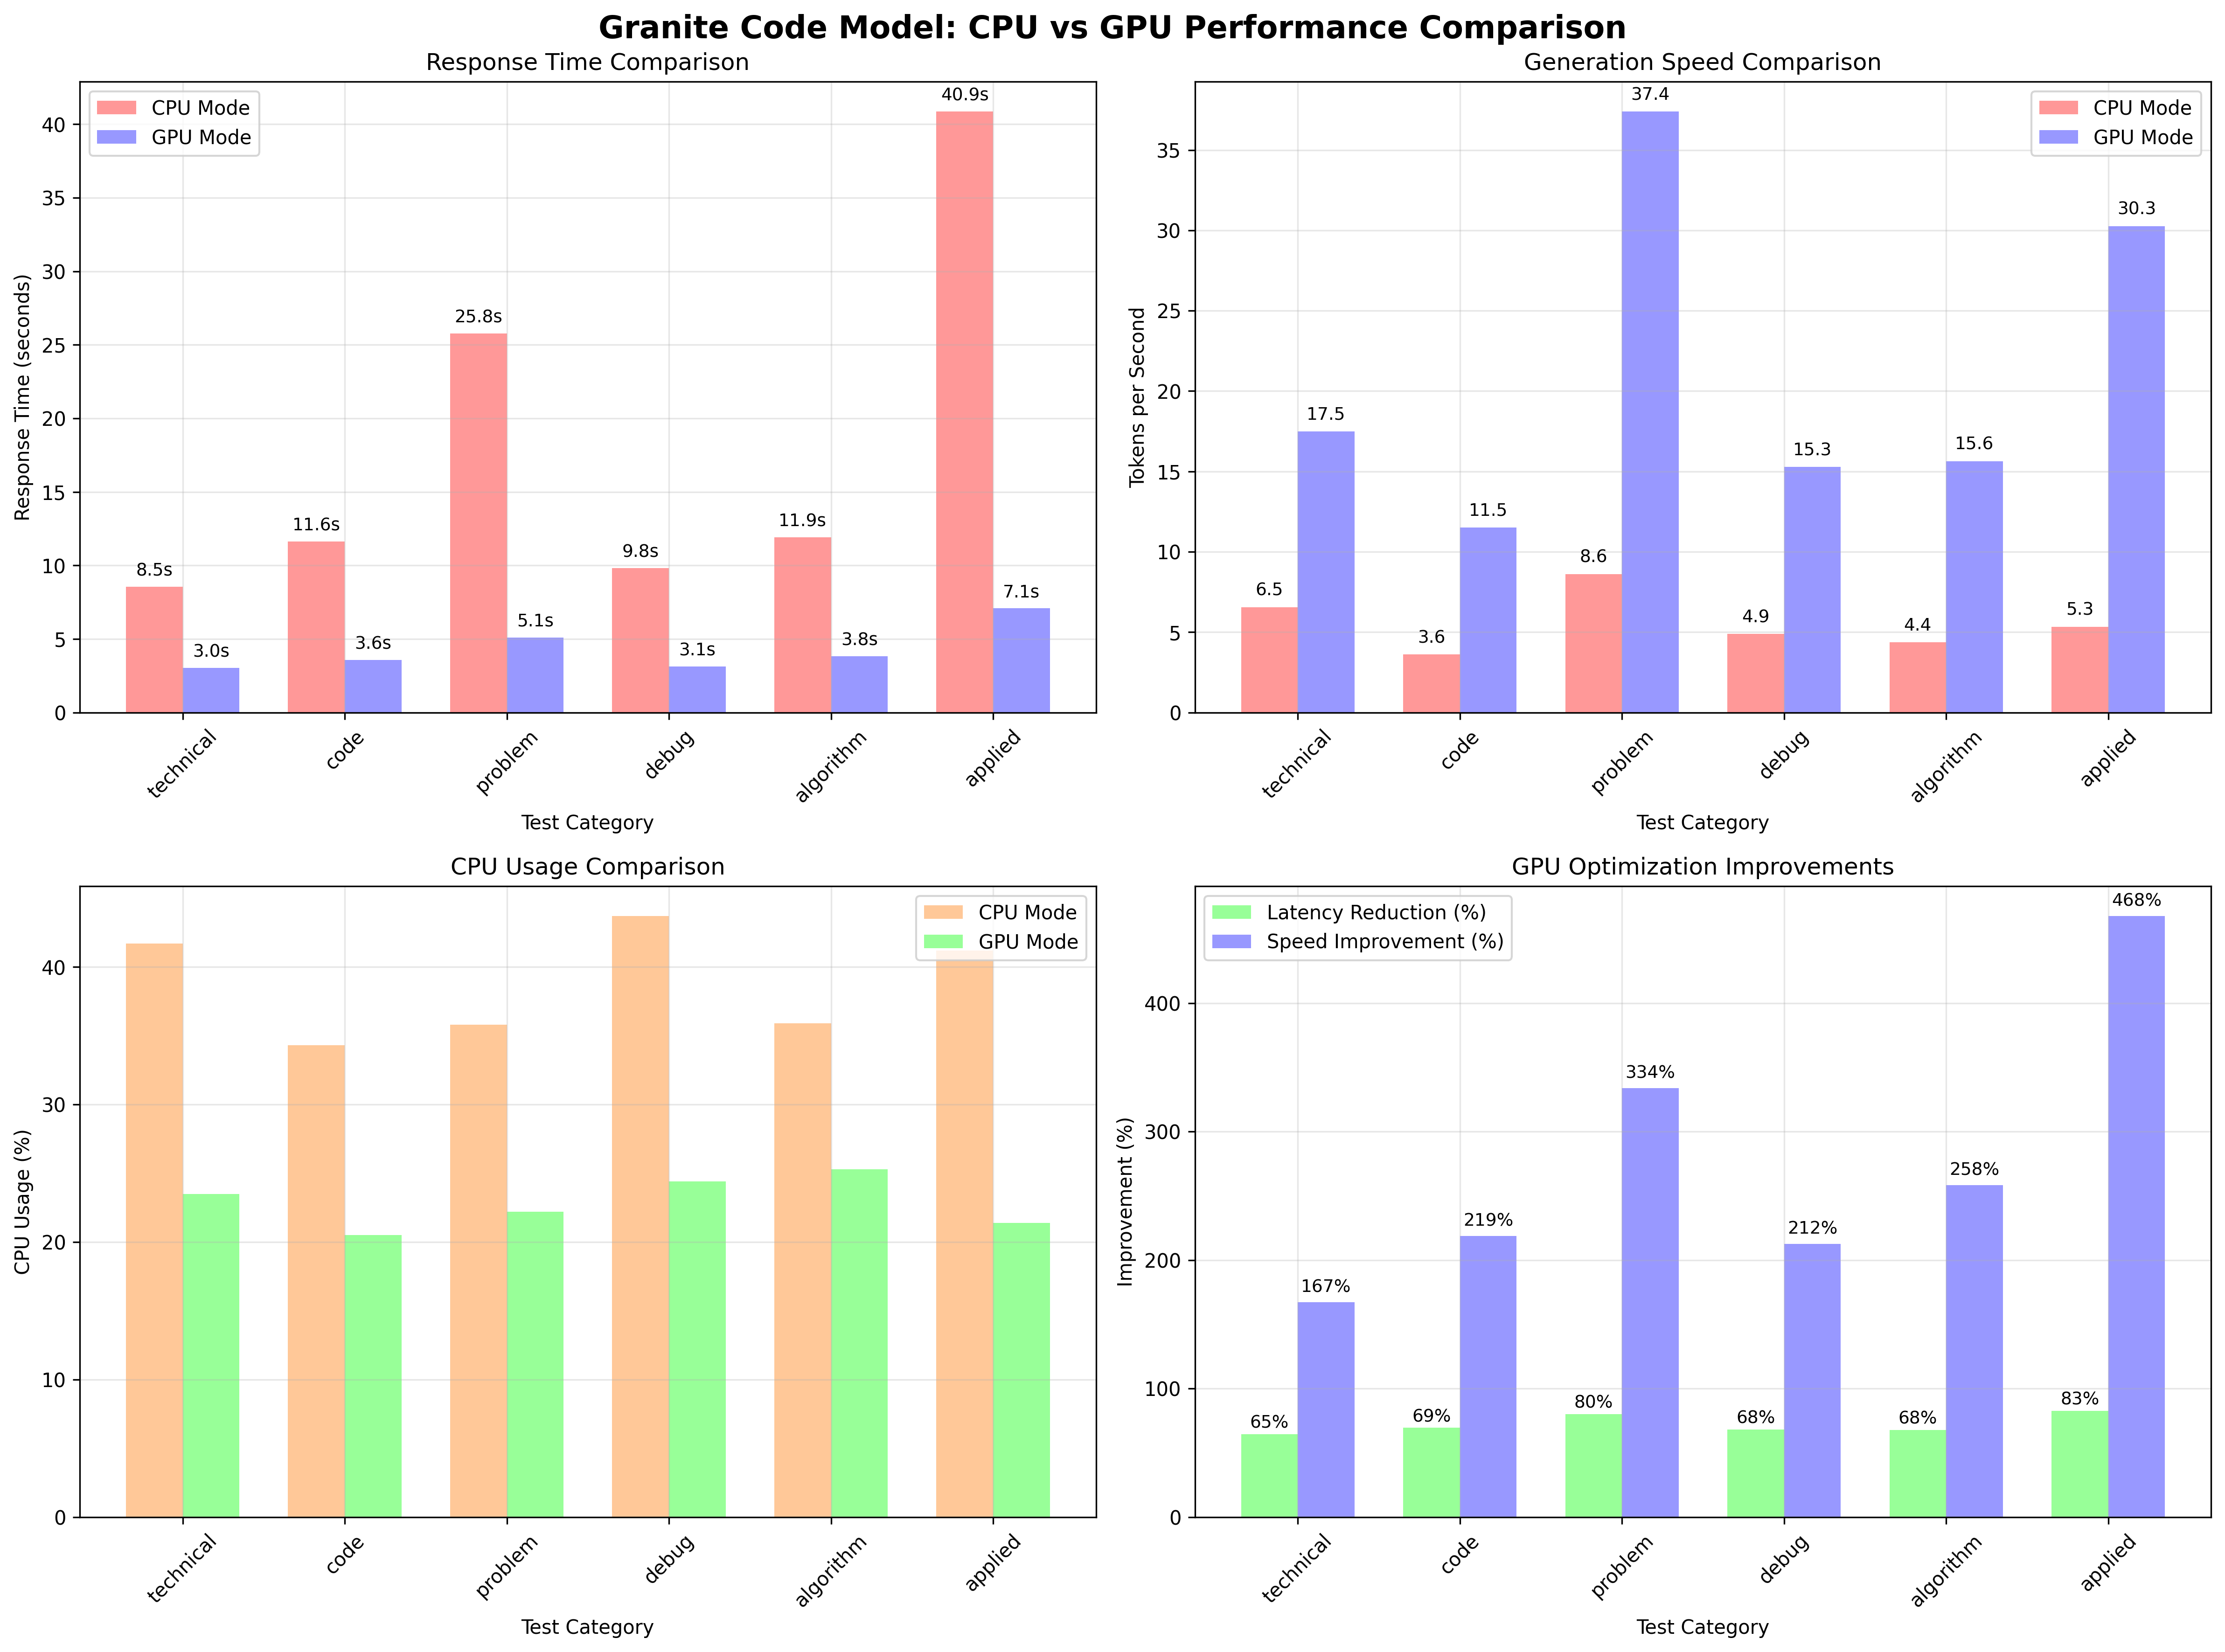
GPU-accelerated IBM Granite Code model optimization achieving 3-5x performance improvement. Complete benchmarking suite with real-time monitoring and visualization.
Using vLLM compressor to quantize Qwen3-0.6B using GPTQ to W4A16