neural-compressor
SOTA low-bit LLM quantization (INT8/FP8/MXFP8/INT4/MXFP4/NVFP4) & sparsity; leading model compression techniques on PyTorch, TensorFlow, and ONNX Runtime
- 2.7k
- Python
- Apache-2.0
- 2 d ago
SOTA low-bit LLM quantization (INT8/FP8/MXFP8/INT4/MXFP4/NVFP4) & sparsity; leading model compression techniques on PyTorch, TensorFlow, and ONNX Runtime
Strata fork: Qwen3.8-Flash-Next 125B MoE in NVFP4 on one RTX 20-50 card (12 GB+) and 64 GB of RAM or more. Setup installs our GPTQ quants (huihui abliterated, OrcaRouter) from Hugging Face. CPU experts on AVX-512 or AVX2 (+AVX-VNNI), all experts in RAM from 92 GB, a low-RAM mode below, vision, W4A8 prompts. Windows / CUDA 13.
Image text to text model, used with transformers.
Text generation model, used with transformers.
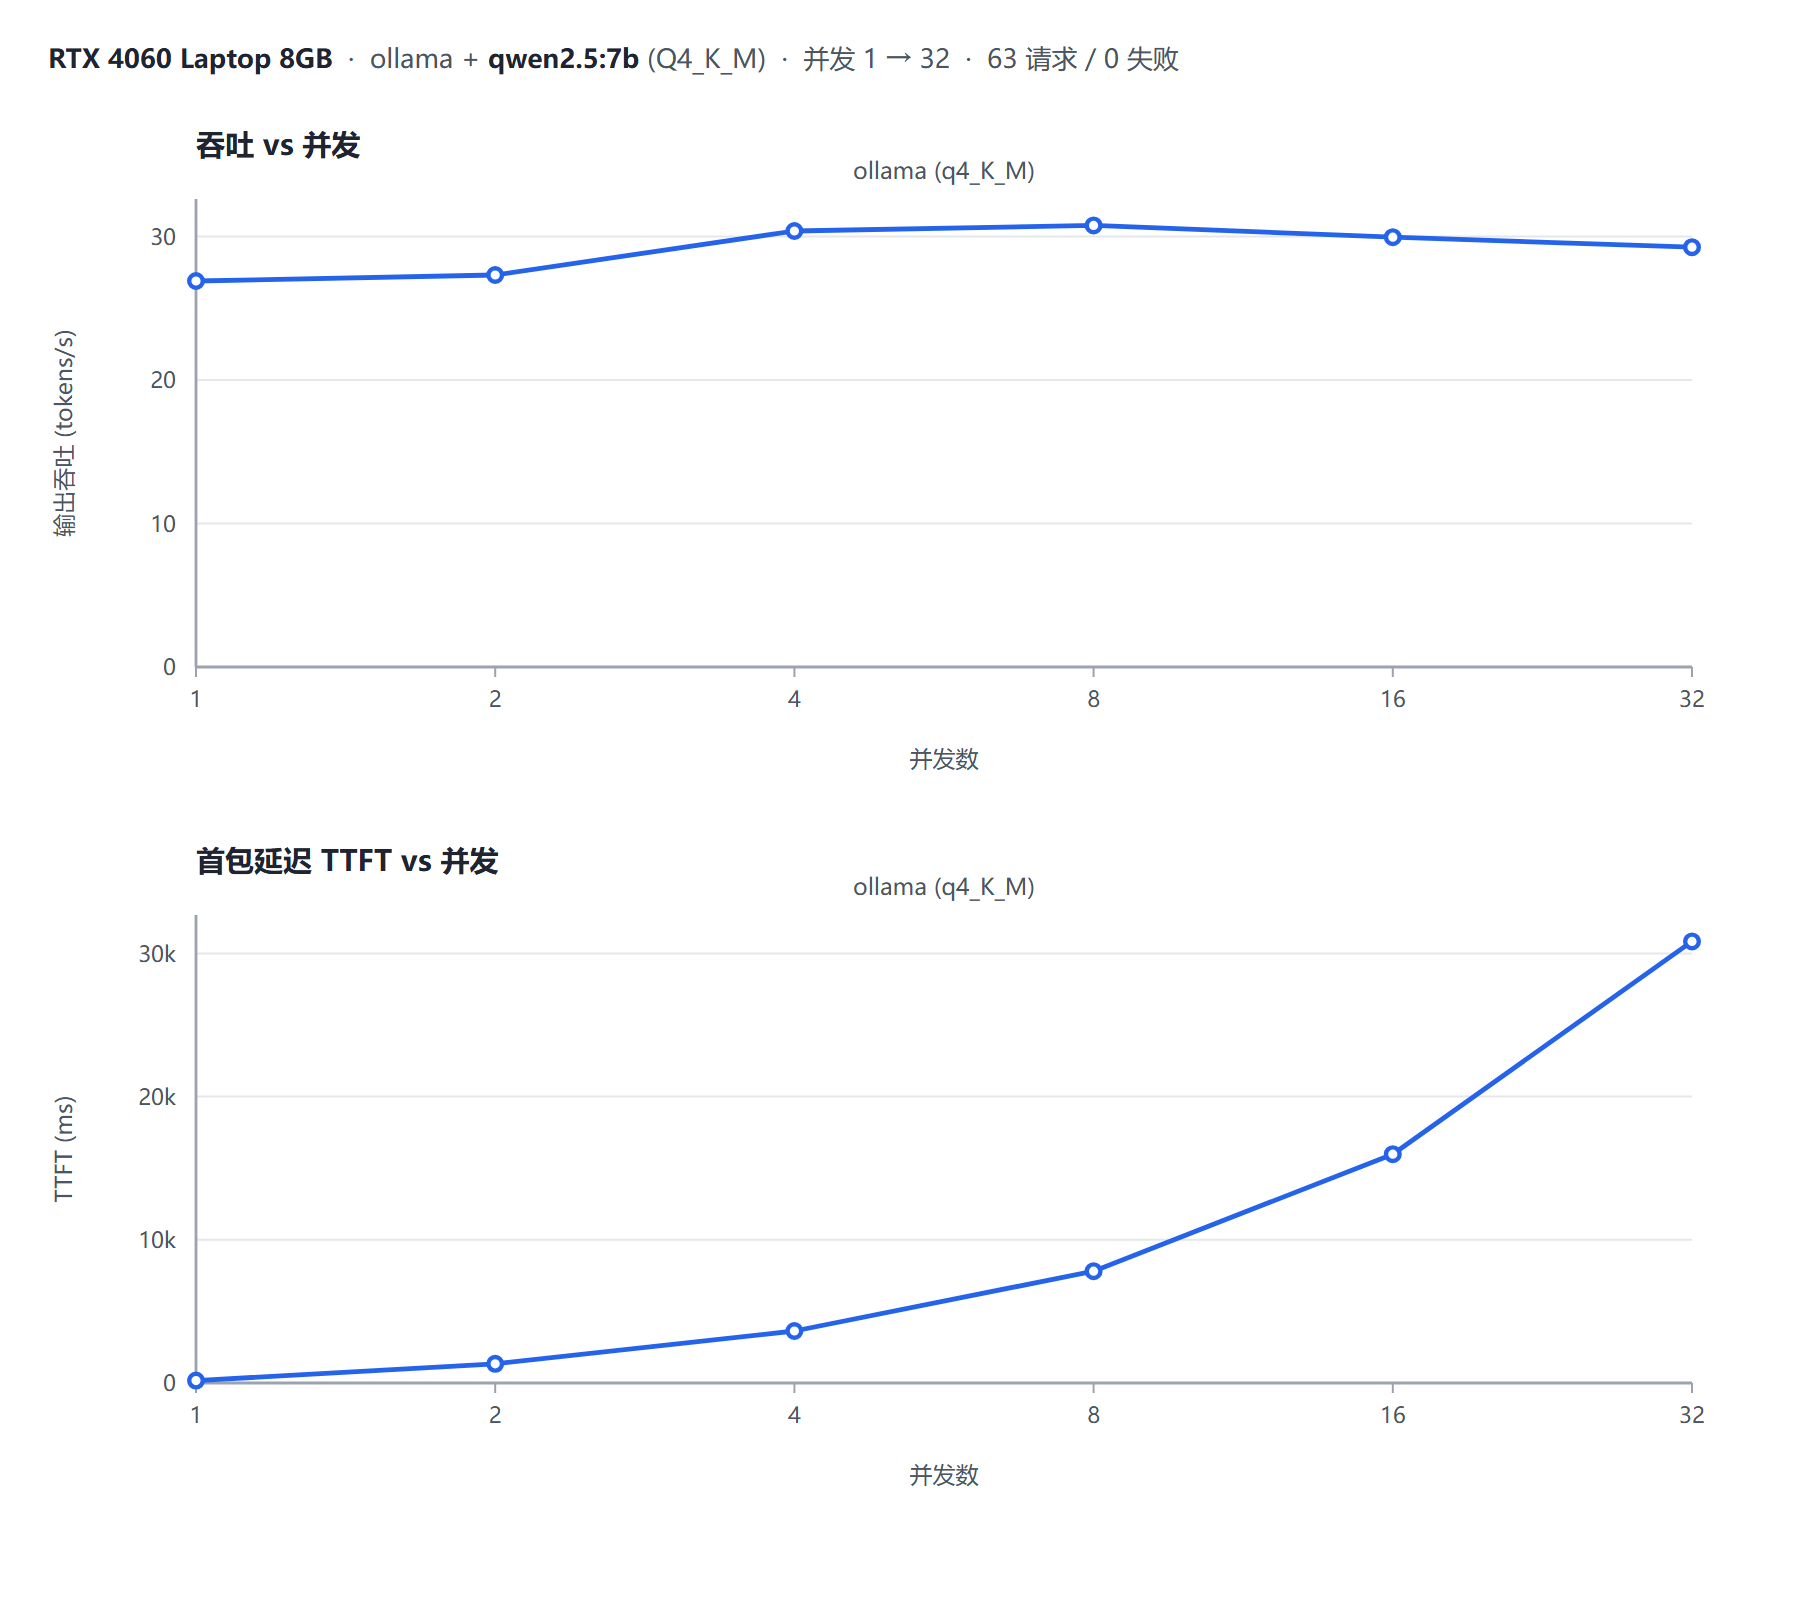
Benchmark self-hosted LLM inference across engines (vLLM, Ollama) and quantisation levels (FP16 / INT8 / AWQ / GPTQ). Concurrency sweeps, TTFT / TPOT / P99 tail latency, VRAM curves, Prometheus + Grafana, self-contained HTML reports.
Low-bit LLM inference engine in Rust + CUDA. Converts models to a 4-bit .wstone format (3.75x smaller) and runs them on consumer GPUs. Built for memory-bandwidth-bound decode on Turing, where bytes per weight — not TOPS — sets token throughput.
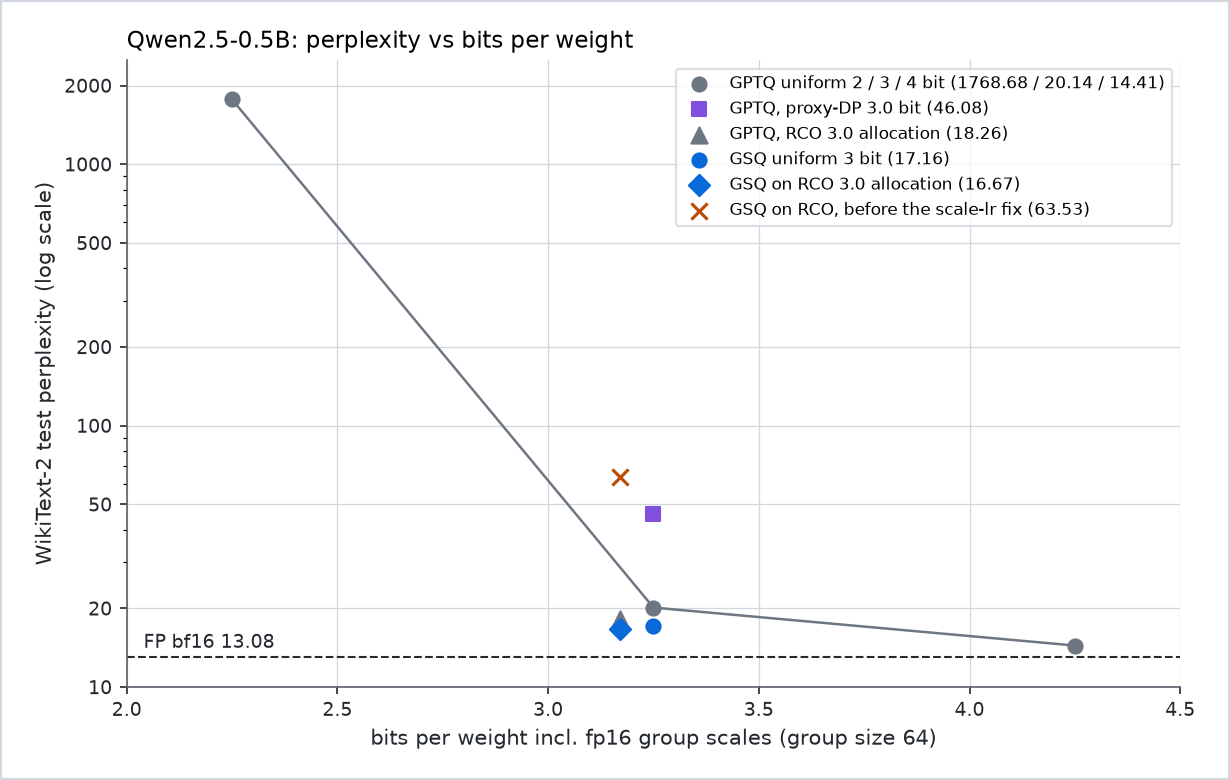
GSQ quantization + RCO bit allocation for low-bit LLMs in MLX on Apple Silicon
Effortlessly quantize, benchmark, and publish Hugging Face models with cross-platform support for CPU/GPU. Reduce model size by 75% while maintaining performance.
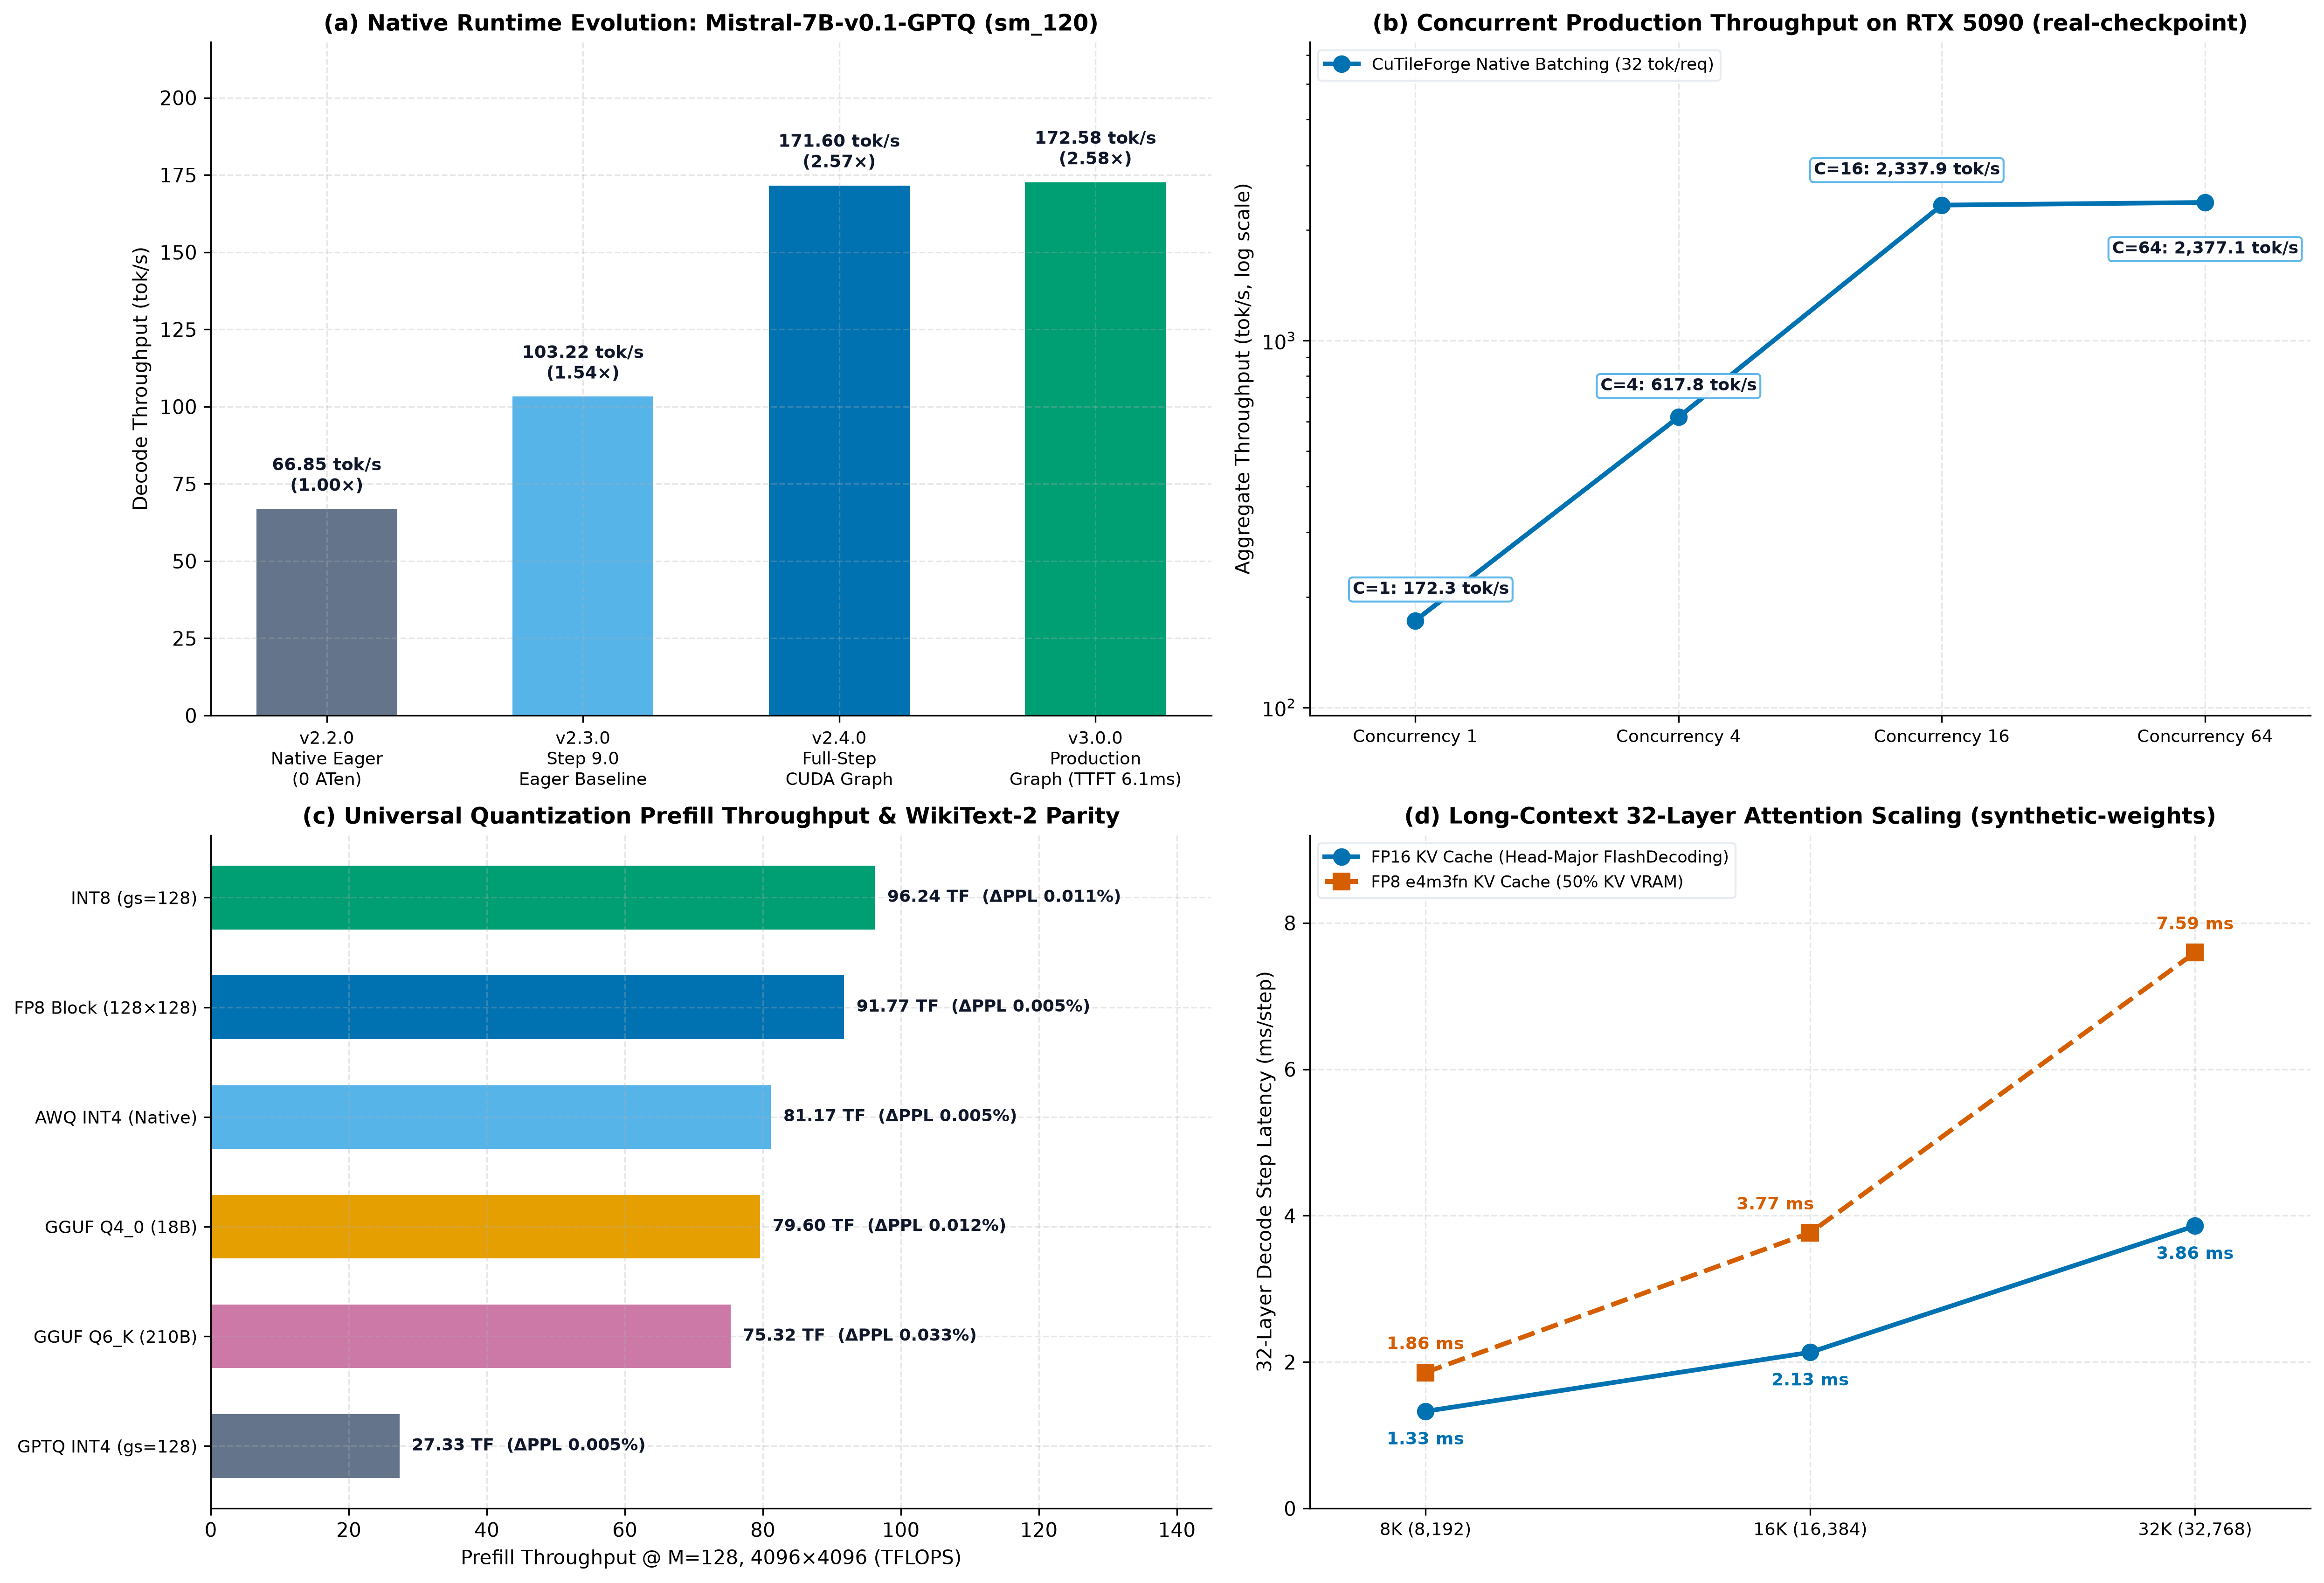
CuTileForge v3.0.0: Native tile-fusion compiler & universal quantization engine on NVIDIA CuTile. Zero-ATen CUDA-graph decode at 172 tok/s, 2,377 tok/s batch serving, 13 model families, 70B hybrid on a single 32 GB GPU (sm_89 ↔ sm_120).
Pure-CUDA inference engine + OpenAI-compatible server for LLaDA2.2-mini (16B MoE diffusion LLM) on Jetson Orin Nano Super 8GB
Compare GPTQ, AWQ, RTN, SmoothQuant and FP8 quantization on Qwen3-0.6B with LLM Compressor: model size, perplexity, speed and output quality against the BF16 base model.
CUDA-to-MLX GPTQ calibration campaigns with pinned models, corpora, and receipts
Using vLLM compressor to quantize Qwen3-0.6B using GPTQ to W4A16
GPU-accelerated LLM inference benchmarking suite covering GGUF, AWQ, and GPTQ quantization formats with TensorRT-LLM integration stubs. Includes latency/throughput metrics dashboard and Docker + Kubernetes deployment configs.