rag-evaluation


future-agi
Open-source, end-to-end platform for evaluating, observing, and improving LLM and AI agent applications. Tracing · Evals · Simulations · Datasets · Gateway · Guardrails. Self-hostable. Apache 2.0.
- 2.3k
- Python
- Apache-2.0
- 13 h ago

haiku.rag
Agentic RAG for local and self-hosted document search: hybrid retrieval, reranking and multimodal RAG on embedded LanceDB, with Docling parsing and an MCP server
- 666
- Python
- MIT
- 2 d ago



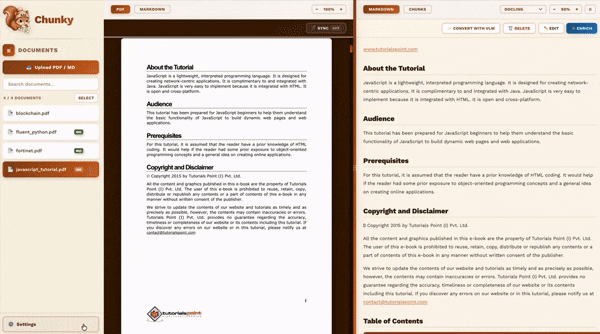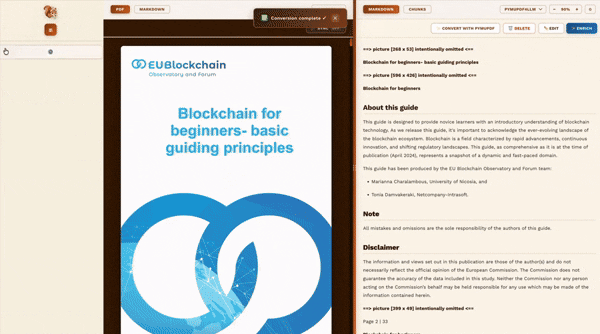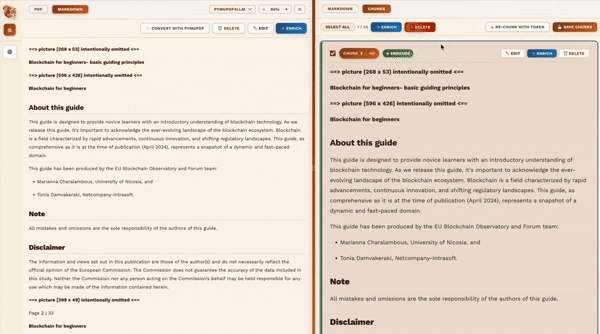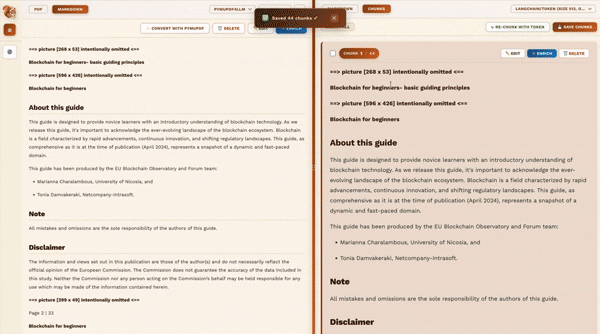
chunky
A local, open-source visual workspace for RAG document preparation: inspect PDF conversion, refine Markdown, compare chunking strategies, and enrich chunks before indexing.
- 233
- Python
- MIT
- 11 d ago

lasagna
Swap one RAG pipeline stage, hold the rest fixed, and measure whether the gain survives composition. The framework behind "Retrieval Augmented Generation Compositionality": 450 configurations, eight benchmarks, corpora from 5K to 200K documents.
- 37
- Python
- Apache-2.0
- 17 h ago

oh-my-knowledge
OMK helps people and agents build, maintain, and reuse valuable knowledge from real work and collaboration, with readable content, traceable sources, and revision history for future tasks.
- 25
- TypeScript
- MIT
- 2 d ago

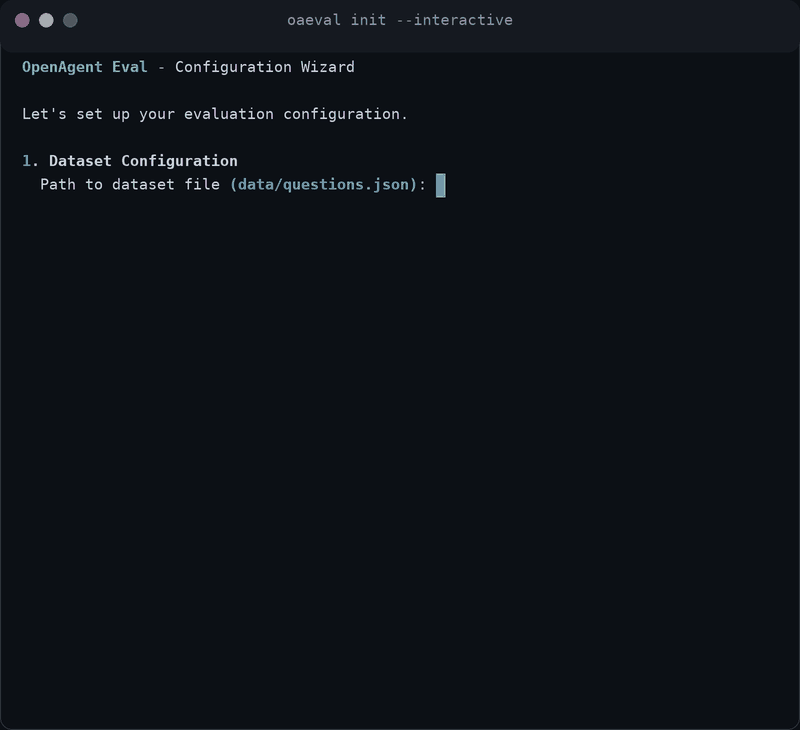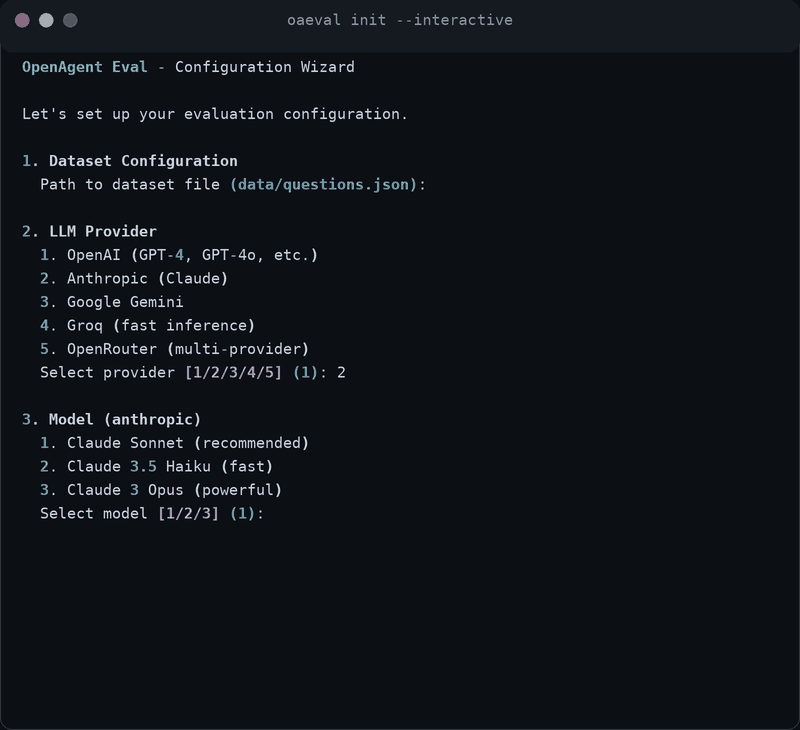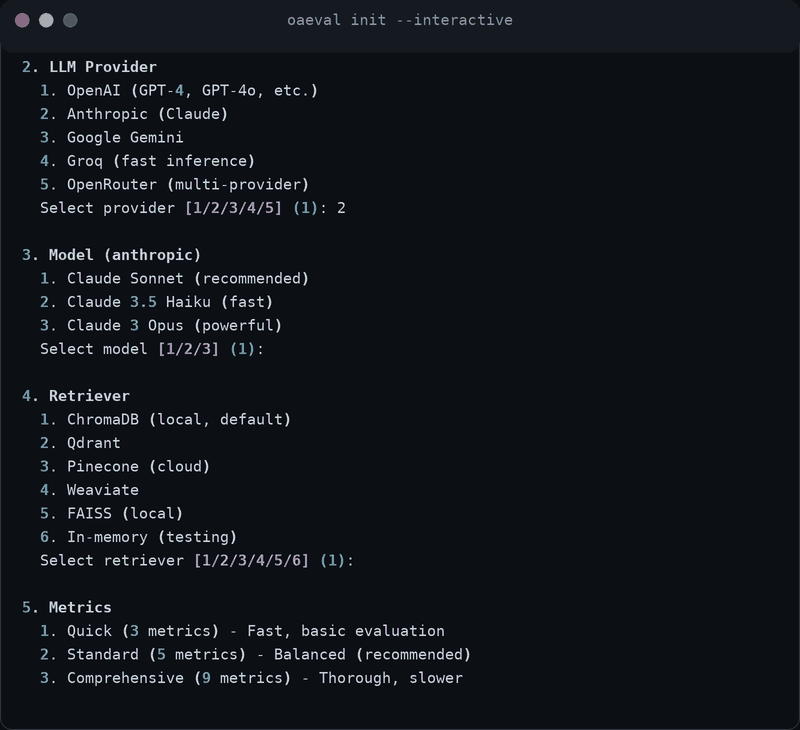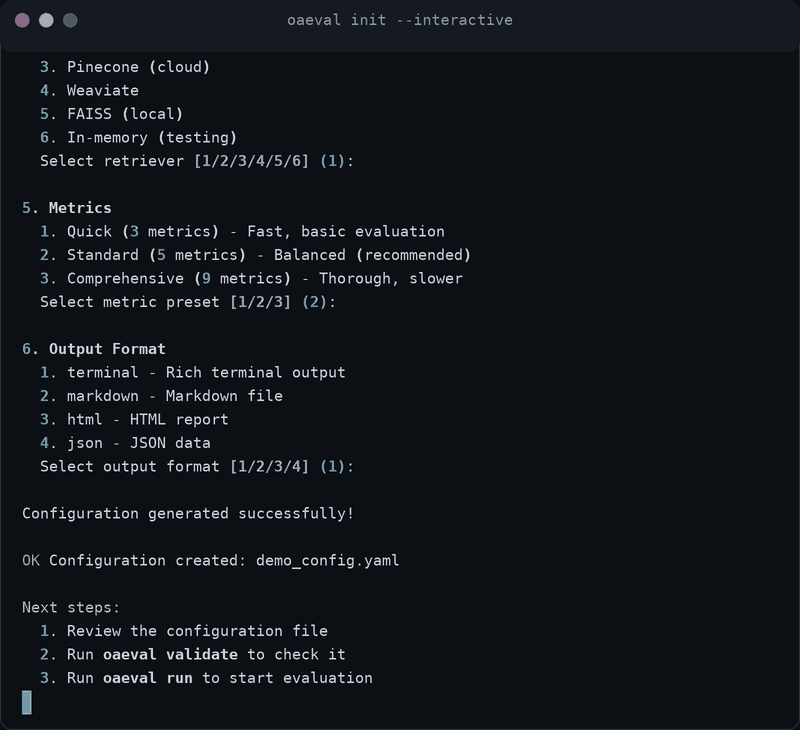
openagent-eval
Local-first evaluation framework for RAG systems and AI Agents. 18+ metrics, CLI + SDK, framework-agnostic. The pytest of AI evaluation.
- 16
- Python
- Apache-2.0
- 3 d ago

Learn_RAG_from_Scratch_LLM
Learn Retrieval-Augmented Generation (RAG) from Scratch using LLMs from Hugging Face and Langchain or Python
- 13
- Jupyter Notebook
- MIT
- 22 mo ago

Production-grade-RAG
Production-grade Retrieval-Augmented Generation (RAG) API built with FastAPI, LangChain, OpenAI, and Qdrant.
- 14
- Python
- 8 mo ago

ai-evaluation-tools
The comprehensive list of AI evaluation tools: 300+ open-source and commercial LLM evaluation frameworks, platforms, benchmarks, observability, red teaming, and guardrails — for LLMs, RAG, and AI agents.
- 16
- Python
- CC0-1.0
- 4 mo ago

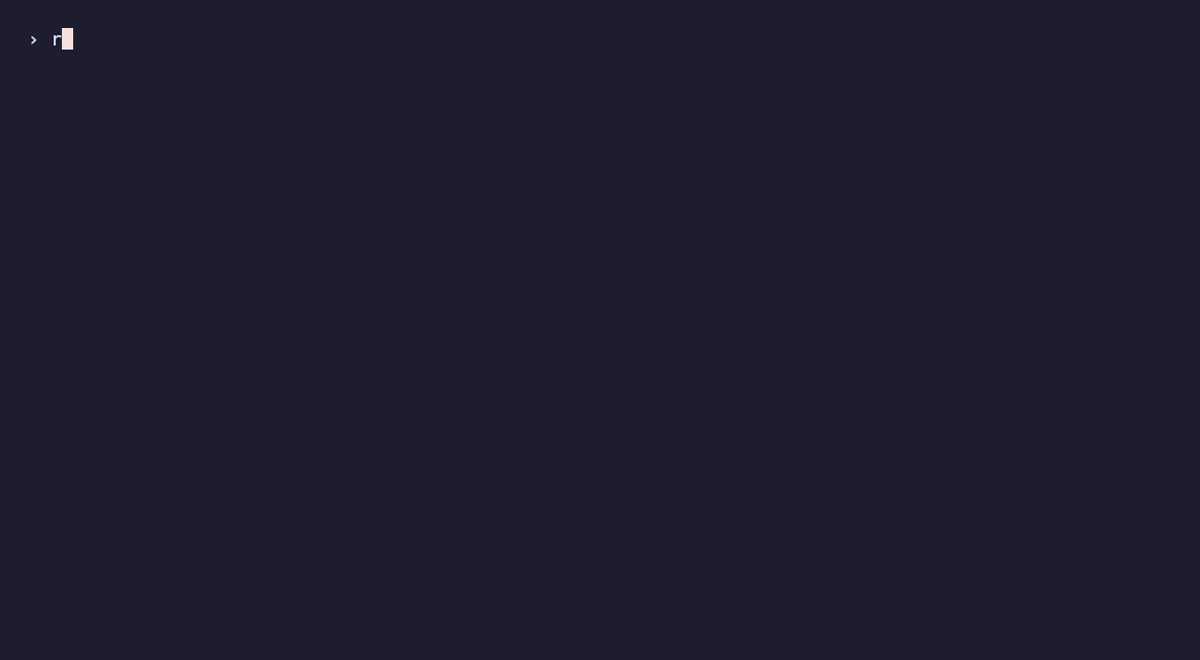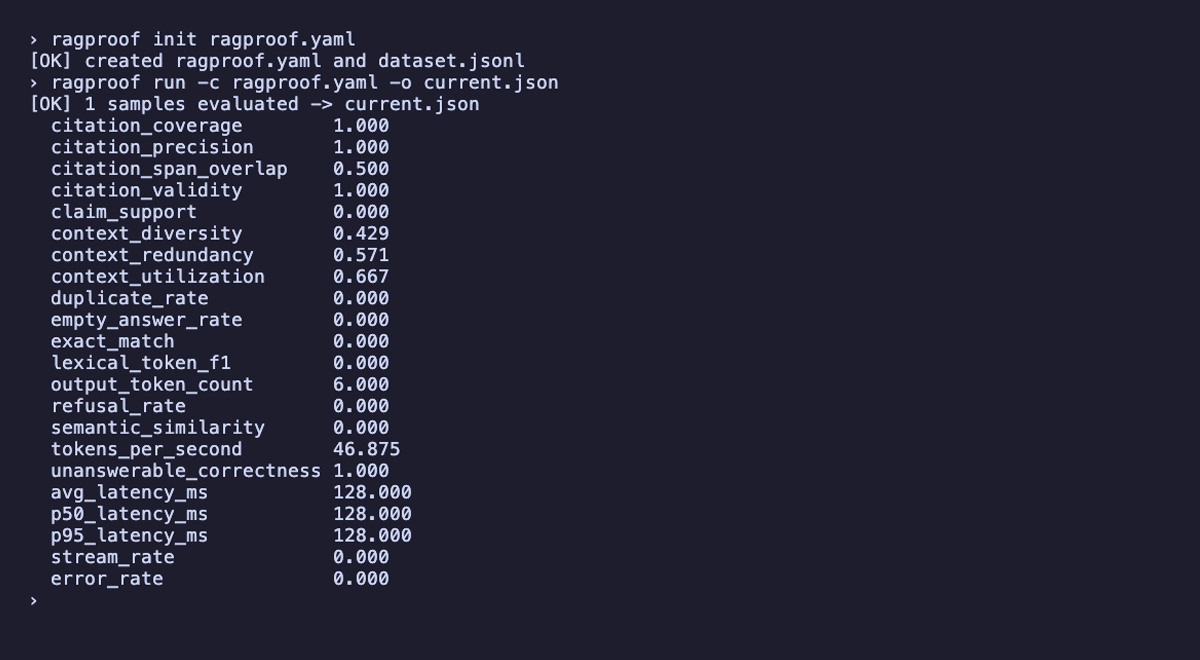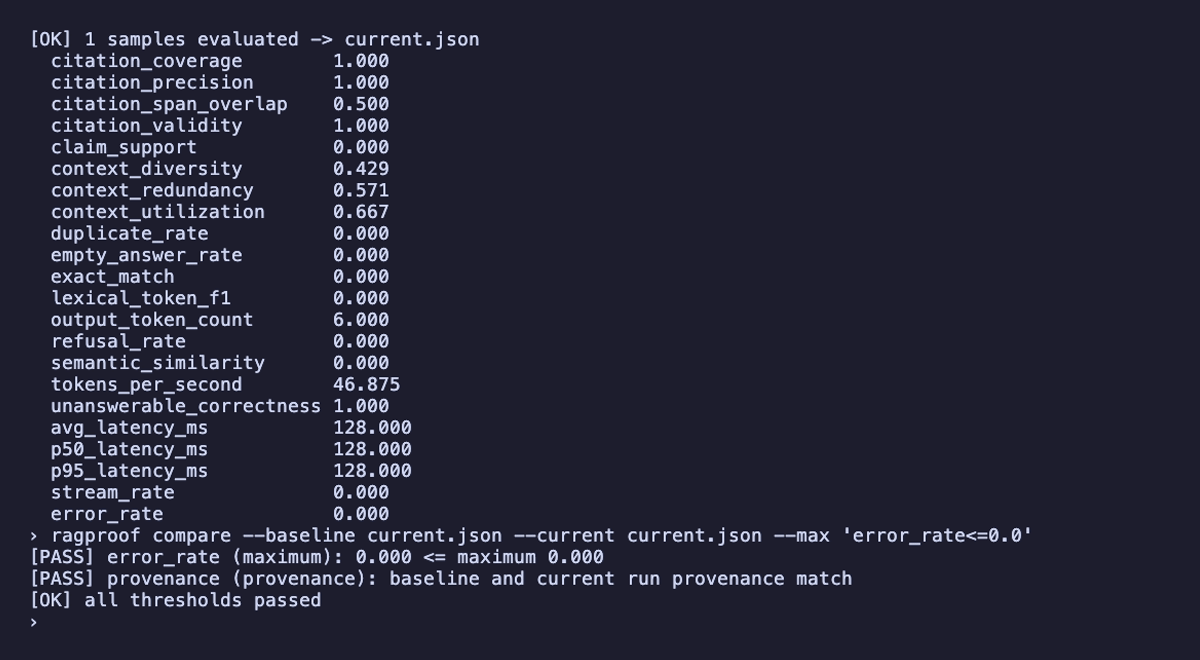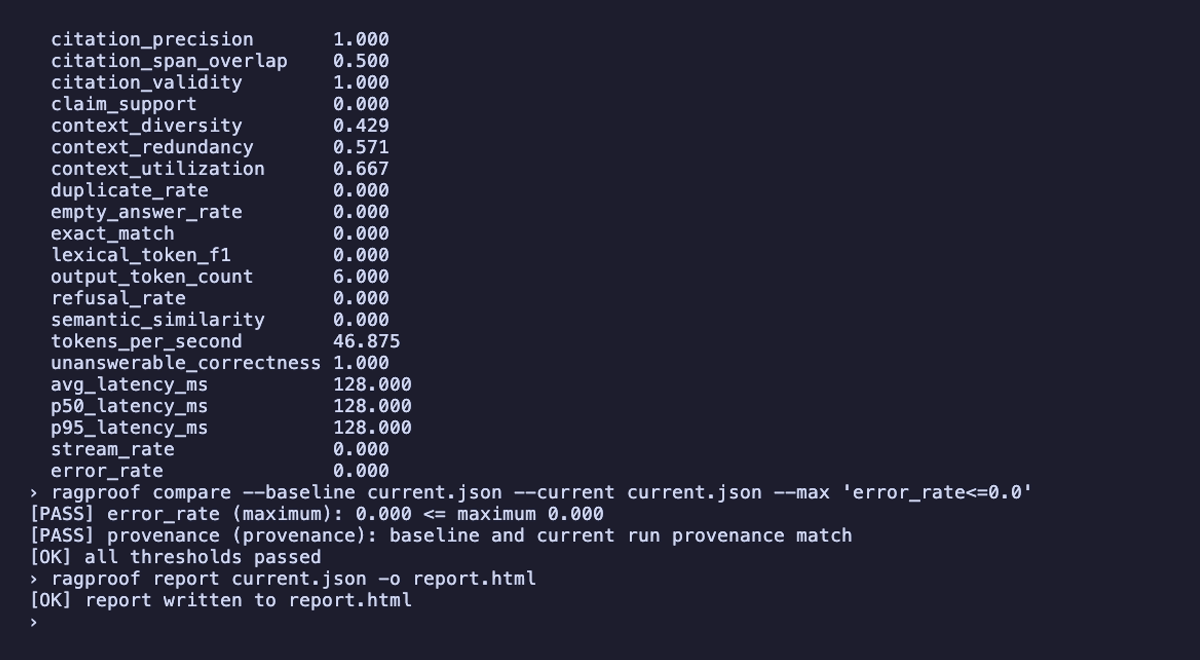
ragproof
Framework-agnostic RAG evaluation & regression-testing CLI — recall@k, MRR, faithfulness, citation metrics, CI gate
- 3
- Python
- MIT
- 3 mo ago

rag-retrieval-tools
The comprehensive list of RAG and retrieval tools: 200+ vector databases, search frameworks, embeddings, rerankers, parsers, pipelines, benchmarks, and evaluation tools.
- 3
- Python
- CC0-1.0
- 4 mo ago
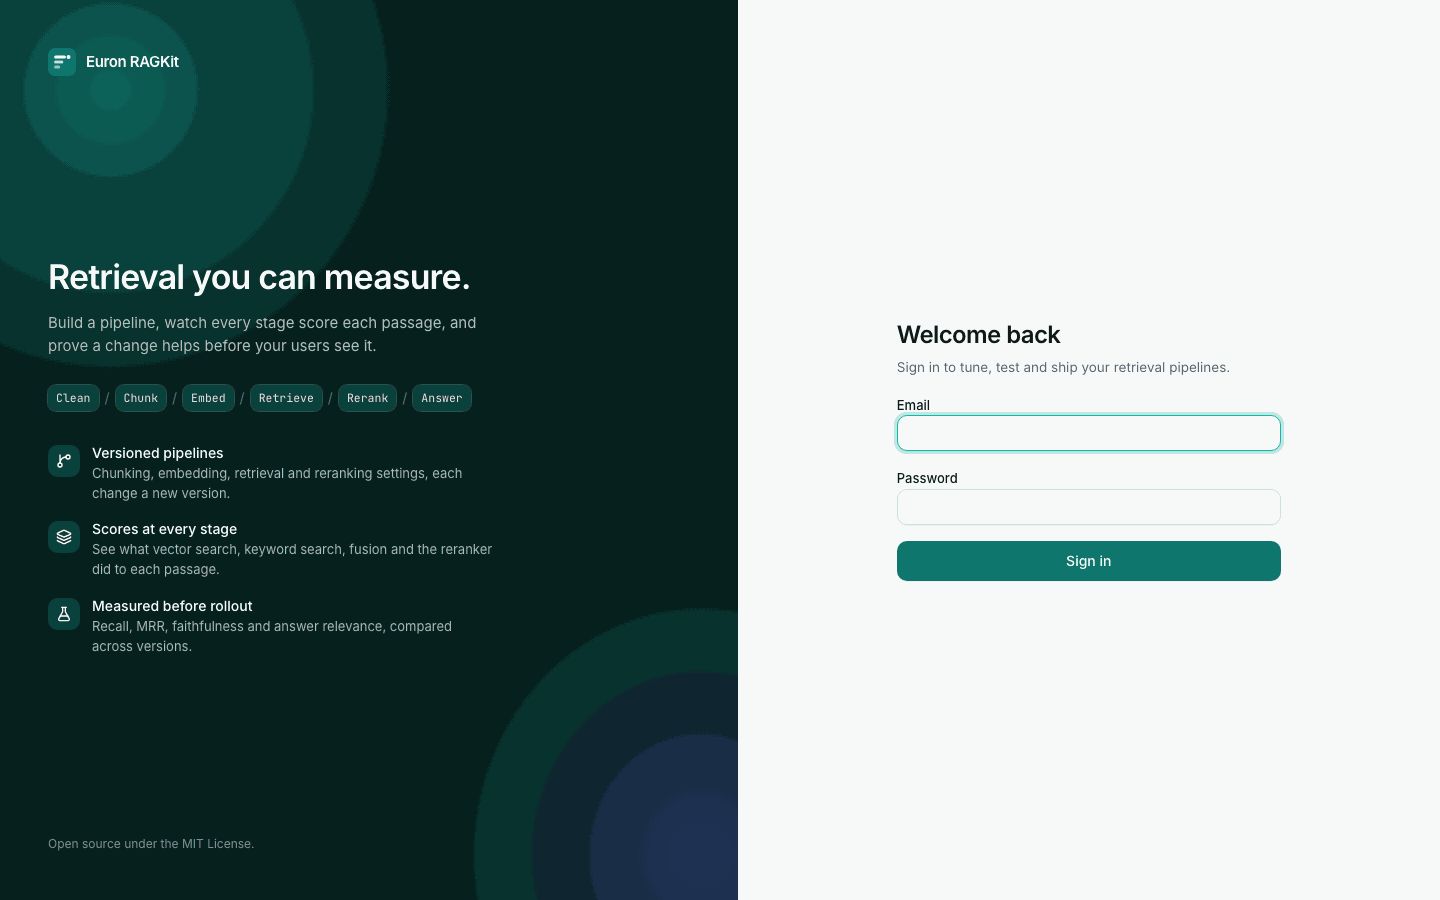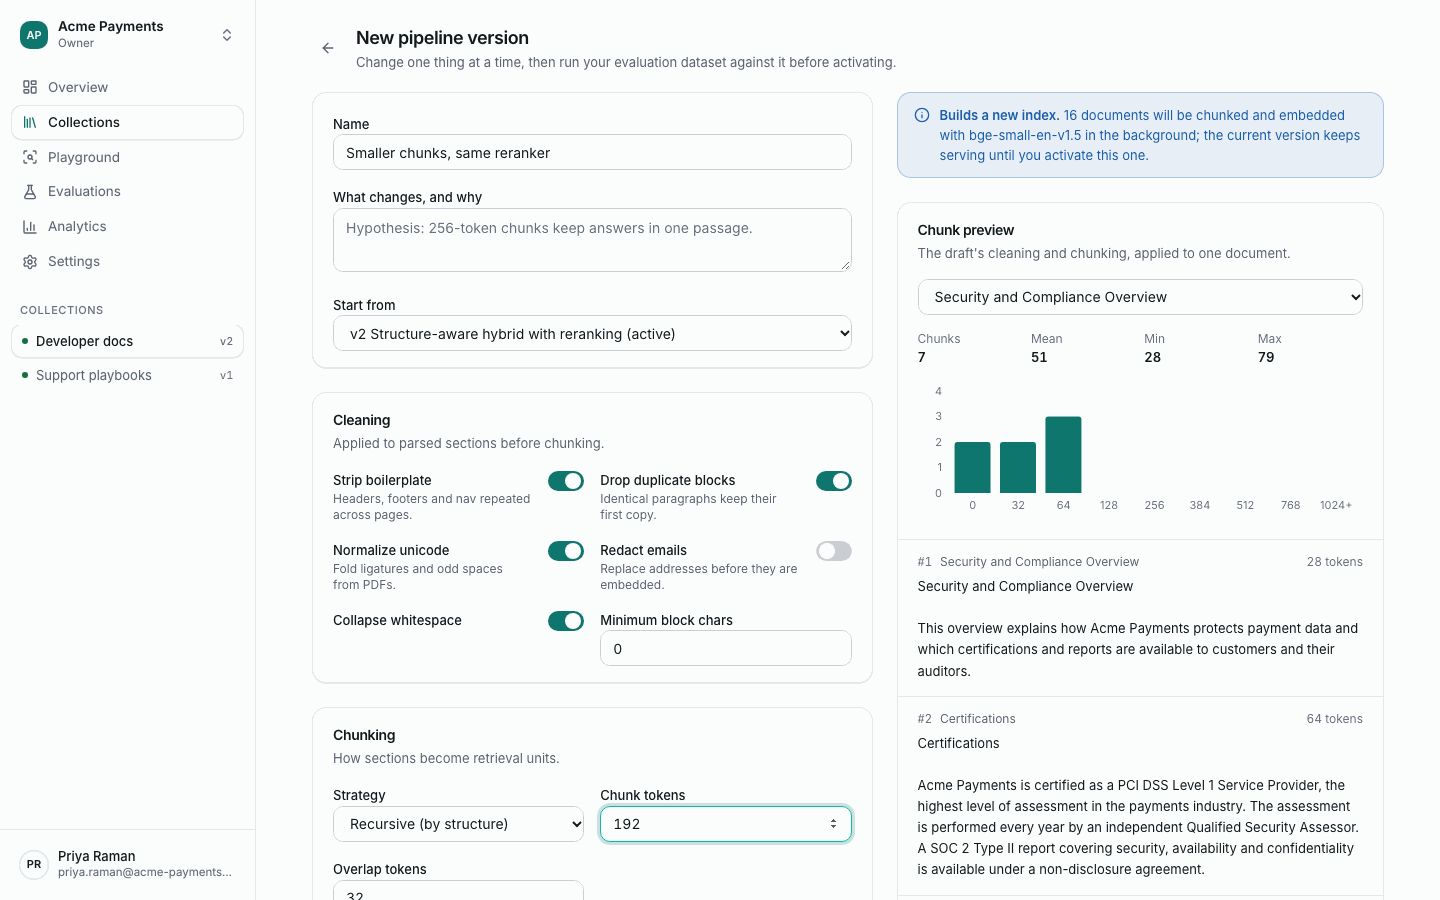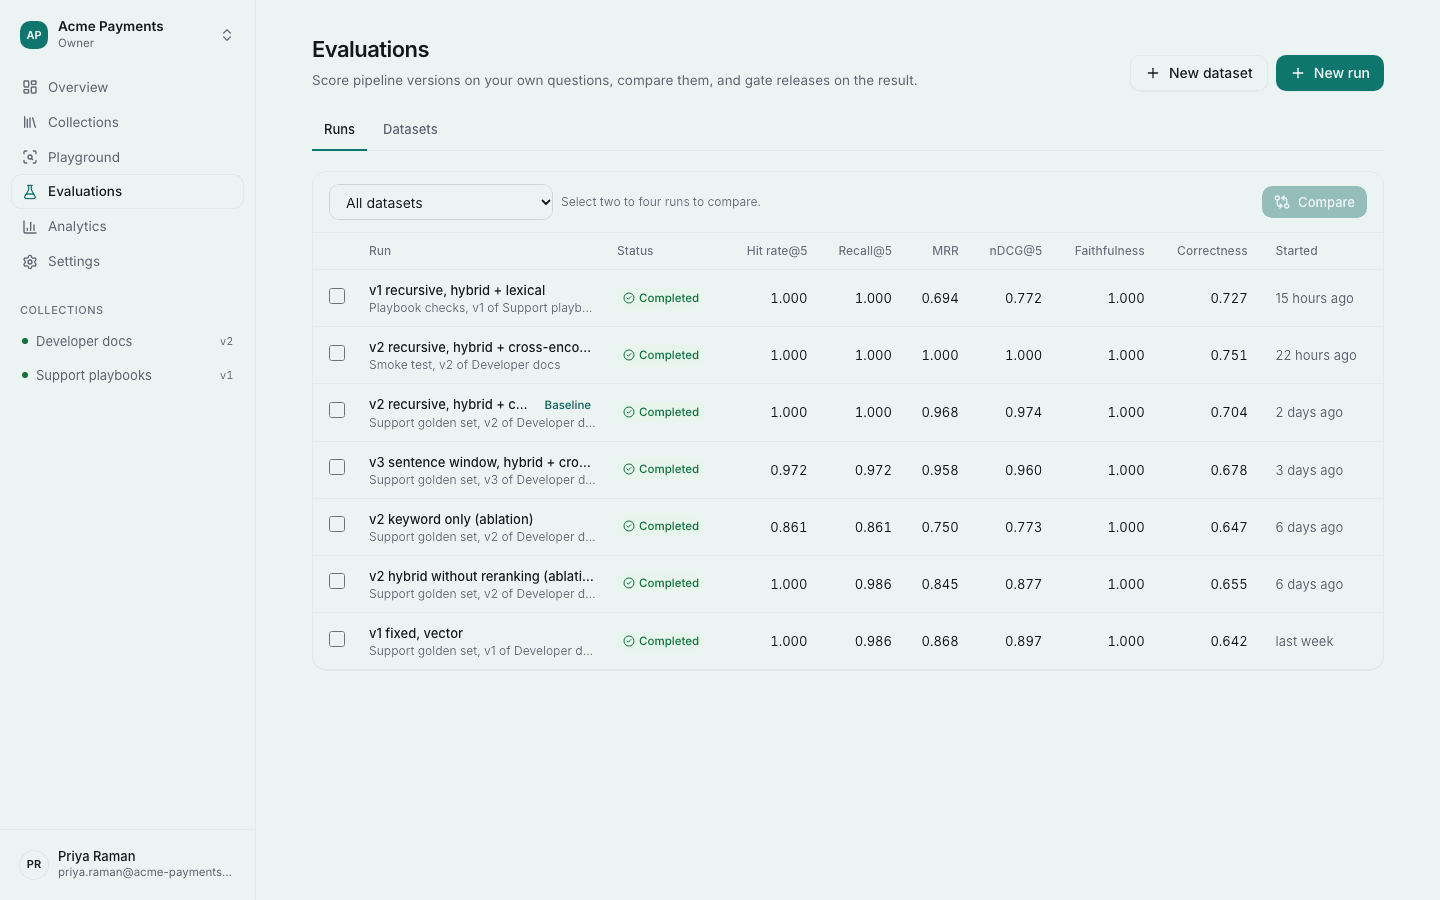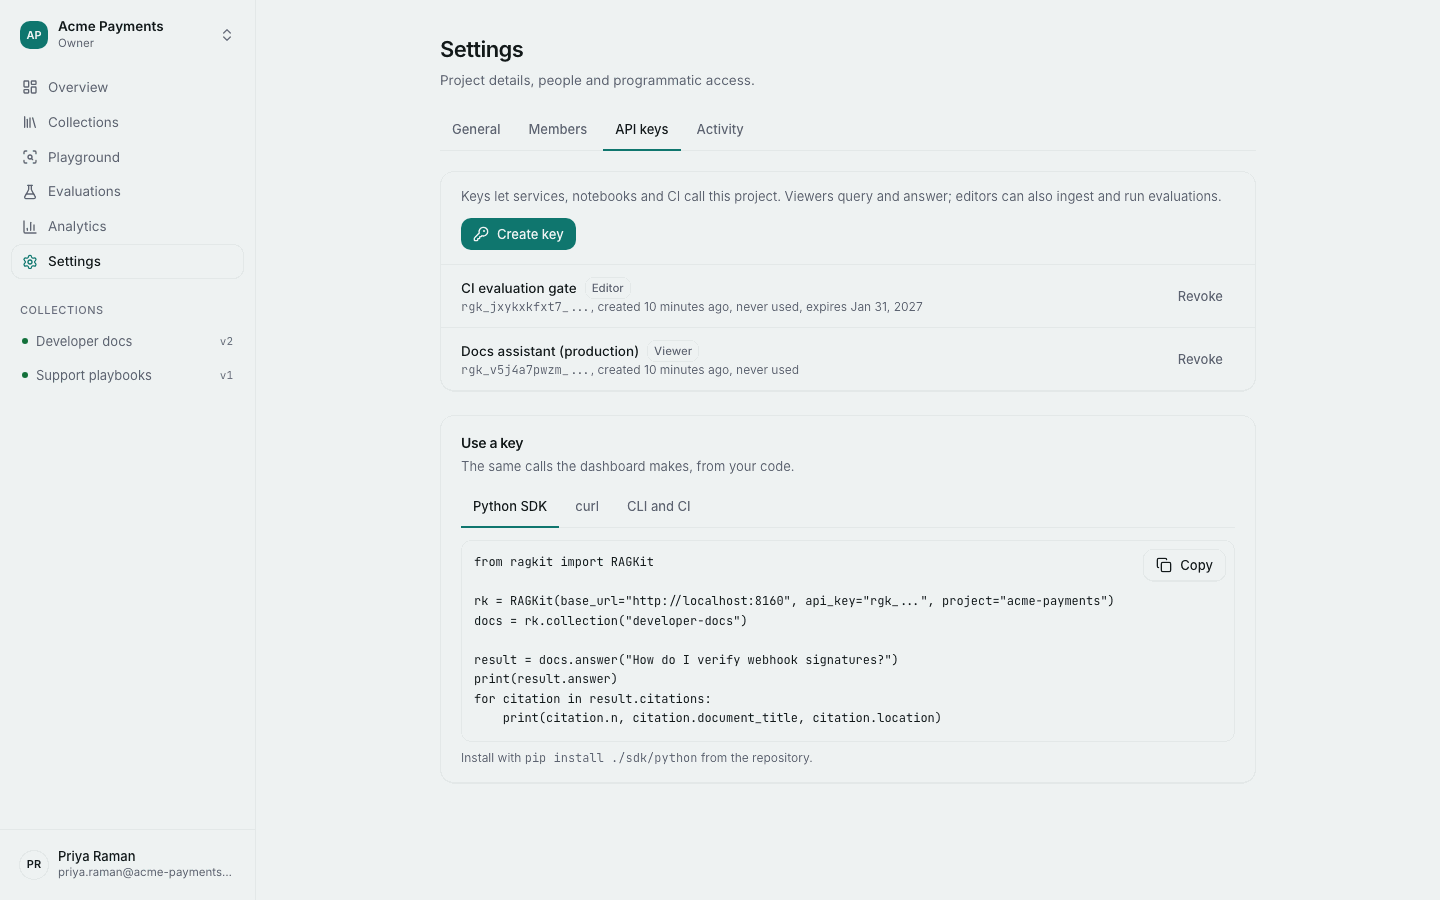
euron-rag-kit
Production RAG toolkit: ingestion pipelines, hybrid retrieval with reranking, cited answers and an offline evaluation suite with regression gates. Terraform for AWS, Floci for local.
- 2
- Python
- MIT
- 3 wk ago

LLM-Evaluation-Intermediate-to-Advanced
hands-on repository covering intermediate to advanced techniques for evaluating Large Language Models (LLMs). Explores evaluation methodologies, performance metrics, benchmarking, hallucination detection, response quality assessment, RAG evaluation, model comparison, and automated evaluation workflows using Python & modern LLM evaluation framework.
- 2
- Python
- 5 d ago

AI-RAG-Intelligent-System-MMI-
The project features a hybrid semantic search pipeline, Japanese-to-English translation caching, Server-Sent Events (SSE) streaming, and a bilingual conversation memory engine. It is accessible via both a rich terminal-based CLI chatbot and a premium Web UI Dashboard.
- 2
- Python
- 6 mo ago

MLflow_with_RAG
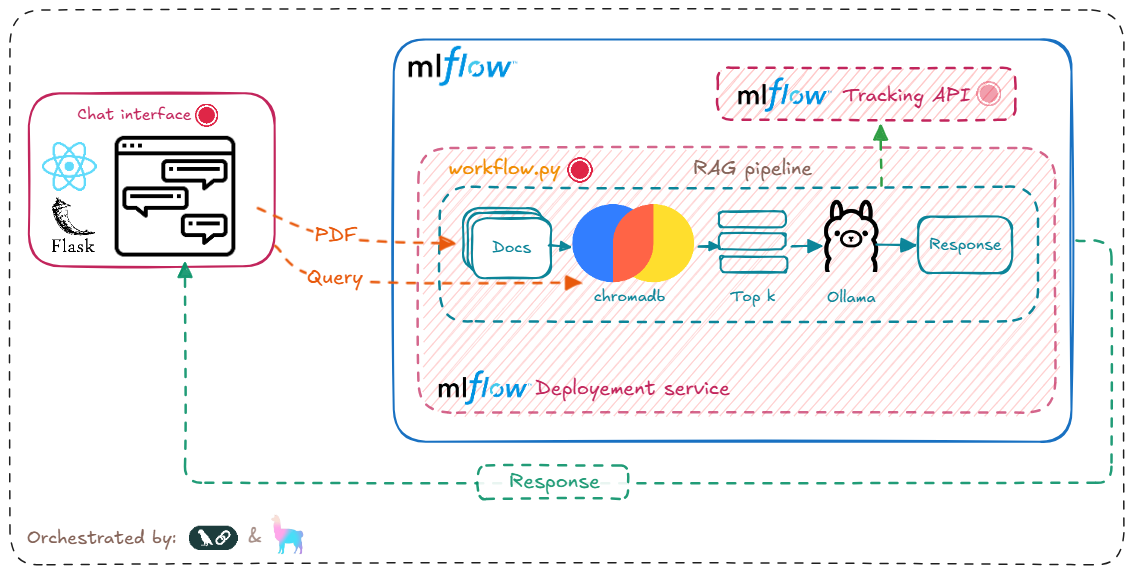
Using MLflow to deploy your RAG pipeline, using LLamaIndex, Langchain and Ollama/HuggingfaceLLMs/Groq
- 2
- Python
- 22 mo ago

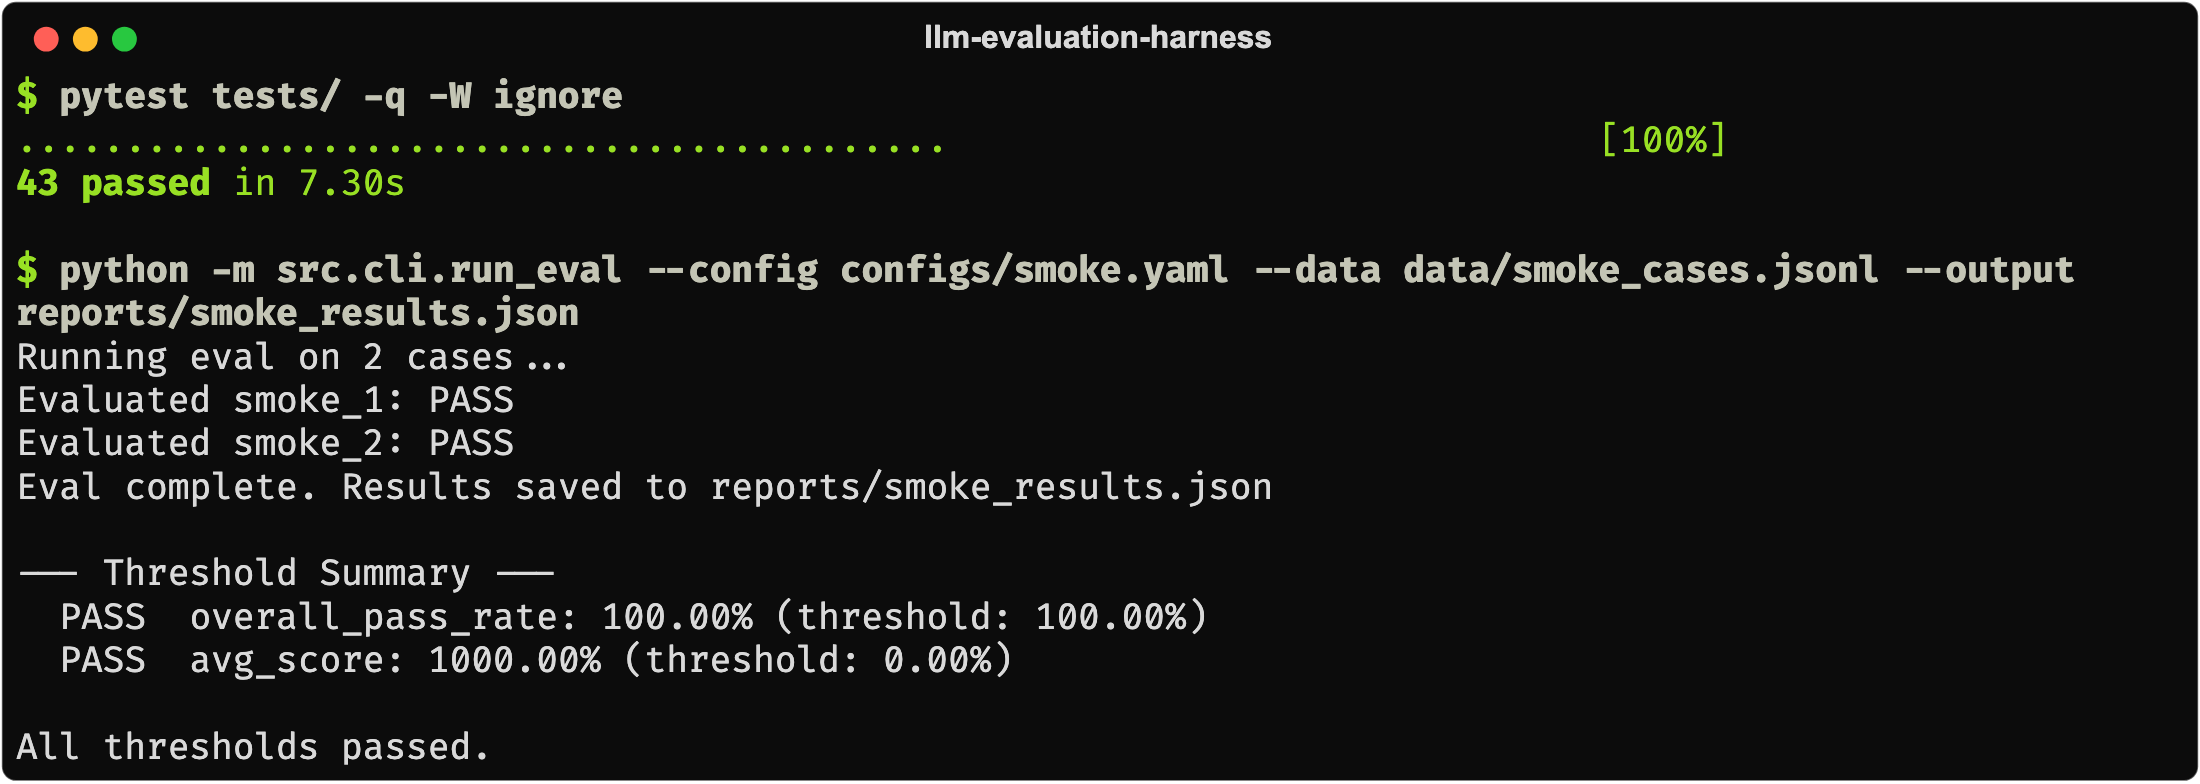
llm-evaluation-harness
LLM evaluation harness for regression testing LLM and RAG systems: rule checks, semantic similarity and LLM-as-a-judge scoring from a YAML config, with baseline vs candidate run diffs. Python, with a mock adapter so CI needs no API key.
- 1
- Python
- MIT
- 4 d ago

ai-evals-skills
Teach your coding agent to build AI evals the aievals.co way: a Claude Code skill, Cursor and AGENTS.md rules, and Python and TypeScript starters for error analysis, calibrated LLM judges and CI release gates.
- 1
- Python
- MIT
- 9 d ago

Complete-Corrective-RAG-CRAG
A comprehensive Corrective Retrieval-Augmented Generation (CRAG) learning repository covering retrieval quality evaluation, document relevance grading, knowledge refinement, web search fallback, corrective retrieval workflows, and context-aware answer generation for building more reliable and accurate LLM applications using Python.
- 1
- Jupyter Notebook
- MIT
- 5 d ago
ai-quality-evals-lab
A practical, AI evalution repo covering LLMs, RAG, MCP, skills, agents, multi-agent systems, security, reliability evaluations
- 1
- Python
- MIT
- 9 d ago

Complete-Naive-RAG
Covering Naive Retrieval-Augmented Generation (RAG), including document loading, text chunking, embedding generation, vector database integration, semantic search, context retrieval, and LLM-powered question answering using Python and modern GenAI frameworks.
- 1
- Jupyter Notebook
- MIT
- 5 d ago
nace-haystack
Drex decision models for Haystack: route text, classify documents and evaluate RAG answers
- 1
- Python
- Apache-2.0
- 3 wk ago

rag-evaluation-with-ragas
Evaluation-driven RAG system using RAGAS, retrieval metrics, behavioral stress testing, holdout validation, diagnostics and reliability analysis.
- 0
- Python
- 7 wk ago

evalpilot
Agent evals on autopilot: find quality bugs in your AI agent, ship a targeted fix, and prove it on a held-out set. Zero-dependency Agent Skill + CLI.
- 0
- Python
- MIT
- 4 mo ago
