DiT-Extrapolation
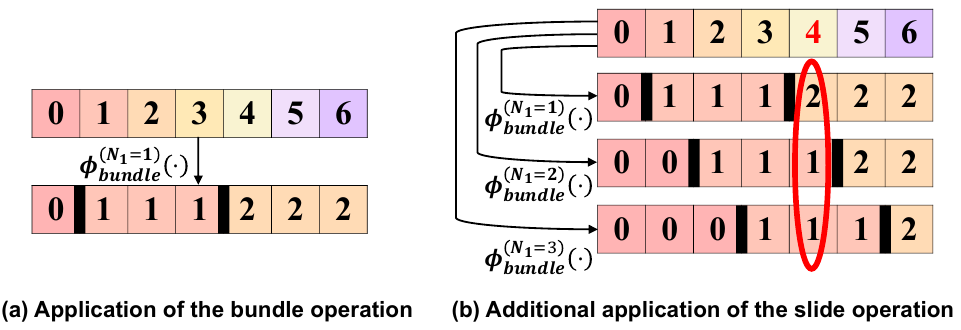
Official implementation for "RIFLEx: A Free Lunch for Length Extrapolation in Video Diffusion Transformers" (ICML 2025) , UltraViCo (ICLR 2026) and UltraImage
- 834
- Python
- Apache-2.0
- 6 mo ago
Official implementation for "RIFLEx: A Free Lunch for Length Extrapolation in Video Diffusion Transformers" (ICML 2025) , UltraViCo (ICLR 2026) and UltraImage
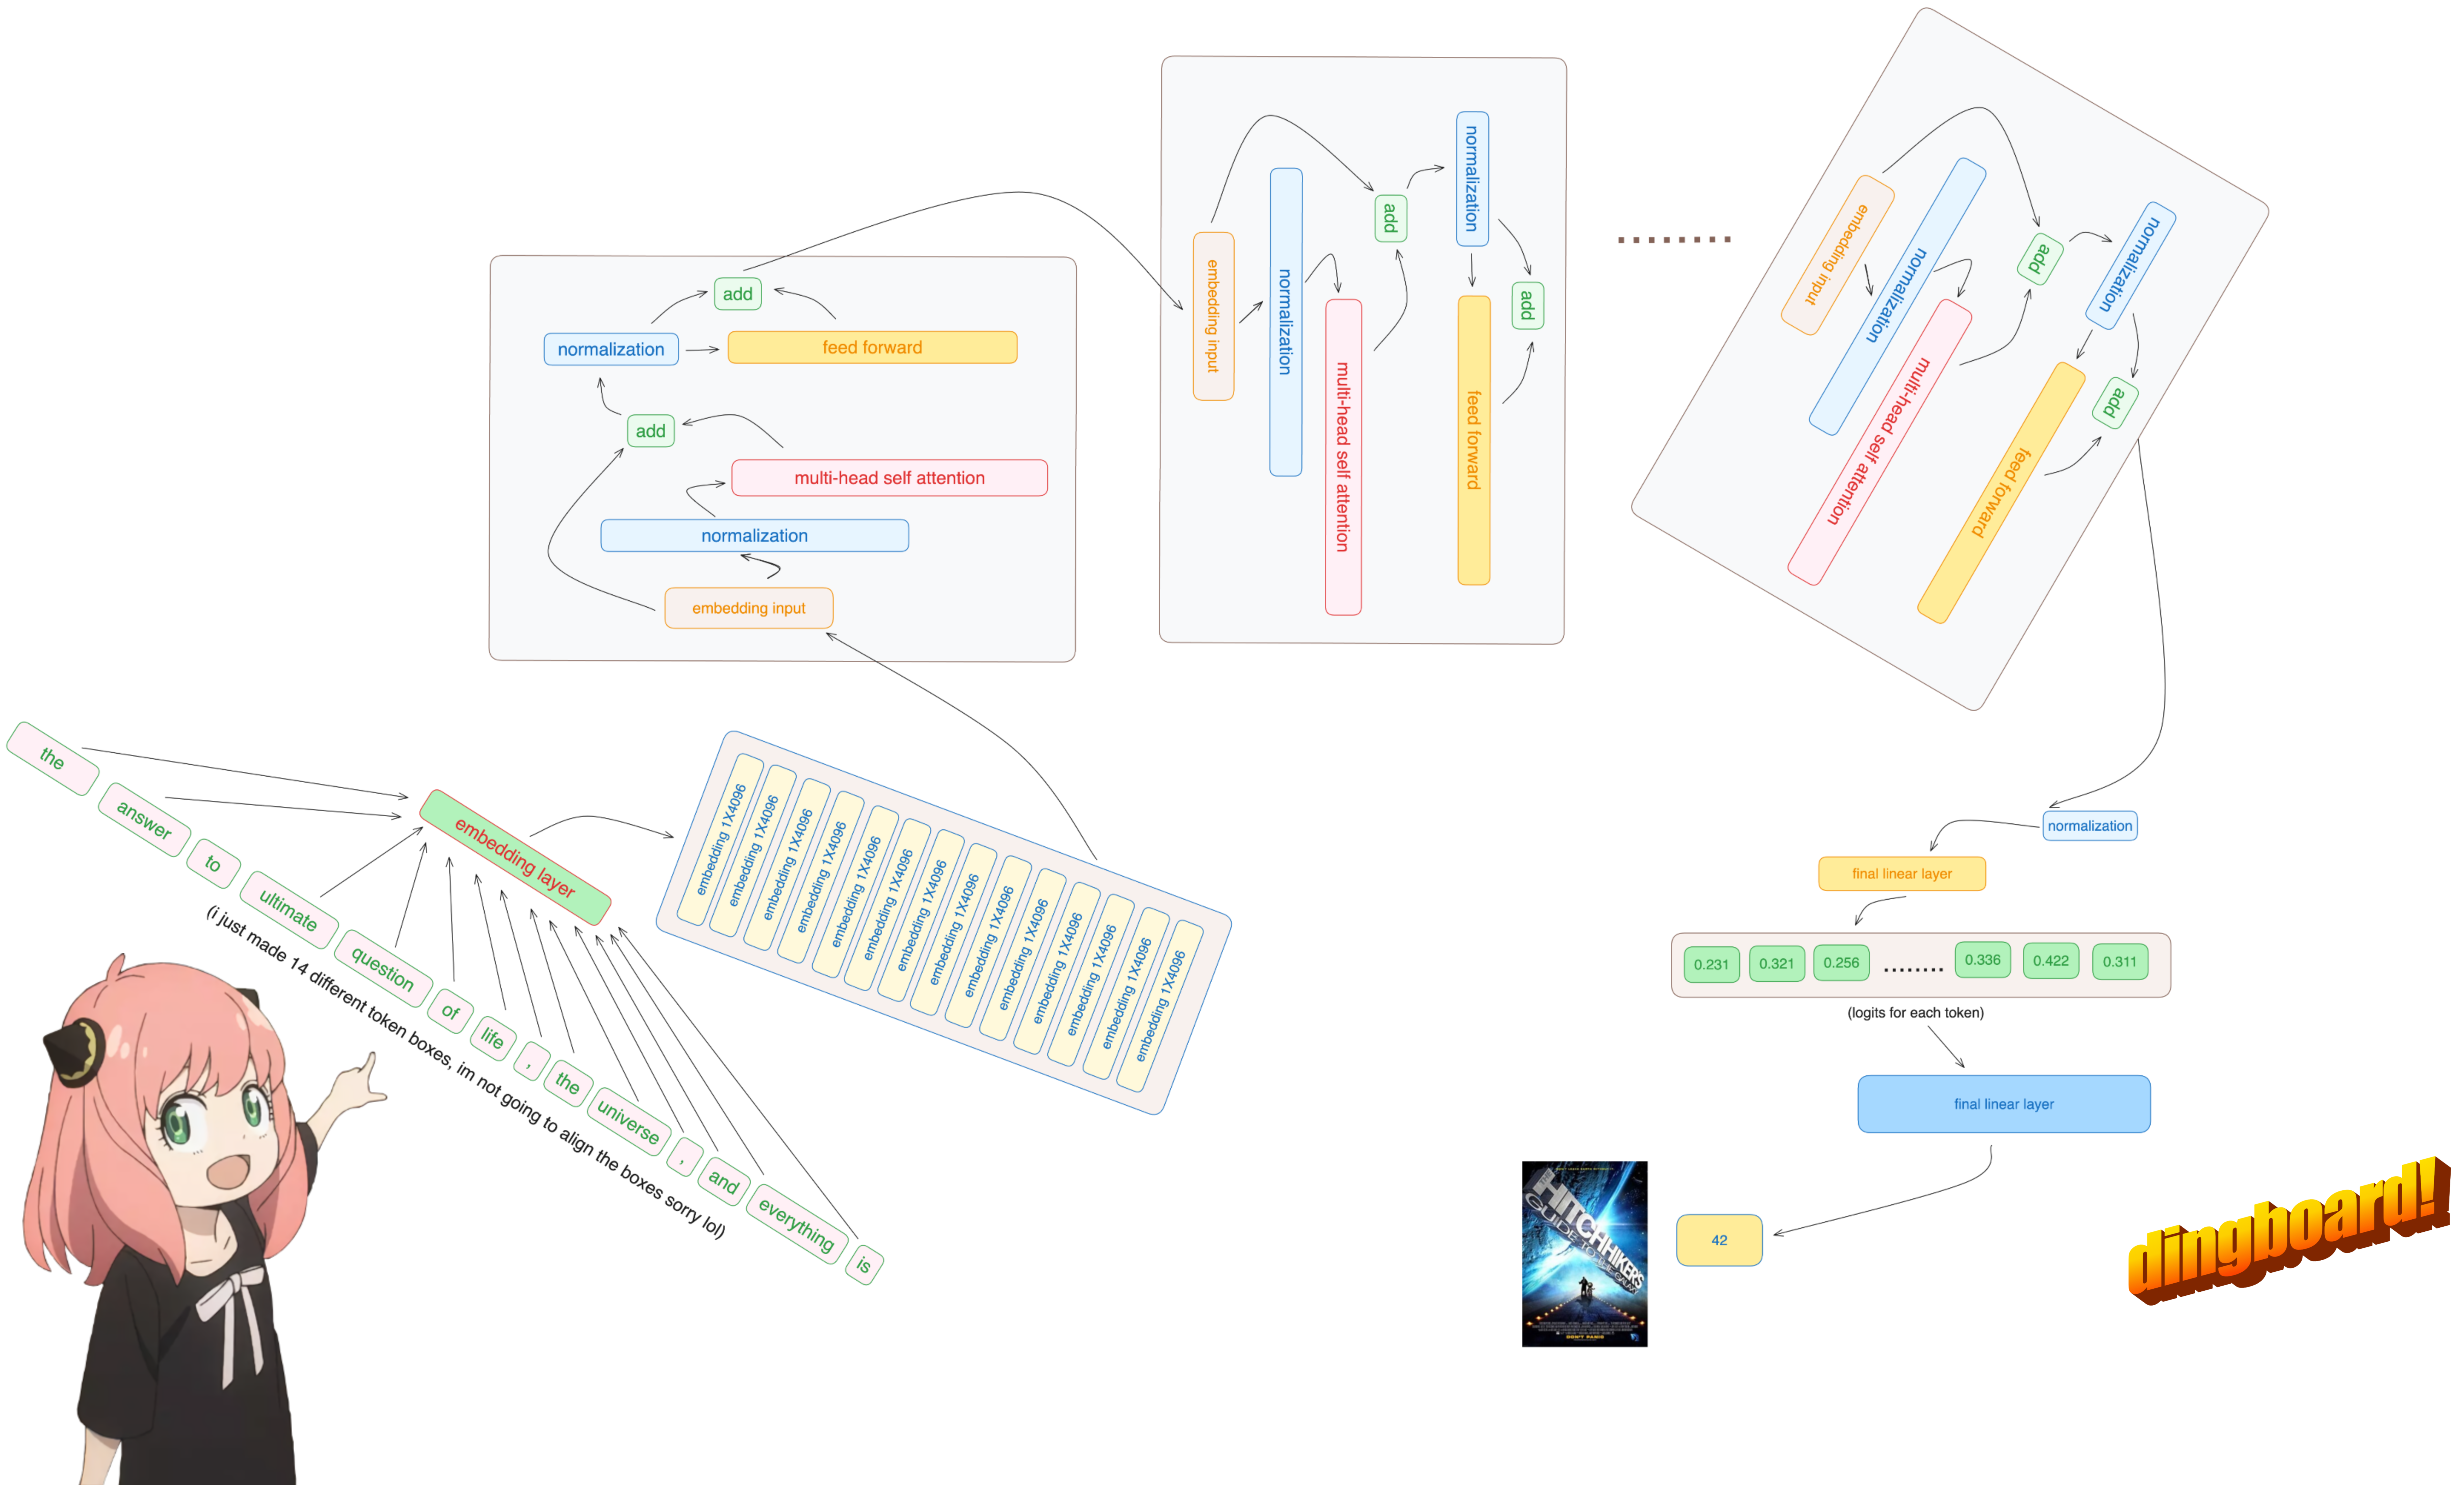
Achieve the llama3 inference step-by-step, grasp the core concepts, master the process derivation, implement the code.
:ghost: Utilities for analyzing Bayesian models and posterior distributions
[ECCV 2026] Official implementation of "HRDiT: Training-Free High-Resolution Image Generation with Off-the-Shelf Diffusion Transformer Models"
从 MiniMind 源码读起,再延伸到现代大模型技术体系的中文学习笔记。主线逐行精读预训练 / SFT / DPO / PPO / GRPO 与训练机制;附录 17 篇进阶卷覆盖量化、投机解码、RLHF 全景、模型代际史等 MiniMind 没涉及、但进阶绕不开的主题。
This repository contains an implementation of the LLaMA 2 (Large Language Model Meta AI) model, a Generative Pretrained Transformer (GPT) variant. The implementation focuses on the model architecture and the inference process. The code is restructured and heavily commented to facilitate easy understanding of the key parts of the architecture.
A wrapper around Text for fast line/column navigation and logarithmic concatenation
249M-param MoE transformer built from scratch in PyTorch. GQA, RoPE, SwiGLU, sparse MoE with 3 aux losses, AMP training loop no Trainer abstractions. Architecture mirrors LLaMA/Mistral/Mixtral decisions, fully inspectable.
PyTorch implementation of RoFormer's Rotary Position Embeddings (RoPE) with comprehensive tests, benchmarks, and documentation. Used in LLaMA, PaLM, GPT-NeoX.
CPU-first long-context KV memory optimization with deterministic page regeneration and exact folded attention.
Open source implementation of AMALIA: A Fully Open Large Language Model for European Portuguese
Hackable PyTorch template for decoder-only transformer architecture experiments. Llama baseline with RoPE, SwiGLU, RMSNorm. Swap components, train, compare
Pure PyTorch + 🤗 Transformers reimplementation of Megalodon (CEMA + chunked attention) - readable, hackable, no CUDA kernels required
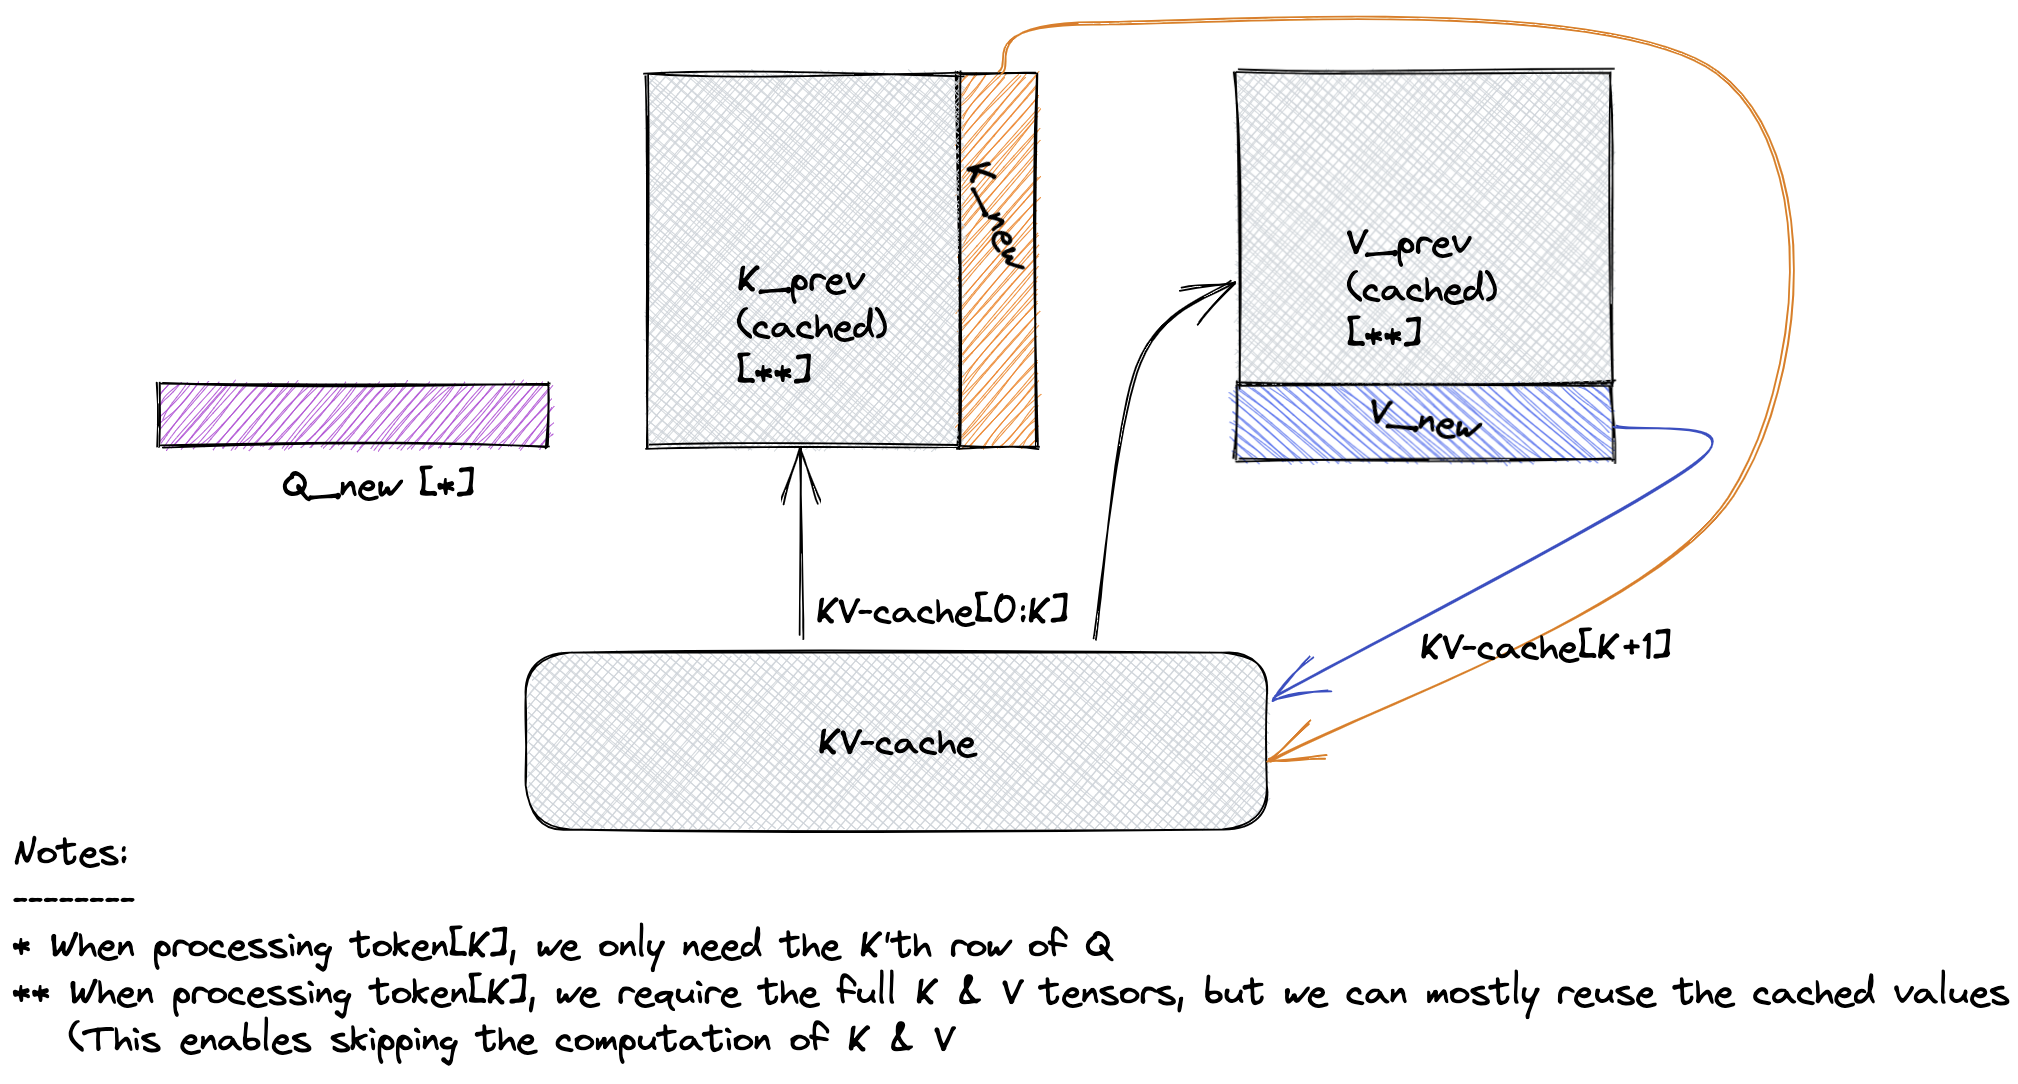
A 66M parameter decoder-only transformer language model implemented from scratch in PyTorch. Features a custom SentencePiece tokenizer, RoPE positional embeddings, SwiGLU feed-forward network, per-layer KV cache for efficient autoregressive inference, and a Svelte-based streaming chat interface.
Decoder-only Assamese LM built from scratch — RMSNorm/RoPE/GQA/SwiGLU, 74.8M params. Includes tokenizer training, data pipeline, training loop, evaluation, and attention visualization. Foundation model for NodiAI, a privacy-focused Assamese document-assistant for schools, clinics, and legal offices
Untying Prefill and Decode Loops in Looped Language Models: a loop adapter lets a looped (recurrent-depth) LM prefill with m loops and decode with n. Ouro, SenseNova-Loop, Lev; every number recomputable.
Persistent text rope with insert/delete/replace, iteration (app/fold/map), line helpers, and Fibonacci rebalancing in pure Standard ML