skypilot
The AI Compute Platform for frontier teams. SkyPilot turns fragmented AI compute into one AI supercomputer, so frontier AI teams build custom intelligence faster.
- 11k
- Python
- Apache-2.0
- 1 d ago
The AI Compute Platform for frontier teams. SkyPilot turns fragmented AI compute into one AI supercomputer, so frontier AI teams build custom intelligence faster.
Best practices & guides on how to write distributed pytorch training code
A WDL, CWL and Python API supporting easy-to-use workflow engine. It is scalable, efficient and cross-platform (Linux/macOS).
A unified orchestration layer for heterogeneous AI compute. It standardizes how to manage compute and run training and inference on GPU clouds, Kubernetes, VMs, or bare-metal clusters.
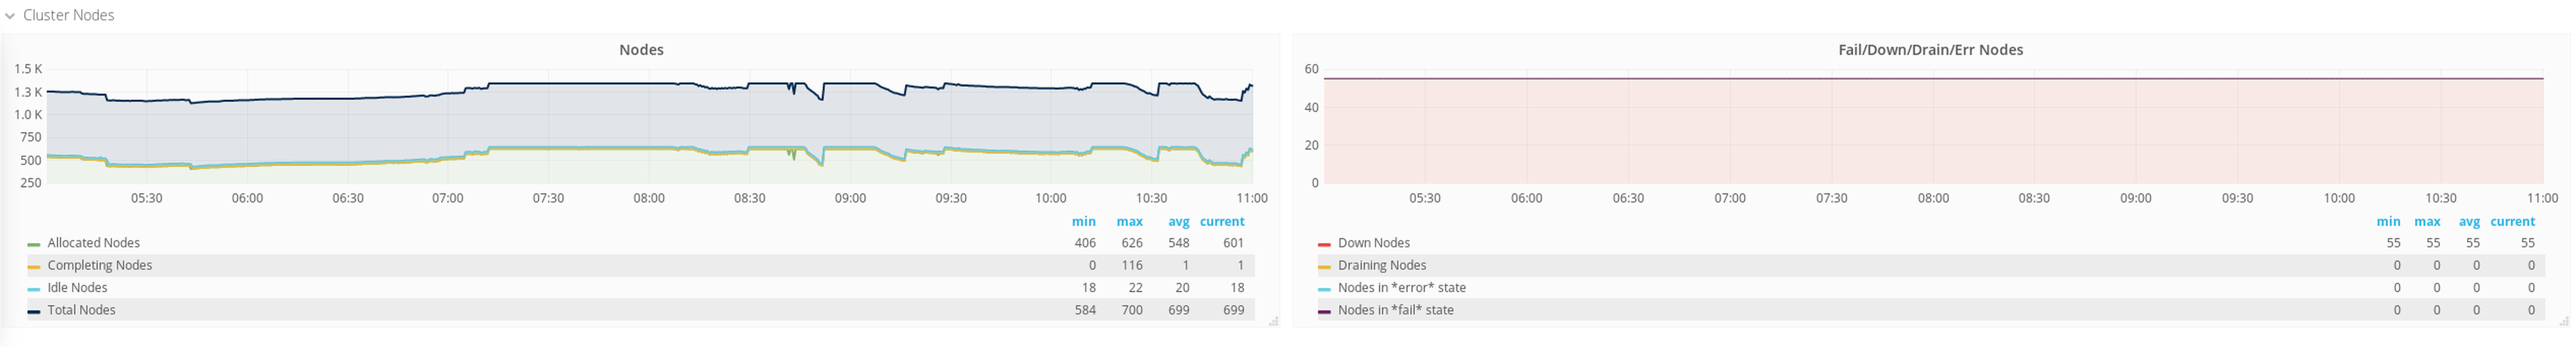
Prometheus exporter for performance metrics from Slurm.
TorchX is a universal job launcher for PyTorch applications. TorchX is designed to have fast iteration time for training/research and support for E2E production ML pipelines when you're ready.
Best practices, reference architectures, and examples for distributed AI training and inference on AWS.
A command line and Python toolkit featured artificial intelligence × ab initio for complex chemistry systems research.
A template for starting reproducible Python machine-learning projects with hardware acceleration. Find an example at https://github.com/CLAIRE-Labo/no-representation-no-trust
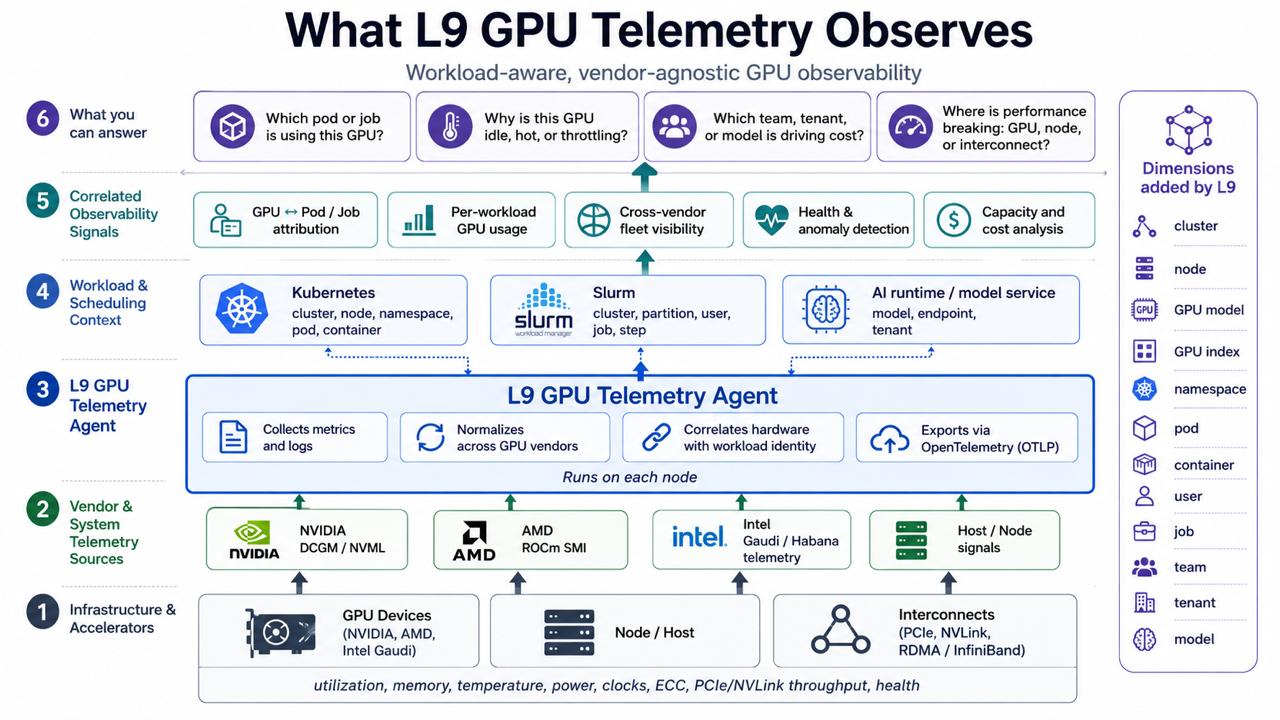
GPU Observability with workload attribution. One OTLP agent per node ties hardware metrics (NVIDIA, AMD, Intel Gaudi) to the K8s pod or Slurm job burning the GPU.
generate HPC scheduler systems jobs input scripts and submit these scripts to HPC systems and poke until they finish
Run many functions (adaptively) on many cores (>10k-100k) using mpi4py.futures, ipyparallel, loky, or dask-mpi. :tada:
Create and manage Amazon SageMaker HyperPod clusters, run distributed model training
Toolkit for launching and observing MaxText training on Slurm-managed GPU clusters
A simple Linux command-line utility which submits a job to one of the multiple GPU servers
A framework to performing benchmark testing on MiniZinc models, solvers, and/or the compiler itself.
Testing ray tune with slurm batch submission and optuna and wandb
Ensemble-based calibration of model parameters, from a laptop to an HPC cluster with the same code
Materials for a training on workflow tools and best practices for HPC.
Slides for a workshop/tutorial on Efficient Research with Slurm Compute Clusters.