vision-language-pretraining


Video-LLaMA
[EMNLP 2023 Demo] Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Video Understanding
- 3.1k
- Python
- BSD-3-Clause
- 2 y ago


Video-ChatGPT
[ACL 2024 🔥] Video-ChatGPT is a video conversation model capable of generating meaningful conversation about videos. It combines the capabilities of LLMs with a pretrained visual encoder adapted for spatiotemporal video representation. We also introduce a rigorous 'Quantitative Evaluation Benchmarking' for video-based conversational models.
- 1.5k
- Python
- CC-BY-4.0
- 3 mo ago


VALOR
[TPAMI2024] Codes and Models for VALOR: Vision-Audio-Language Omni-Perception Pretraining Model and Dataset
- 311
- Python
- MIT
- 23 mo ago

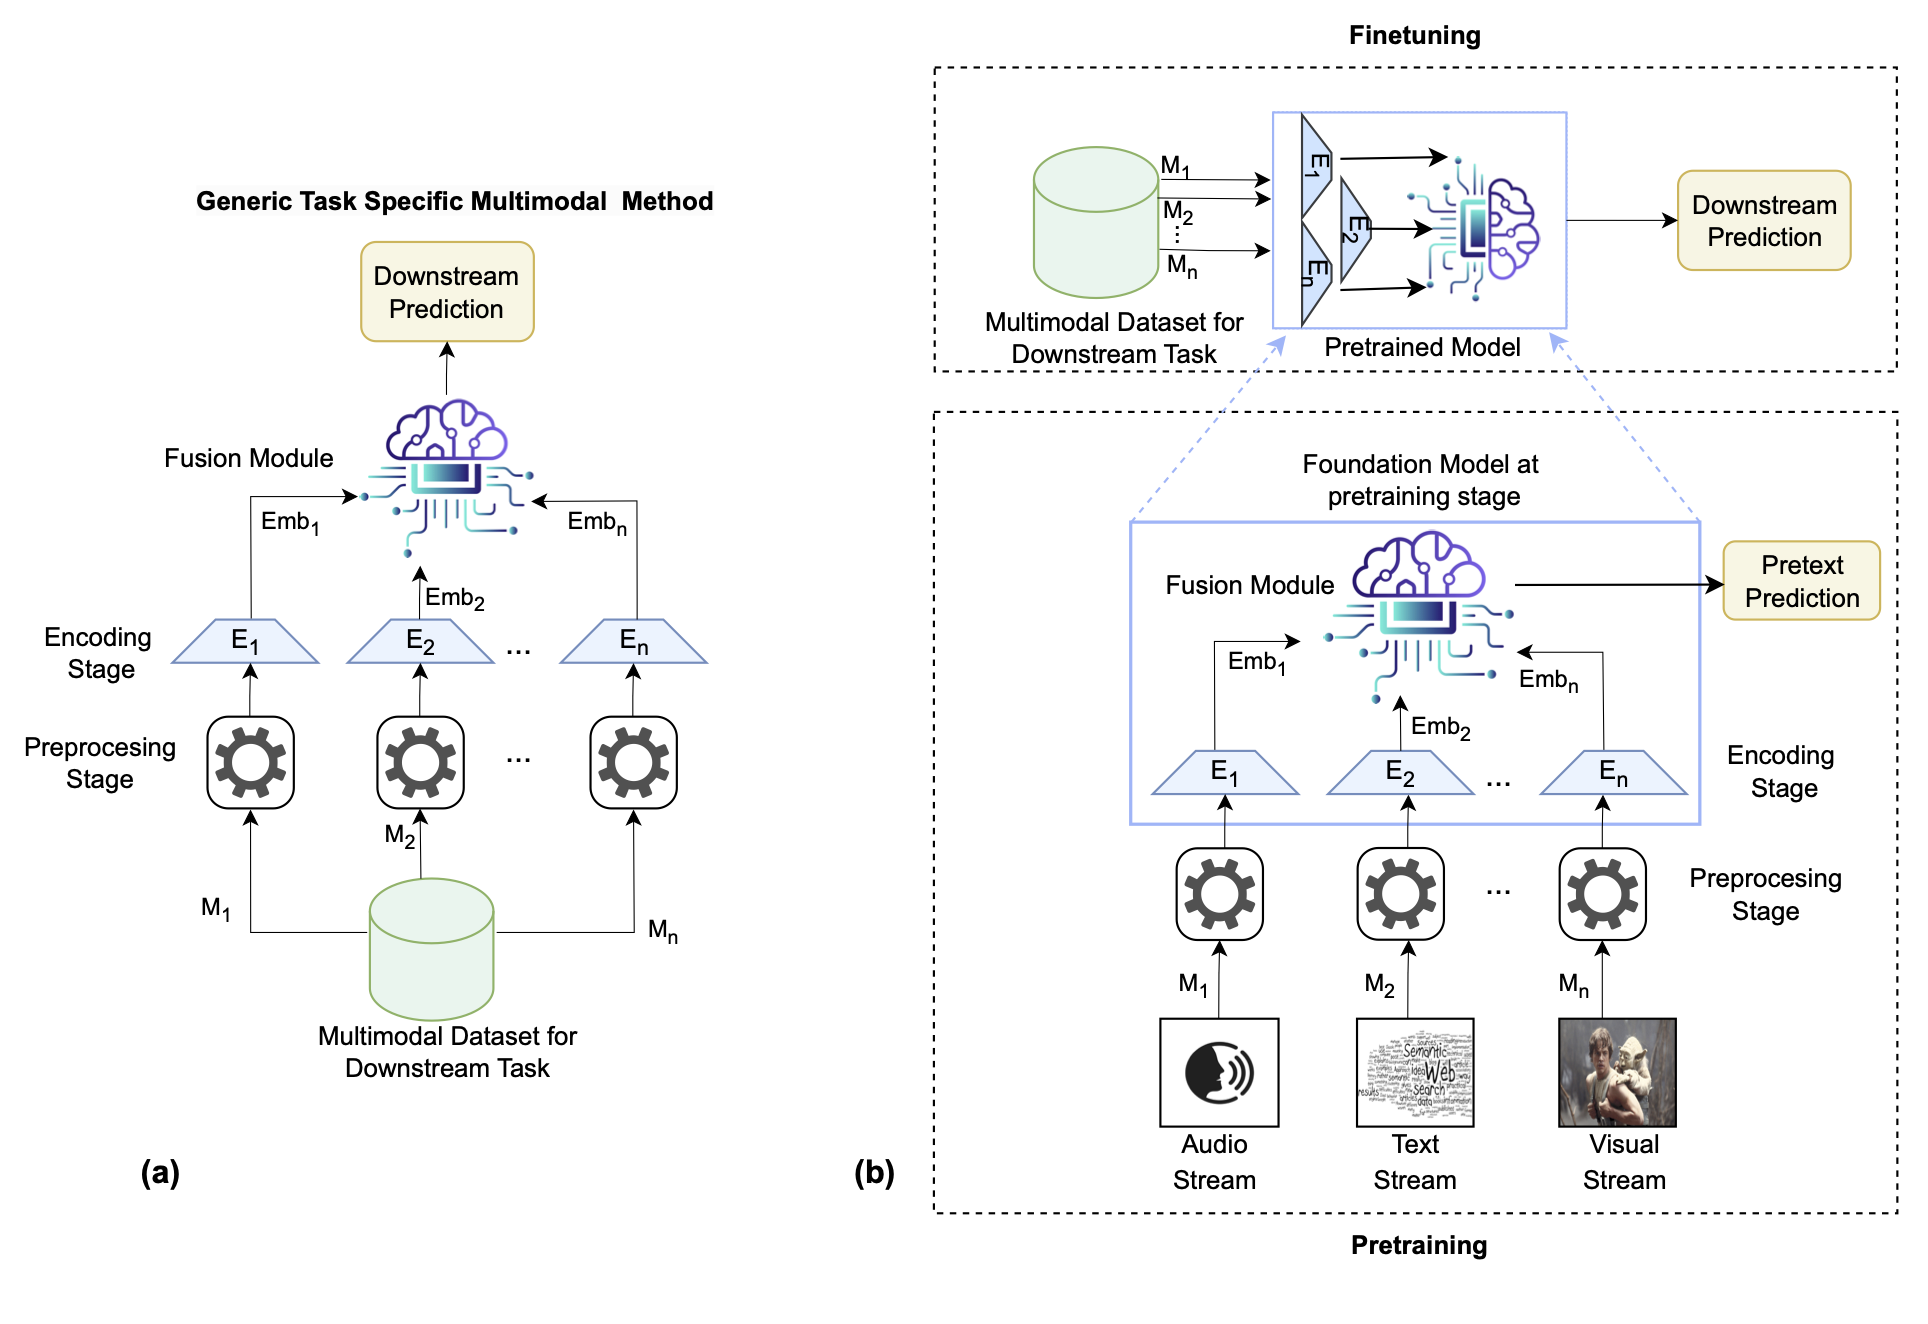
Multimodality-Representation-Learning
This repository provides a comprehensive collection of research papers focused on multimodal representation learning, all of which have been cited and discussed in the survey just accepted https://dl.acm.org/doi/abs/10.1145/3617833 .
- 86
- 17 mo ago


vlm-fairness
[Science Advances] Demographic Bias of Vision-Language Foundation Models in Medical Imaging
- 22
- Python
- MIT
- 20 mo ago

VTC-dataset
- 1
- Python
- 3 y ago
vision-language-pretraining-final
- 0
- 9
- mit
- 7 wk ago