LLaVA
[NeurIPS'23 Oral] Visual Instruction Tuning (LLaVA) built towards GPT-4V level capabilities and beyond.
- 25k
- Python
- Apache-2.0
- 2 y ago
[NeurIPS'23 Oral] Visual Instruction Tuning (LLaVA) built towards GPT-4V level capabilities and beyond.
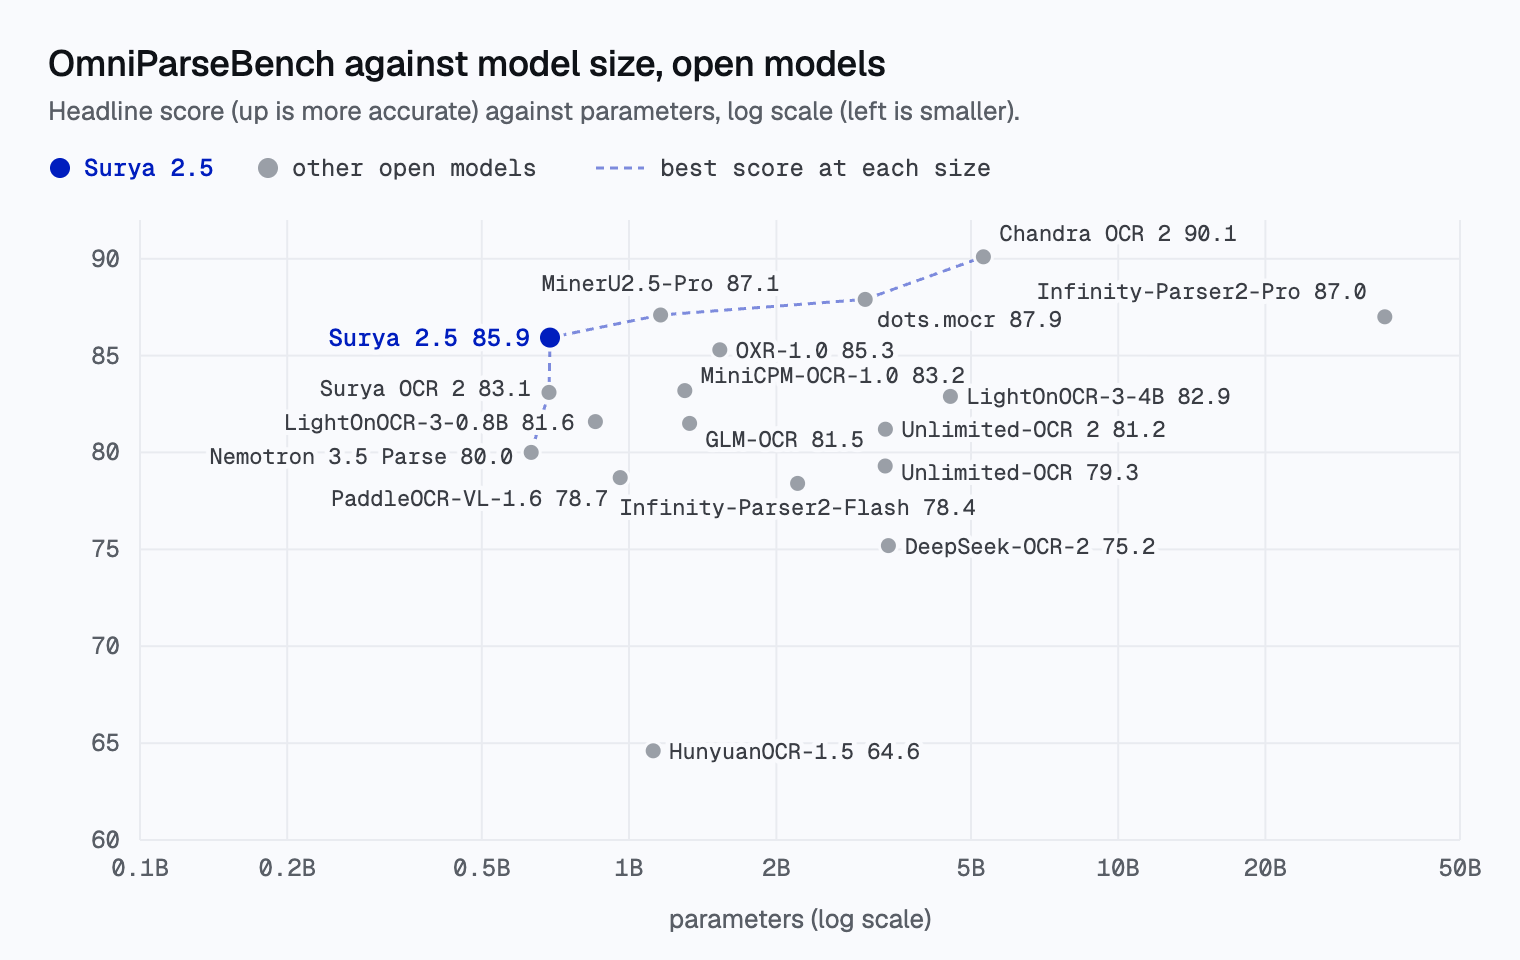
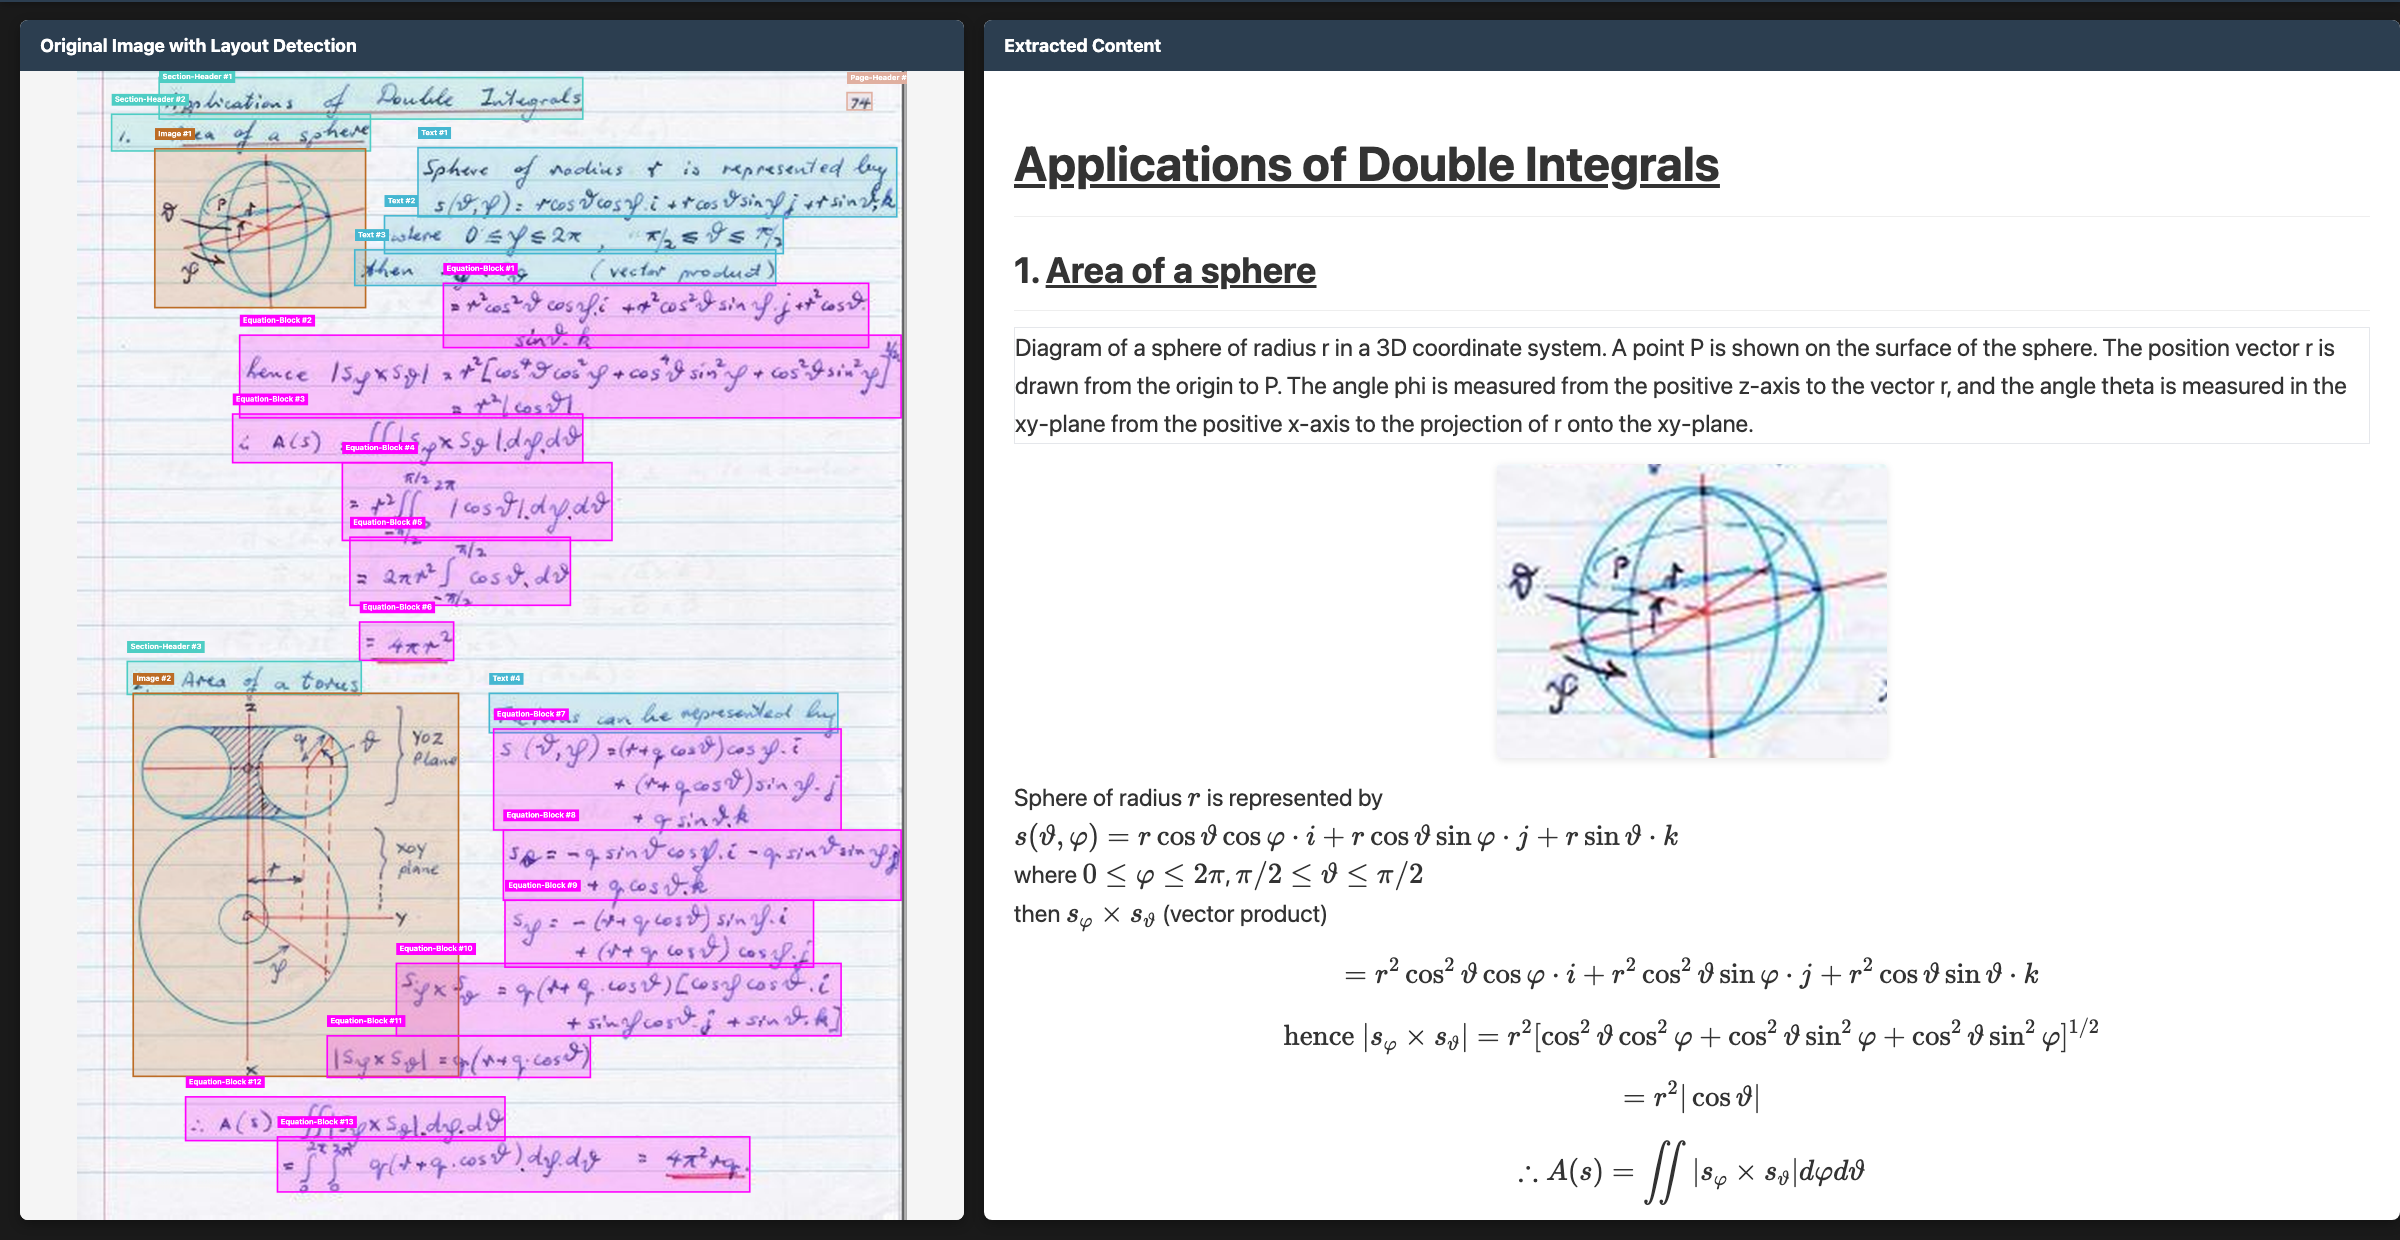
OCR, layout analysis, reading order, table recognition in 90+ languages
OCR model that handles complex tables, forms, handwriting with full layout.
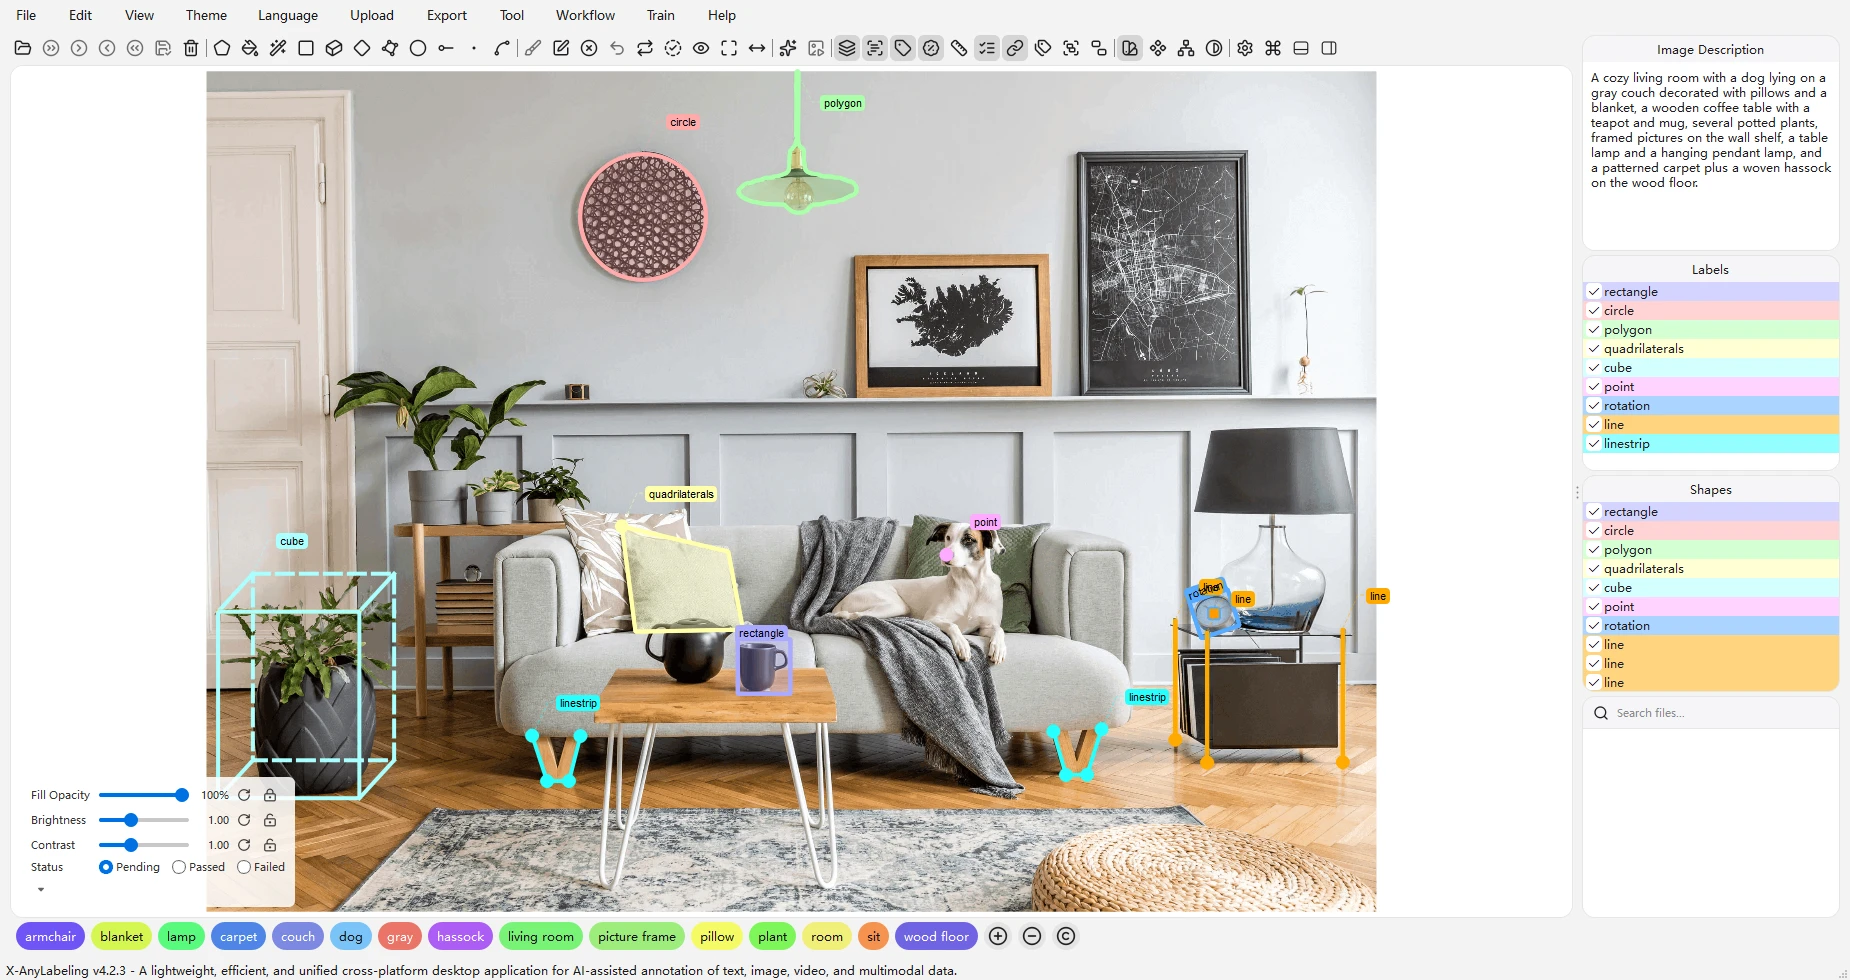
X-AnyLabeling: A lightweight, efficient, and unified cross-platform desktop application for annotating text, image, video, point cloud and multimodal data, combining versatile built-in tools with state-of-the-art AI models and flexible multi-format export.
[CVPR 2024 Oral] InternVL Family: A Pioneering Open-Source Alternative to GPT-4o. 接近GPT-4o表现的开源多模态对话模型
The official repo of Qwen-VL (通义千问-VL) chat & pretrained large vision language model proposed by Alibaba Cloud.
MLX-VLM is a package for inference and fine-tuning of Vision Language Models (VLMs) on your Mac using MLX.
MineContext is your proactive context-aware AI partner(Context-Engineering+ChatGPT Pulse)
Align Anything: Training All-modality Model with Feedback
One-for-All Multimodal Evaluation Toolkit Across Text, Image, Video, and Audio Tasks
The official repo of MiniMax-Text-01 and MiniMax-VL-01, large-language-model & vision-language-model based on Linear Attention
The Swiss Army Knife of Offline AI. Chat, see, speak, and generate images on your phone or Mac — GGUF LLMs, vision, Whisper speech-to-text, Stable Diffusion, tool calling, and local-network servers. Runs on your CPU, GPU, or NPU. No account, no API key, zero data leaves your device.
InternLM-XComposer2.5-OmniLive: A Comprehensive Multimodal System for Long-term Streaming Video and Audio Interactions
NVIDIA AI Blueprint for video search and summarization (VSS) is a GPU-accelerated reference architecture for building video analytics agents with real-time verified alerts, visual Q&A, and automated reporting. The VSS Blueprint uses vision language models (VLMs) such as NVIDIA Cosmos, LLMs such as NVIDIA Nemotron, RAG, and NVIDIA NIMs.
An open-source implementaion for fine-tuning Qwen-VL series by Alibaba Cloud.
[CVPR 2025] Open-source, End-to-end, Vision-Language-Action model for GUI Agent & Computer Use.
A collection of original, innovative ideas and algorithms towards Advanced Literate Machinery. This project is maintained by the OCR Team in the Language Technology Lab, Tongyi Lab, Alibaba Group.
High-performance OpenAI and Anthropic compatible LLM inference server for Apple Silicon. Native MLX, continuous batching, multimodal models, MCP tool calling, and Claude Code support.
A novel Multimodal Large Language Model (MLLM) architecture, designed to structurally align visual and textual embeddings.
Get clean data from tricky documents, powered by vision-language models ⚡
[ICCV 2025] Implementation for Describe Anything: Detailed Localized Image and Video Captioning
Fine-tune LLMs on your Mac with Apple Silicon. SFT, DPO, GRPO, Vision, TTS, STT, Embedding, and OCR fine-tuning — natively on MLX. Unsloth-compatible API.
Fully Open Framework for Democratized Multimodal Training
[dsh]为纯文本模型设计更强大的视觉工具箱:一行安装使用、粘贴图片直接识别、多张图片问答、截图到前端UI 还原等|DeepSeek Harness-native integration for agent-vision-toolkit: image Q&A, long-screenshot OCR, UI restoration, grounding, pixel diff, Artifacts, and Web UI.
This series will take you on a journey from the fundamentals of NLP and Computer Vision to the cutting edge of Vision-Language Models.
[CVPR 2024 Highlight🔥] Chat-UniVi: Unified Visual Representation Empowers Large Language Models with Image and Video Understanding
About This repository is a curated collection of the most exciting and influential CVPR 2025 papers. 🔥 [Paper + Code + Demo]
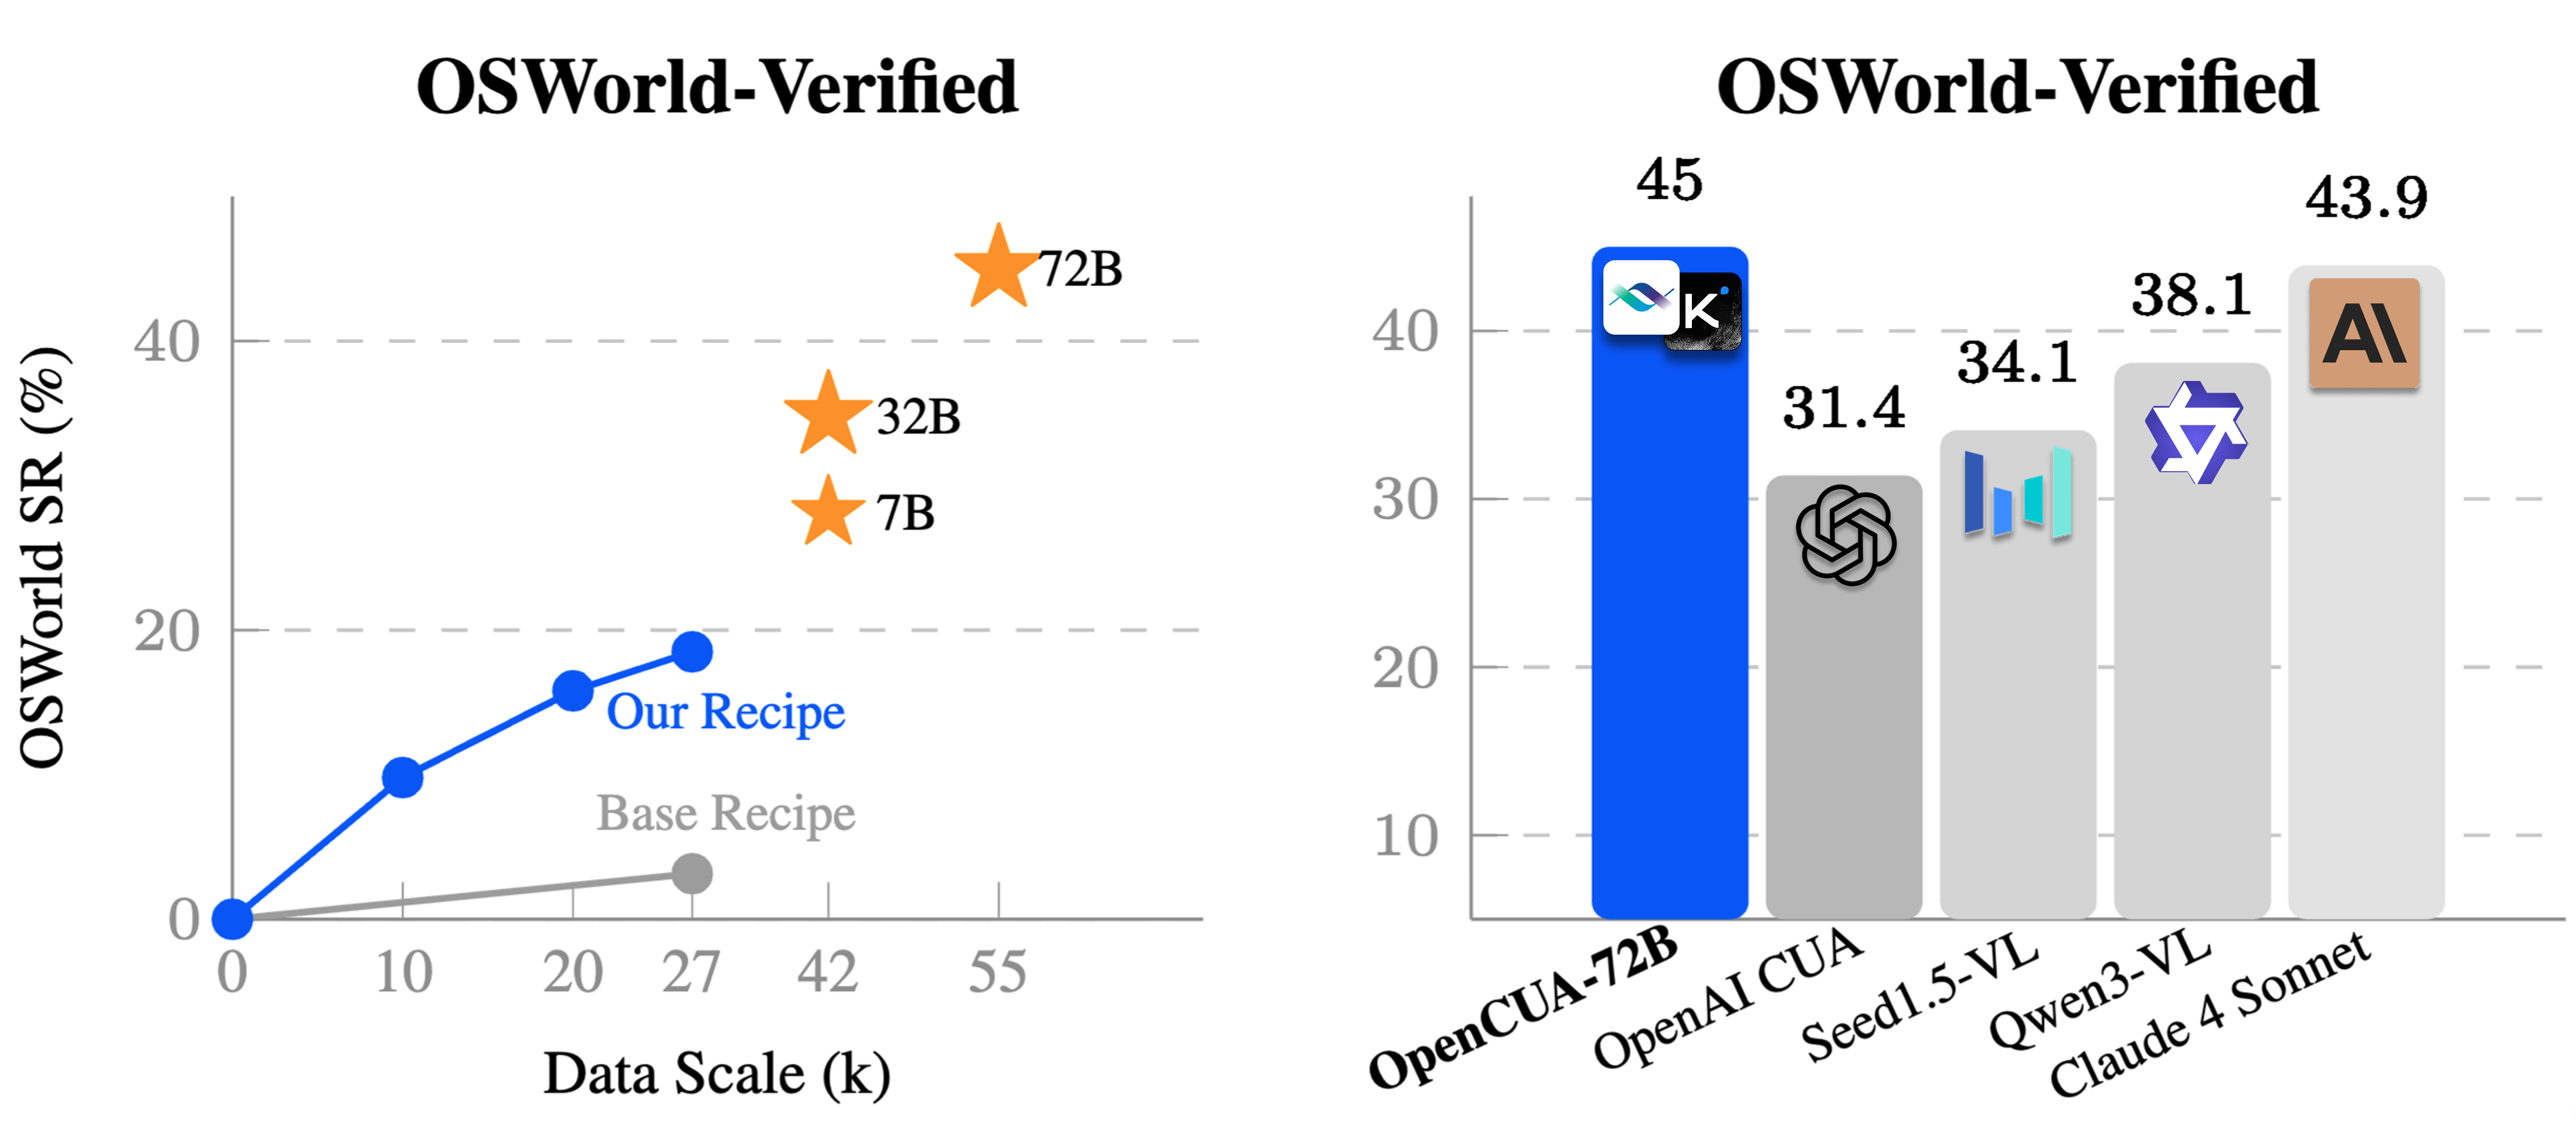
[NeurIPS 2025 Spotlight] OpenCUA: Open Foundations for Computer-Use Agents
An open-weight 11B model series for long-form and real-time video understanding
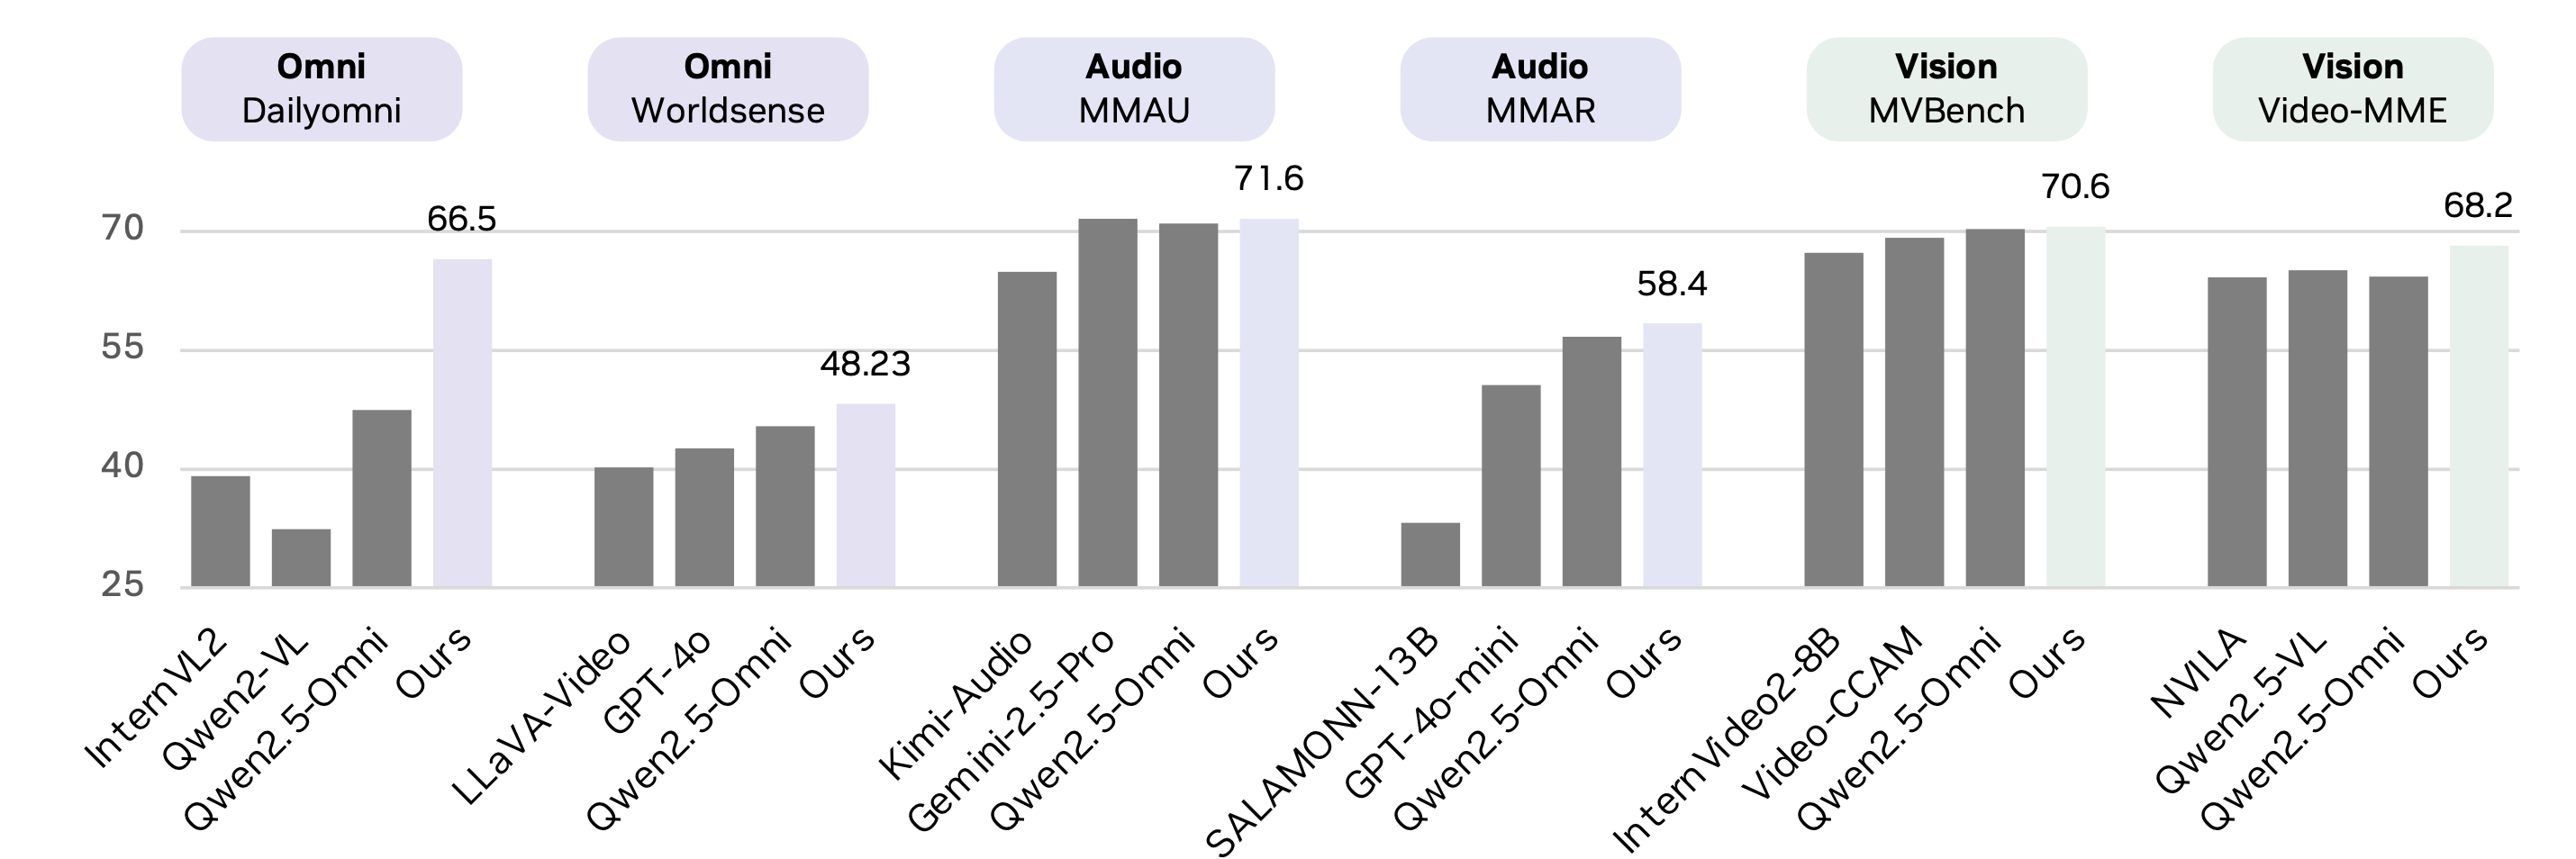
OmniVinci is an omni-modal LLM for joint understanding of vision, audio, and language.
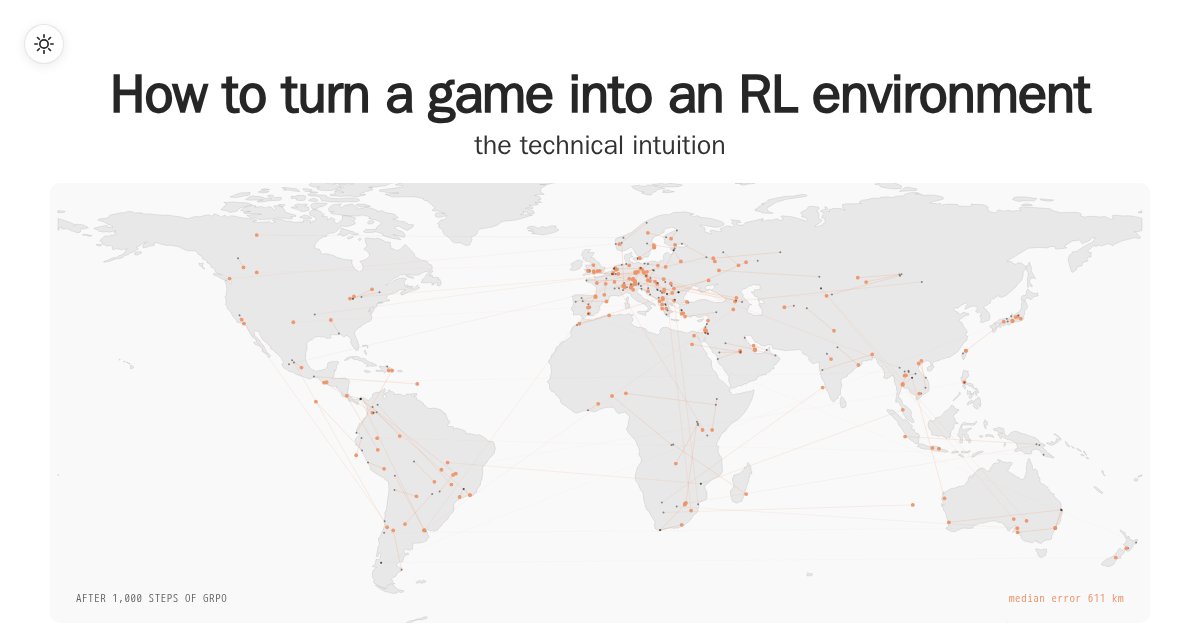
From an idea to a trained 4B, with the dead ends left in
Runs in the browser on Hugging Face
Build visual AI workflows with MiniCPM-V 4.7
Runs in the browser on Hugging Face
Qwen3-VL 8B 圖表理解微調、量化與 serving 實證作品
Runs in the browser on Hugging Face