firecrawl
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
- 203k
- TypeScript
- AGPL-3.0
- 2 h ago
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
Give your AI agent eyes to see the entire internet. Read & search Twitter, Reddit, YouTube, GitHub, Bilibili, XiaoHongShu — one CLI, zero API fees.
🕷️ The BEST Web Scraping framework that handles everything from a single request to a full-scale crawl! Don't be shy, join here: https://discord.gg/EMgGbDceNQ and follow here for daily tips and tricks: https://x.com/Scrapling_dev
Best headless browser for AI agents. Lite, Fast, High-Compatibility. Built in Rust
Turn any website into a structured API. Extract, automate, search and monitor the web.
scrape data from Google Maps. Extracts data such as the name, address, phone number, website URL, rating, reviews number, latitude and longitude, reviews,email and more for each place
Professional-grade, local-first browser extension that transforms any webpage into high-fidelity, LLM-friendly Markdown entirely within the browser's runtime. Zero-cloud, privacy-centric, and designed specifically for AI workflows.
Scrape Google AI Mode responses without blocks on a large scale.
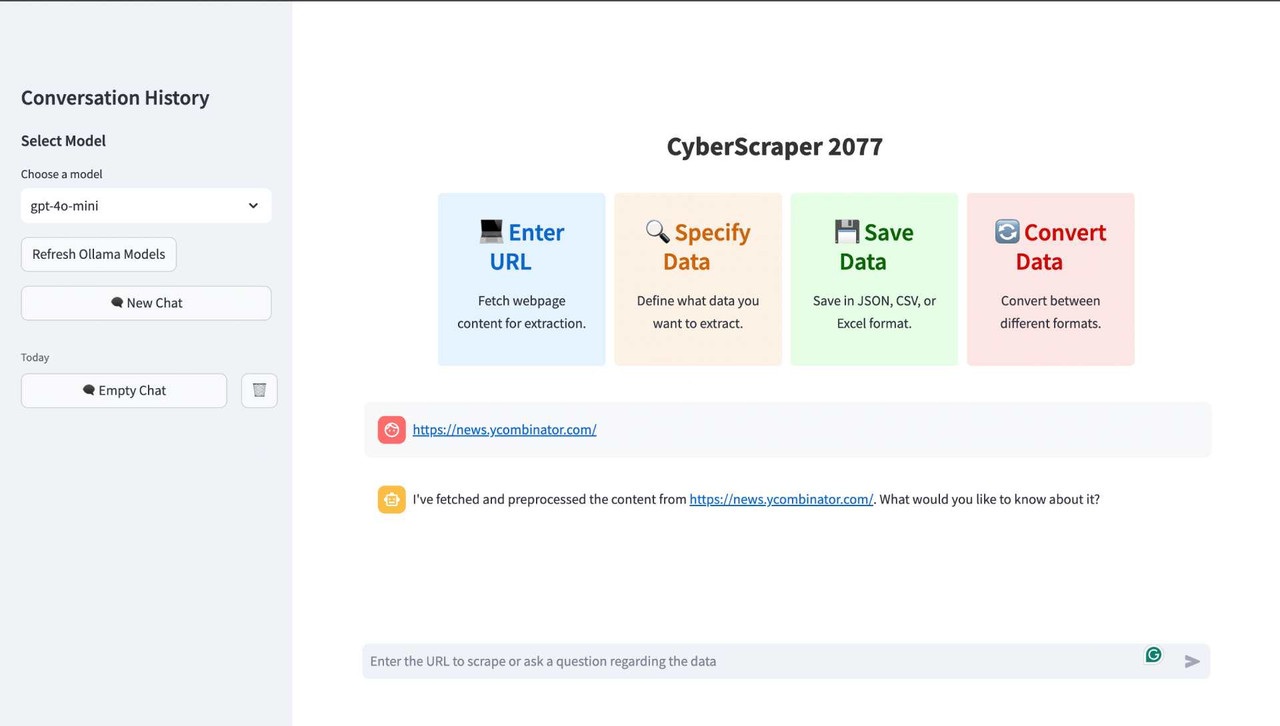
A Powerful web scraper powered by LLM | OpenAI, Gemini & Ollama
The process of extracting product data from Amazon using Python, including titles, ratings, prices, images, and descriptions.
A guide for extracting titles, authors, and citations from Google Scholar using Python and Oxylabs SERP Scraper API.
A code for extracting best-selling items, search results, and currently available deals from Amazon using Python and Oxylabs E-Commerce Scraper API.
Fast, lightweight Firecrawl/Tavily alternative in Rust. Web scraper, crawler & search API with MCP server for AI agents. Drop-in Firecrawl-compatible API (/scrape, /crawl, /search). 2.3x faster than Tavily, 1.5x faster than Firecrawl in 1K-URL benchmarks. 6 MB RAM, single binary. Self-host or use managed cloud.
:rocket: Stealth - Secure, Peer-to-Peer, Private and Automateable Web Browser/Scraper/Proxy
100% free and full open-source edge Firecrawl alternative with better links extraction for agents - that you can deploy to cloudflare or vercel by yourself.
Python quick start guides to get the most out of Oxylabs' Web Scraper API free trial.
All-in-one web scraping API for real-time, large-scale data extraction – proxies, CAPTCHA management, JS rendering, and parsing in a single request returning HTML or structured JSON.
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page, designed for LLM RAG
Amazon Scraper — free, open-source Amazon scraper. Unlimited product details, prices, reviews & best sellers as clean JSON, no API key, no proxies.
A tutorial for web scraping using Playwright headless browser
A tutorial for collecting job postings from Indeed using Python and Oxylabs Web Scraper API.
Learn to create ChatGPT prompts that generate a web scraping code with proper CSS selectors.
A simple python library that allows for easy access of the SEC website so that someone can parse filings, collect data, and query documents.
Google Play scraper for Node.js with a fully typed TypeScript API. App details, search, top charts, reviews, permissions and data safety. A modern replacement for the unmaintained google-play-scraper.
Scrape Google Trends data using Python or the Bright Data API. Get real-time search trends, filter by location, category, and time range, and scale effortlessly.
Coleta e processa dados históricos de preços da Tabela FIPE para PostgreSQL.
Makra is a memory layer between the web and your AI agents. It serves real-time structured data from the open web at the cost of a vector search.