llm-evaluation-framework

Open repos and models their makers tagged llm-evaluation-framework, most starred first. The same for everyone.

AI on my own machineRepo

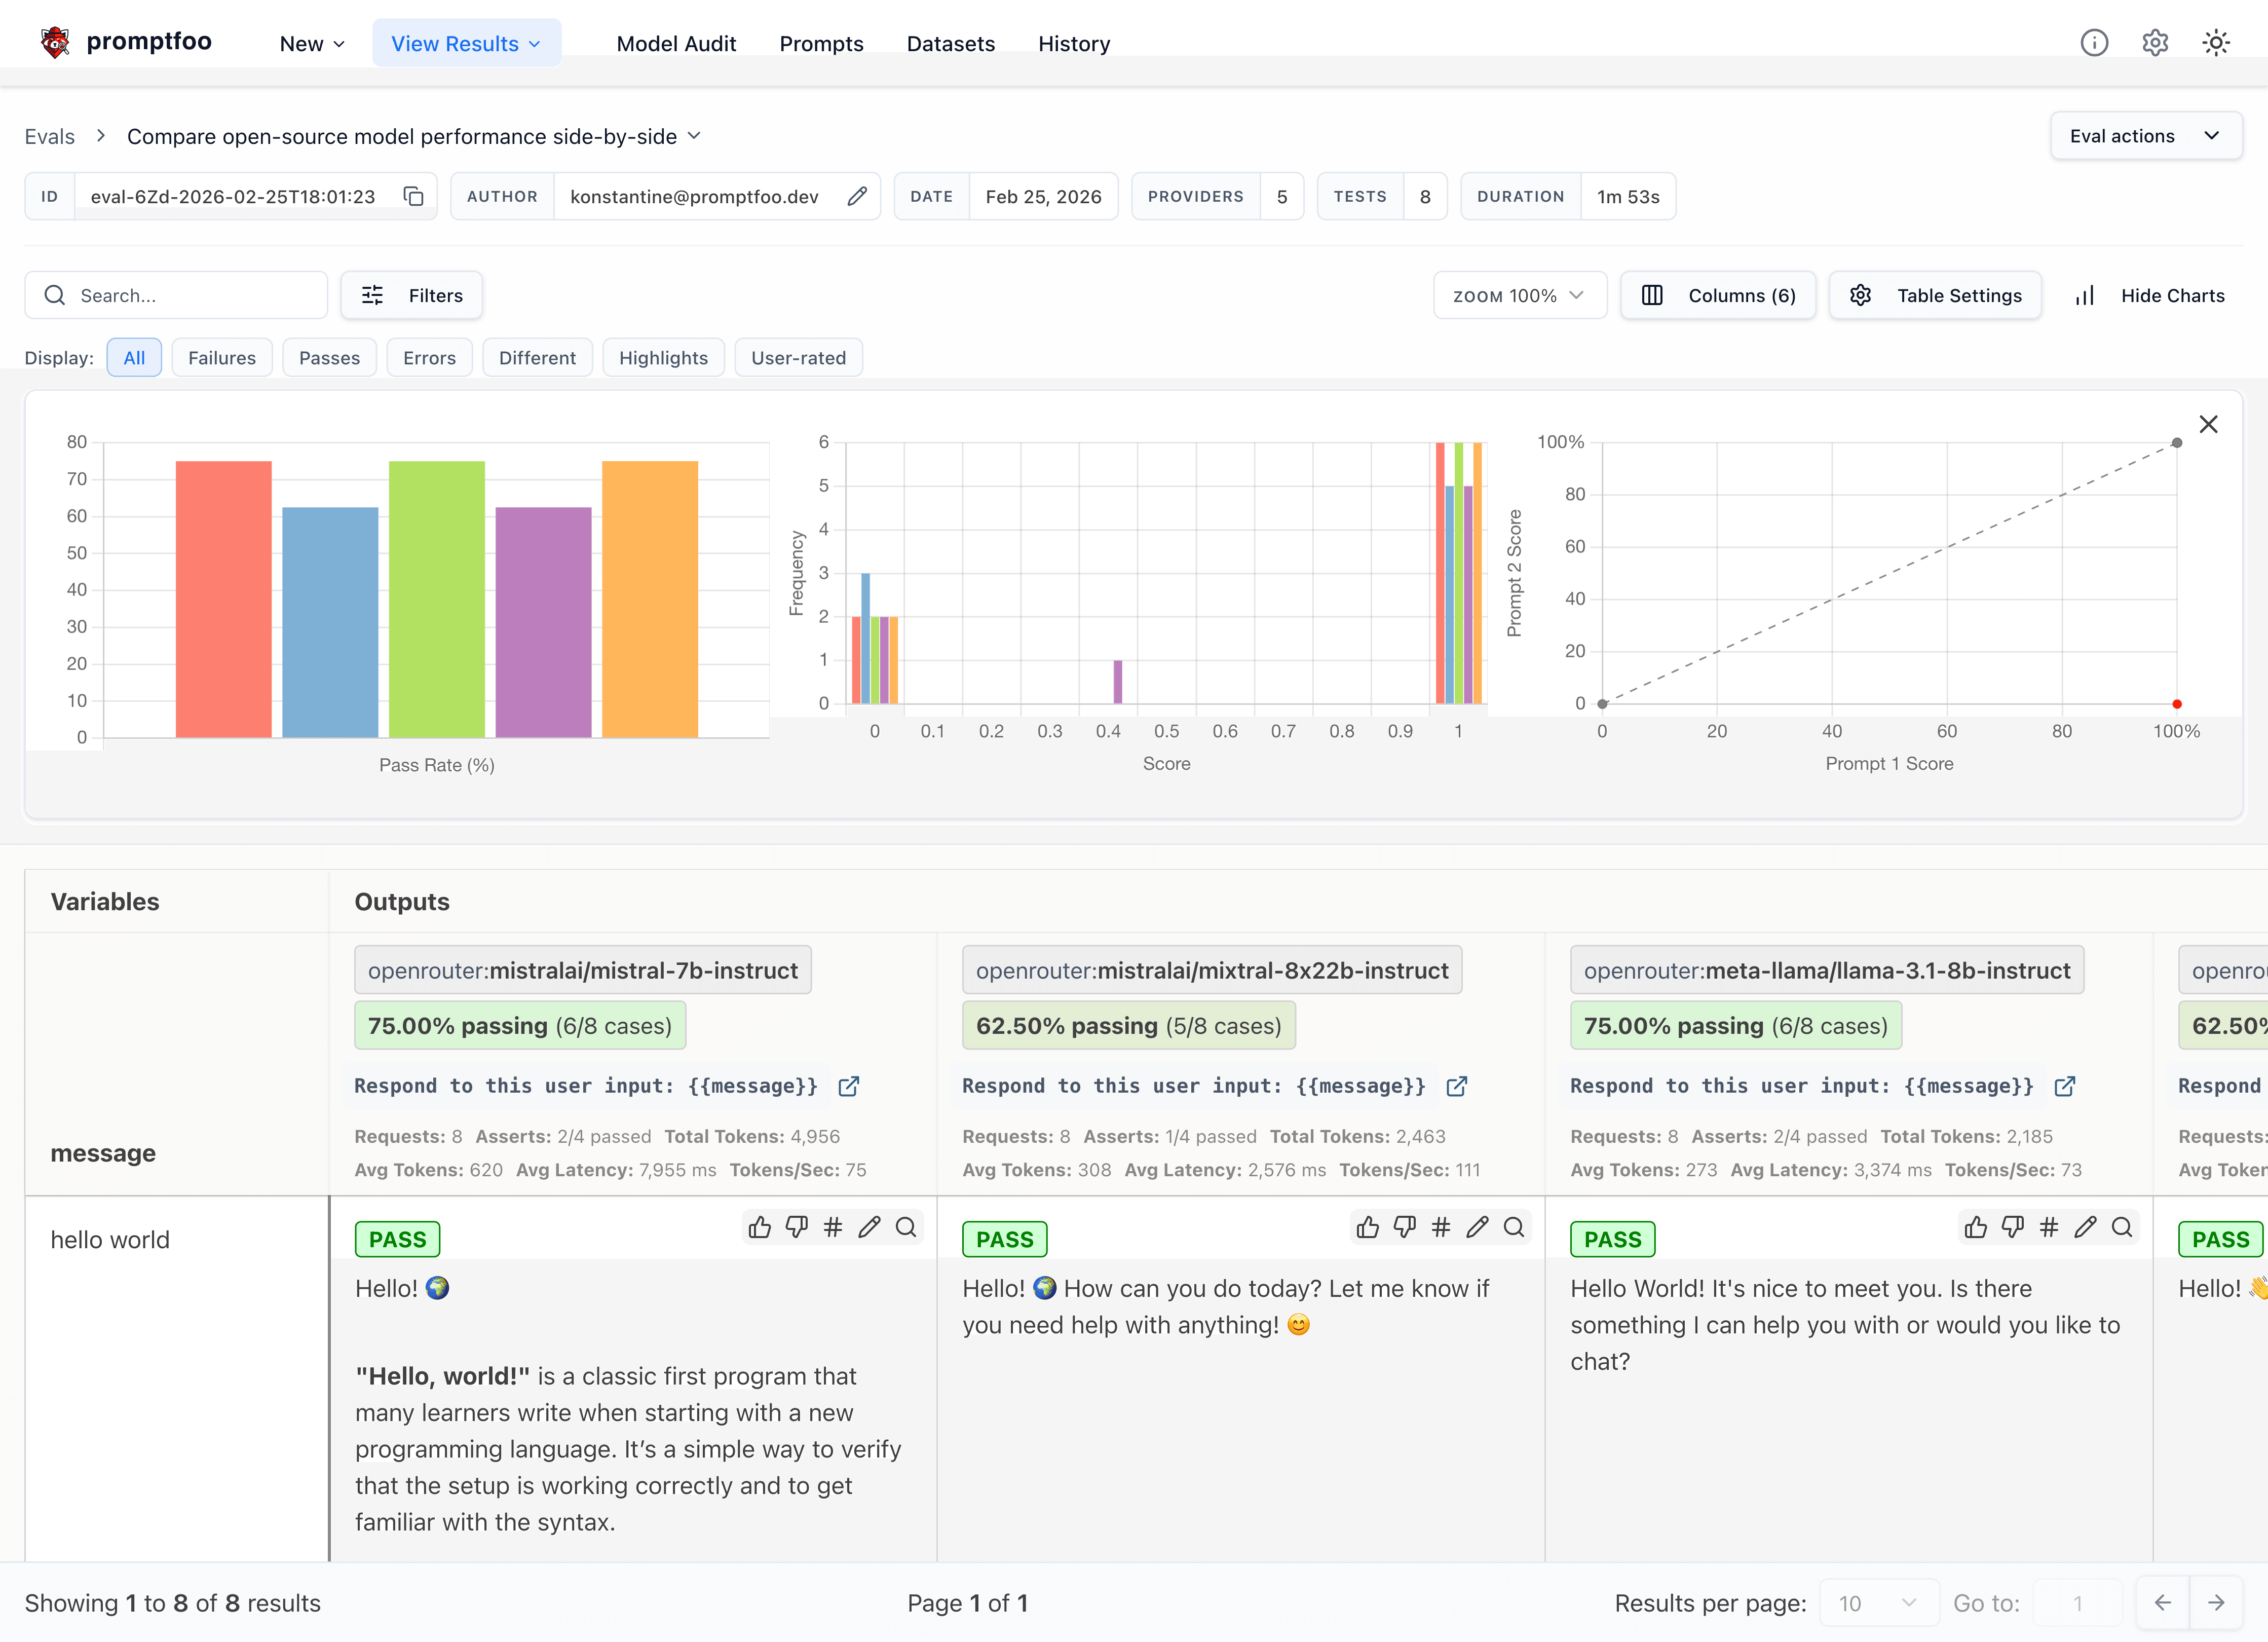
promptfoo

Test your prompts, agents, and RAGs. Red teaming/pentesting/vulnerability scanning for AI. Compare performance of GPT, Claude, Gemini, DeepSeek, and more. Simple declarative configs with command line and CI/CD integration. Used by OpenAI and Anthropic.

  • 28k
  • TypeScript
  • MIT
  • 2 h ago
promptfooTake it
GitHubRepo

MindTrial

MindTrial: Evaluate and compare AI language models (LLMs) on text-based tasks with optional file/image attachments and tool use. Supports multiple providers (OpenAI, Google, Anthropic, DeepSeek, Mistral AI, xAI, Alibaba, Moonshot AI, OpenRouter), custom tasks in YAML, and HTML/CSV/JSON reports.

  • 21
  • Go
  • MPL-2.0
  • 9 d ago
petmalTake it
AI on my own machineRepo

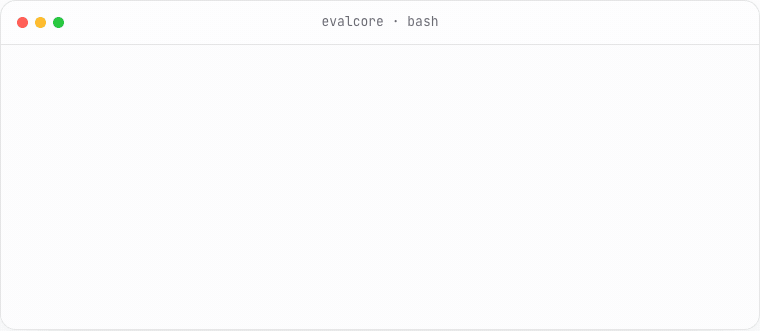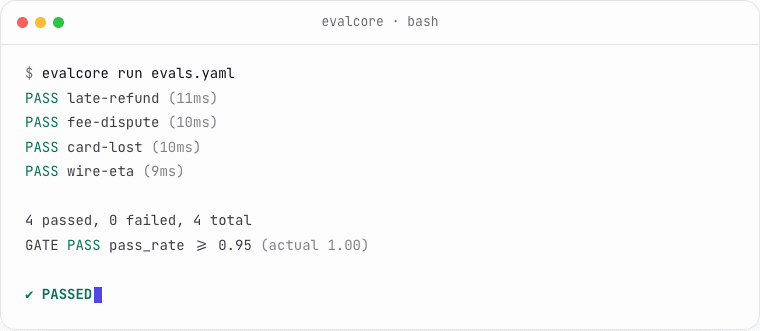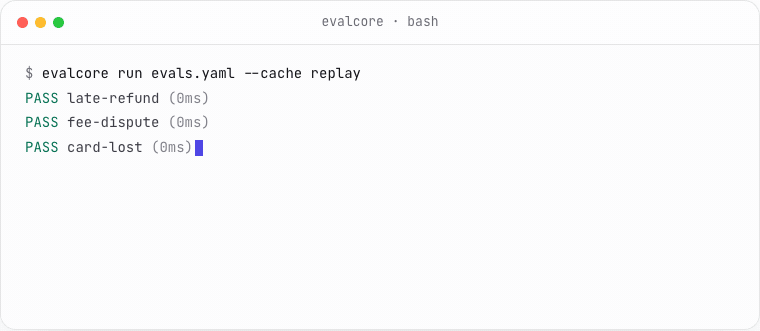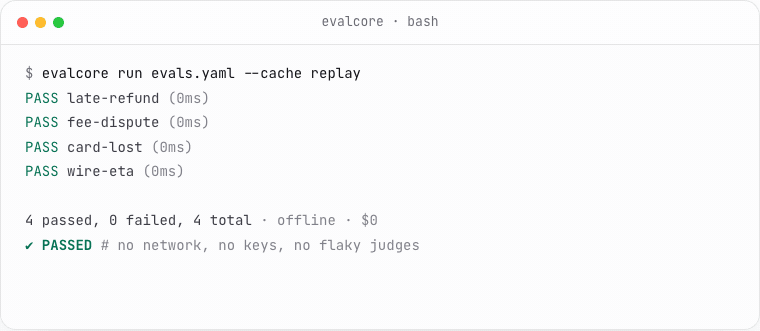
evalcore

Snapshot testing for LLM apps and agents, built to run locally and block regressions in CI.

  • 19
  • Rust
  • Apache-2.0
  • 4 mo ago
Eval-coreTake it
AI on my own machineRepo

LLM-Evaluation-Intermediate-to-Advanced

hands-on repository covering intermediate to advanced techniques for evaluating Large Language Models (LLMs). Explores evaluation methodologies, performance metrics, benchmarking, hallucination detection, response quality assessment, RAG evaluation, model comparison, and automated evaluation workflows using Python & modern LLM evaluation framework.

  • 2
  • Python
  • 6 d ago
Search GitHub and Hugging Face for llm-evaluation-framework

Get , open it once and sign in. Then come back here and press the button again.

llm-evaluation-framework: open source repos and models on Take My Repo