vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
- 97k
- Python
- Apache-2.0
- 41 min ago
A high-throughput and memory-efficient inference and serving engine for LLMs
The easiest way to serve AI apps and models - Build Model Inference APIs, Job queues, LLM apps, Multi-model pipelines, and more!
Type-safe, distributed orchestration of agents, ML pipelines, and real-time inference on your k8s — in pure Python with async/await, also other languages (rust, go and ts)
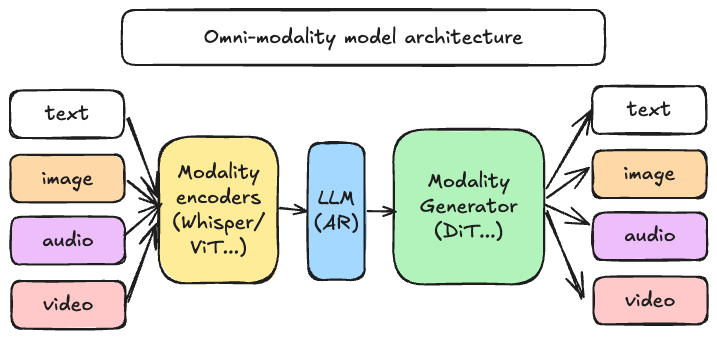
A framework for efficient model inference with omni-modality models
Standardized Distributed Generative and Predictive AI Inference Platform for Scalable, Multi-Framework Deployment on Kubernetes
In this repository, I will share some useful notes and references about deploying deep learning-based models in production.
LightLLM is a Python-based LLM (Large Language Model) inference and serving framework, notable for its lightweight design, easy scalability, and high-speed performance.
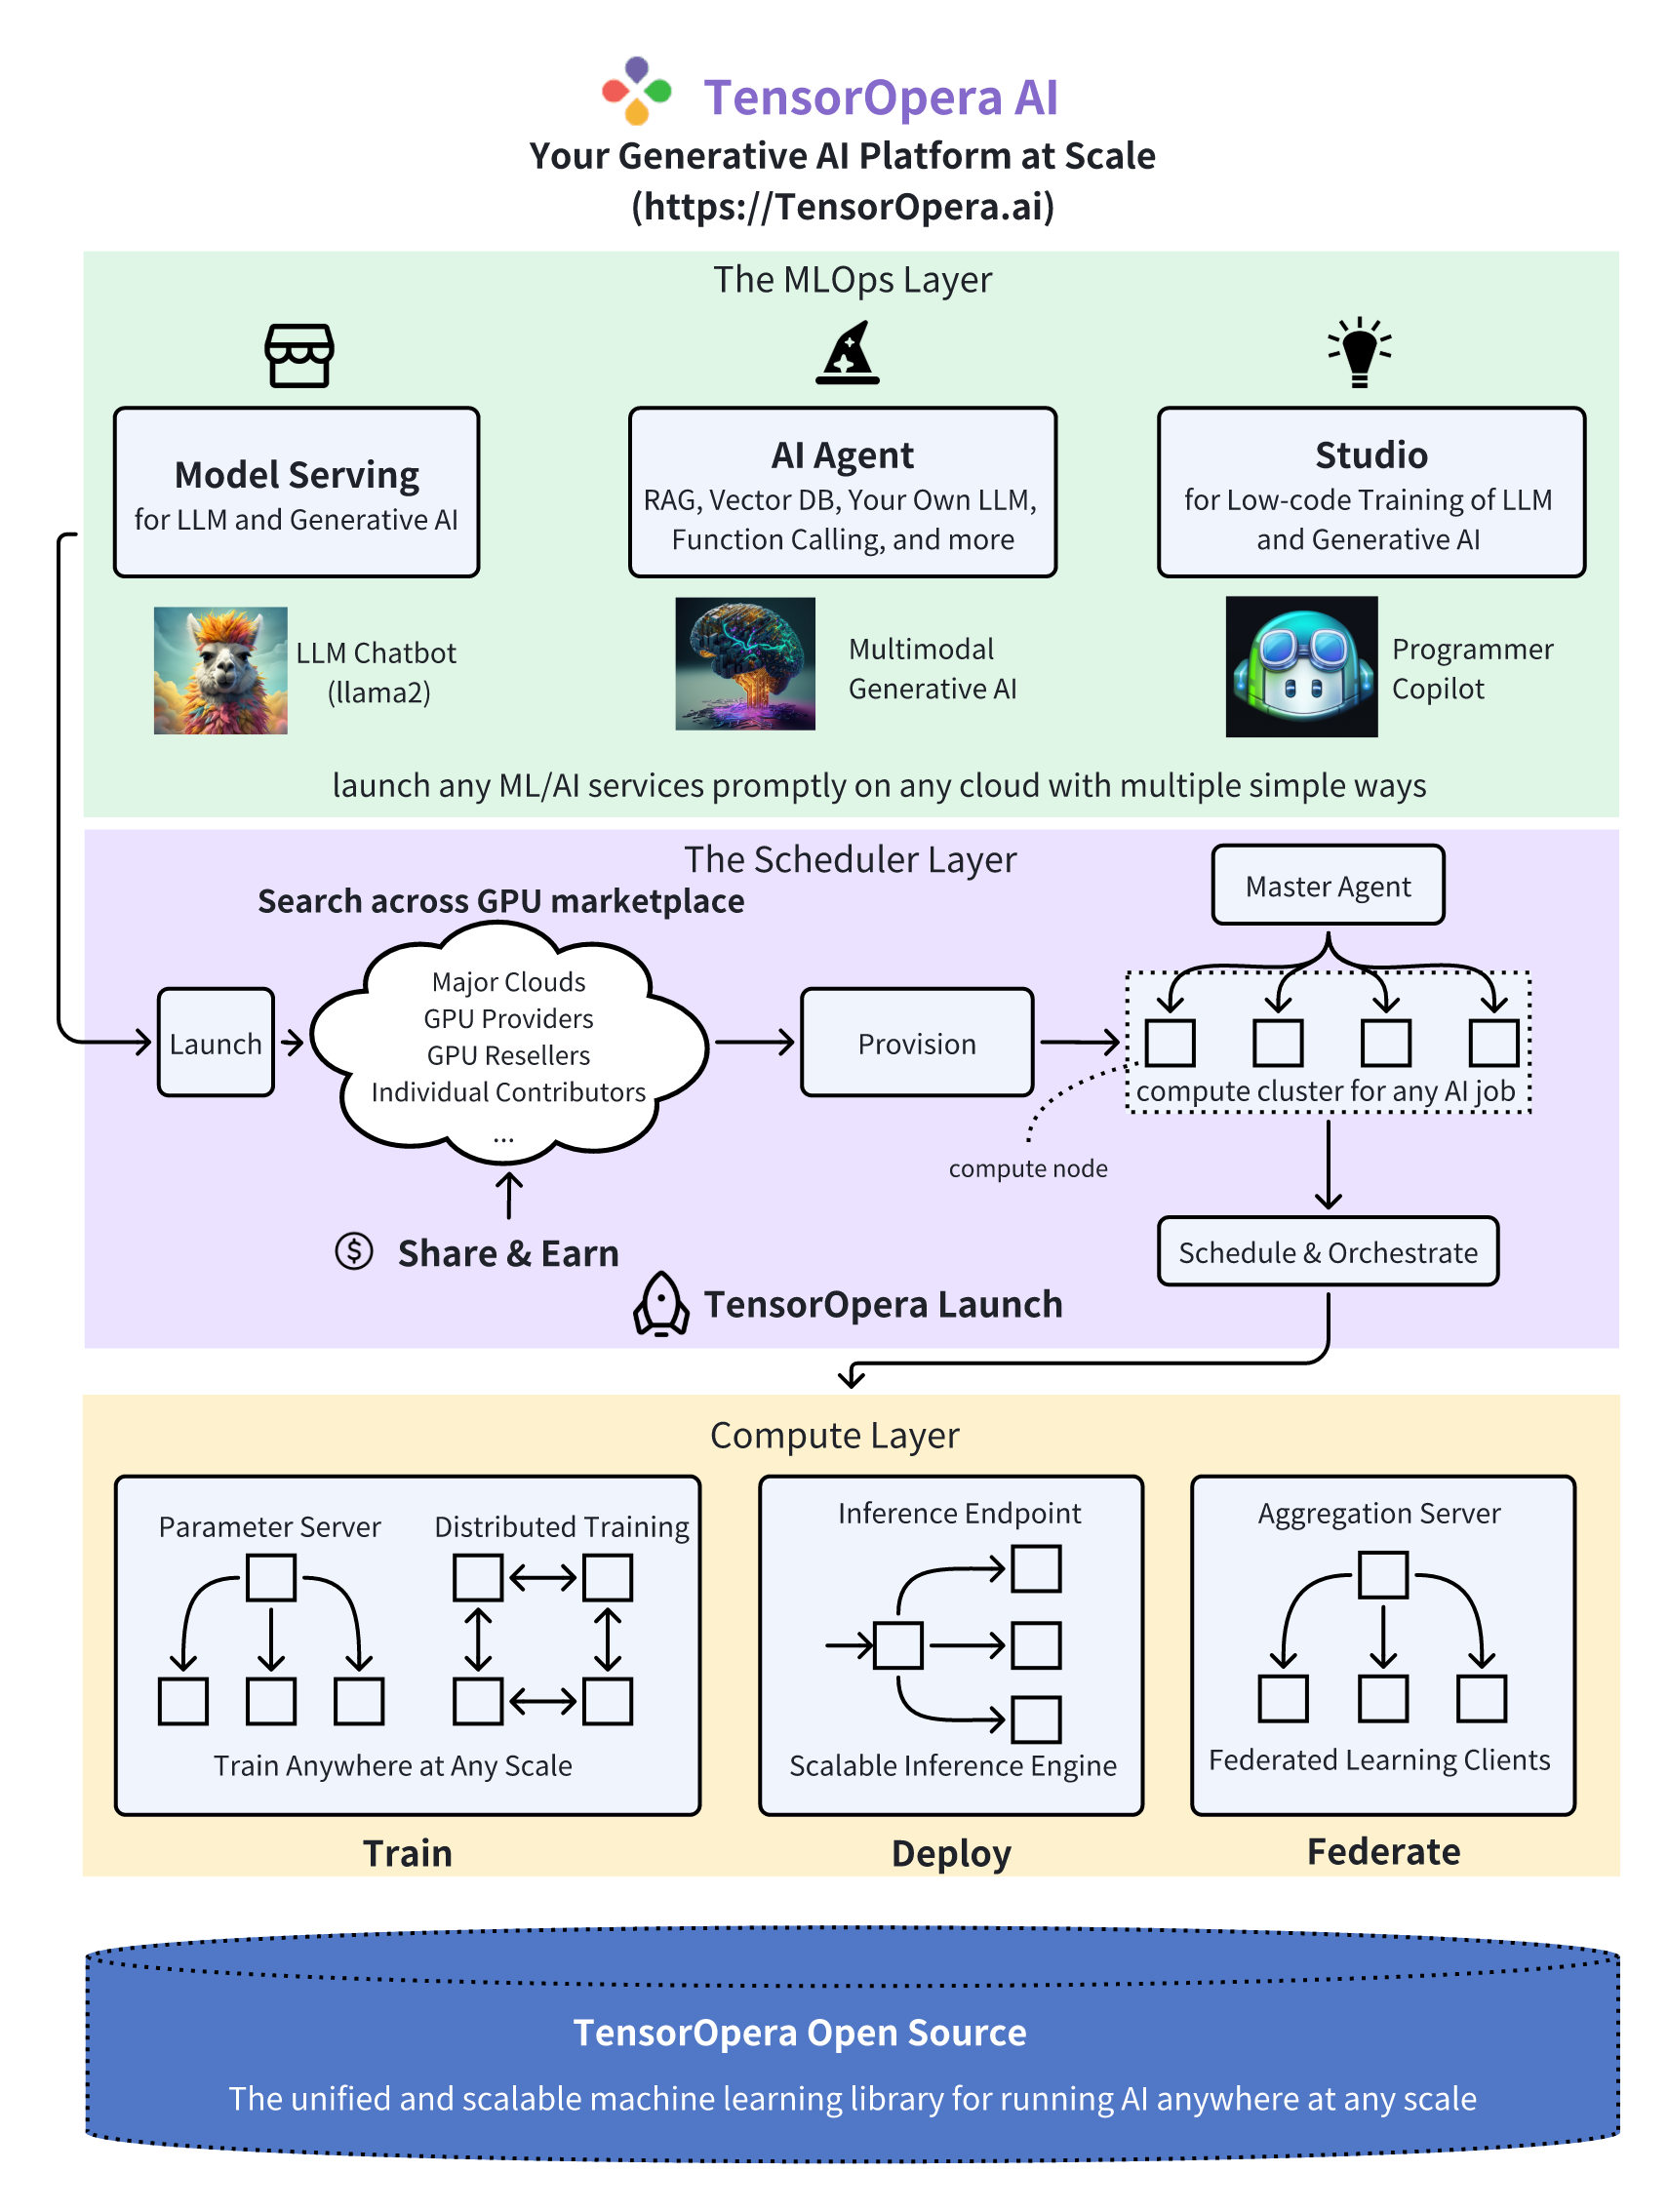
FEDML - The unified and scalable ML library for large-scale distributed training, model serving, and federated learning. FEDML Launch, a cross-cloud scheduler, further enables running any AI jobs on any GPU cloud or on-premise cluster. Built on this library, TensorOpera AI (https://TensorOpera.ai) is your generative AI platform at scale.
MLRun is an open source MLOps platform for quickly building and managing continuous ML applications across their lifecycle. MLRun integrates into your development and CI/CD environment and automates the delivery of production data, ML pipelines, and online applications.
High Performance Serving Runtime For Interactive Super Intelligence System
OpenLake is a high performance storage engine for efficient LLM inference and GPU Training
Jev-compatible API server for open decision models. Ollama for decision models: pull and serve 29 model families (Laya, pplx-decider, Clef, Winnow, coba...) locally or self-hosted behind /v1/systemone. The TypeSafe SDK works unchanged: set its base URL and pick an open model. CLI, desktop app, Docker, MCP server, public bench.
RTP-LLM: Alibaba's high-performance LLM inference engine for diverse applications.
A highly optimized LLM inference acceleration engine for Llama and its variants.
A high-performance ML model serving framework, offers dynamic batching and CPU/GPU pipelines to fully exploit your compute machine
Pure Rust + CUDA LLM inference engine — no PyTorch, OpenAI-compatible, serves Qwen3 to Kimi-K2
FastAPI Skeleton App to serve machine learning models production-ready.
Open Model Engine (OME) — Kubernetes operator for LLM serving, GPU scheduling, and model lifecycle management. Works with SGLang, vLLM, TensorRT-LLM, and Triton
Python + Inference - Model Deployment library in Python. Simplest model inference server ever.
JetStream is a throughput and memory optimized engine for LLM inference on XLA devices, starting with TPUs (and GPUs in future -- PRs welcome).
The production framework for Predictive and Generative AI. Serve any model as an API in one line, with OpenAI/Anthropic/Ollama-compatible endpoints, a built-in chat UI, and native MCP.
BentoDiffusion: A collection of diffusion models served with BentoML
MONAI Deploy App SDK offers a framework and associated tools to design, develop and verify AI-driven applications in the healthcare imaging domain.
Live, multi-camera object tracking with SAM3, SAM 2 and EdgeTAM, on one GPU or many. One model per GPU serves every camera: faster than the original code, about 4x less GPU memory, identical masks.
Unified KV-cache compression for LLM inference: 12 Python-native methods, guarded add-on composition and routing, analytical capacity simulation, Godzilla KVarN/TriAttention with SM86/SM89 qualification, CUDA weight sharing, and multi-GPU planning.
Python library for Modzy Machine Learning Operations (MLOps) Platform
Learn the ins and outs of efficiently serving Large Language Models (LLMs). Dive into optimization techniques, including KV caching and Low Rank Adapters (LoRA), and gain hands-on experience with Predibase’s LoRAX framework inference server.
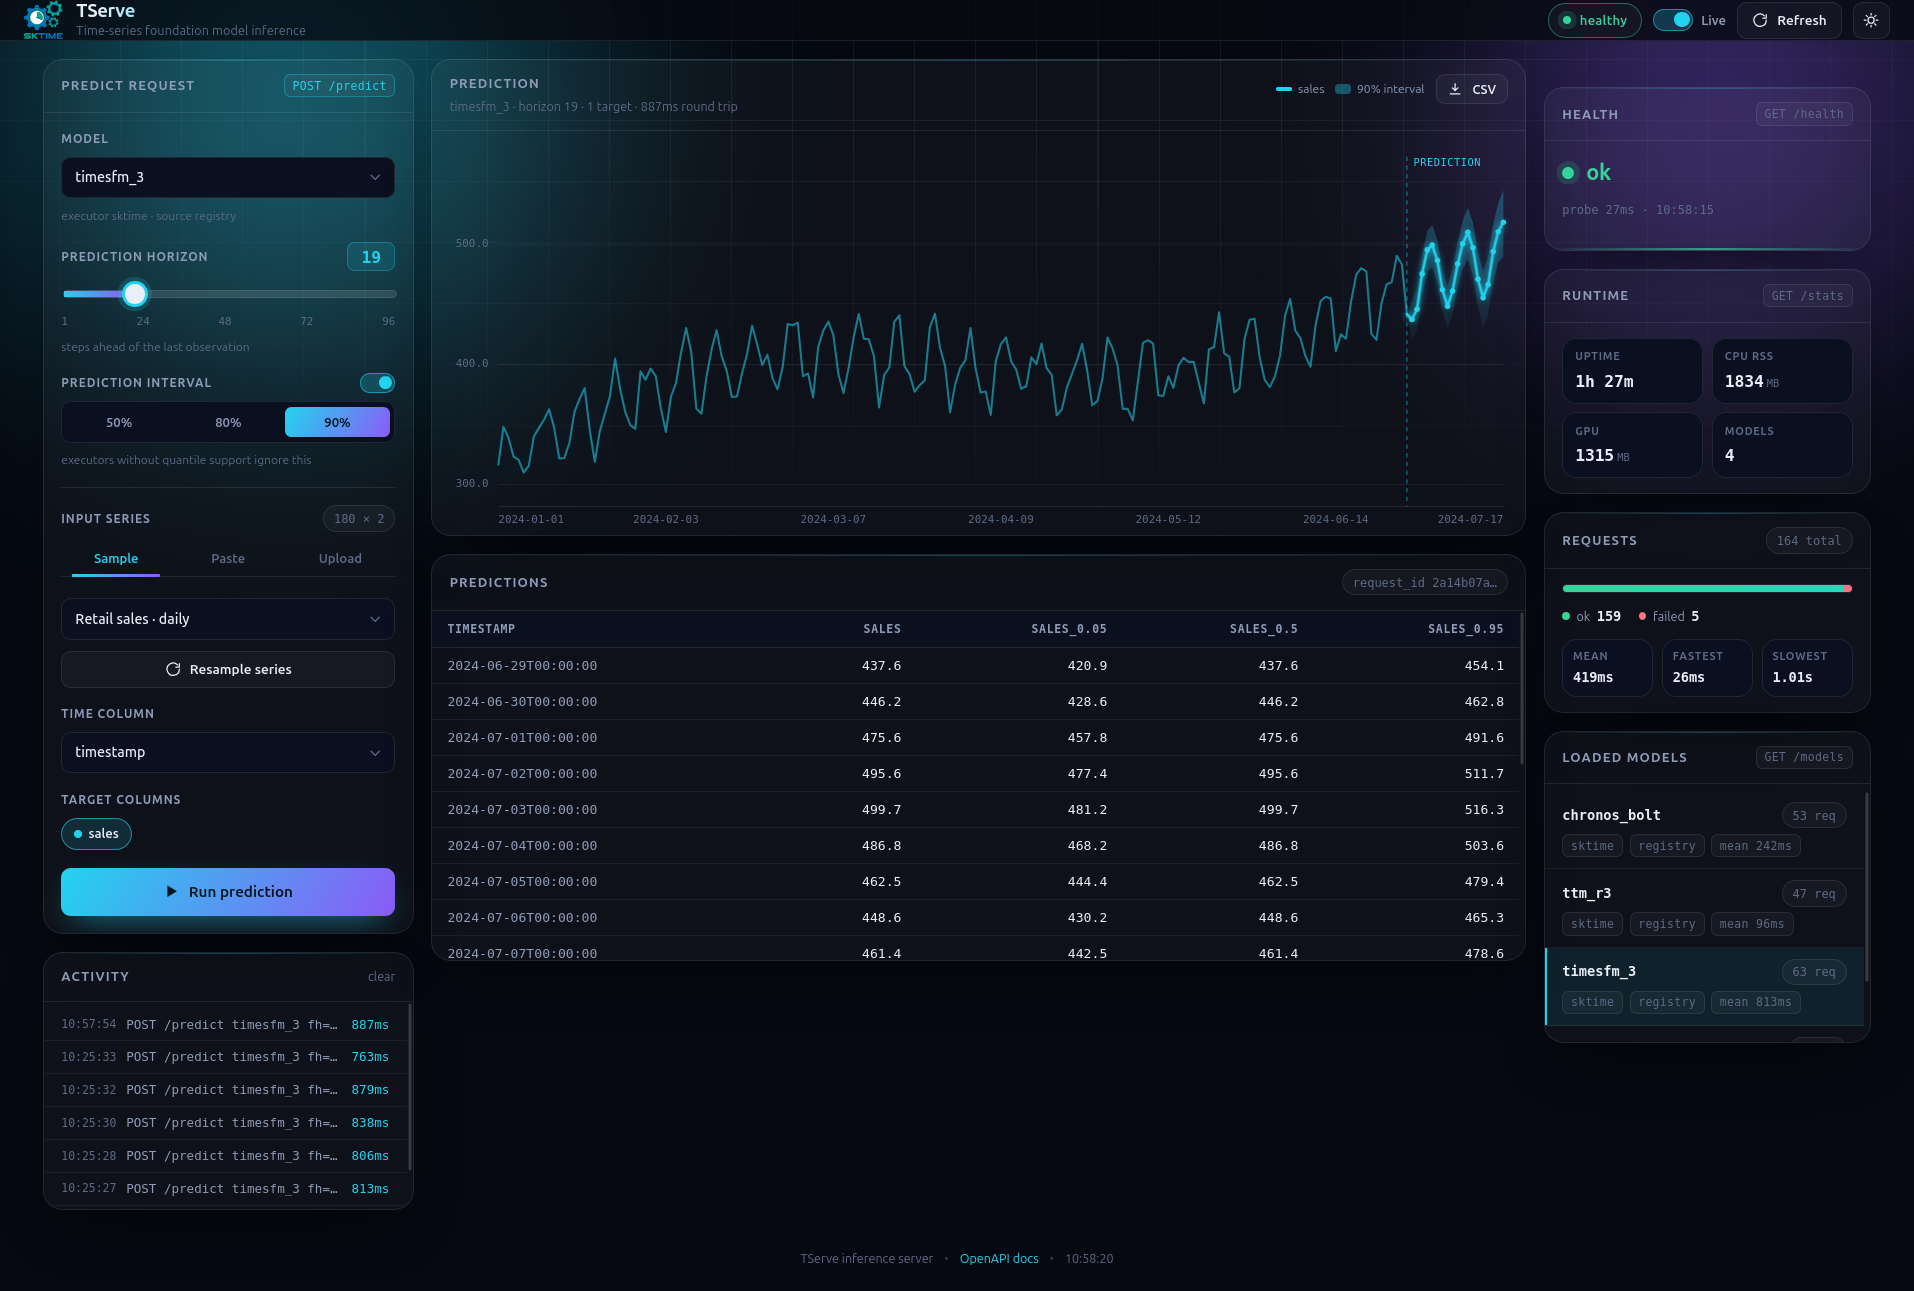
Time Series serving (TServe): local inference server for foundation models
The official JavaScript SDK for the Modzy Machine Learning Operations (MLOps) Platform.
Production-grade MLOps: Model deployment, monitoring, feature stores, and ML pipelines for real-world AI systems.
Hopsworks Machine Learning Api 🚀 Model management with a model registry and model serving
Manage heterogeneous accelerators, vGPU slicing, shared KV cache, model delivery, and inference workloads.