rocm

gpustack
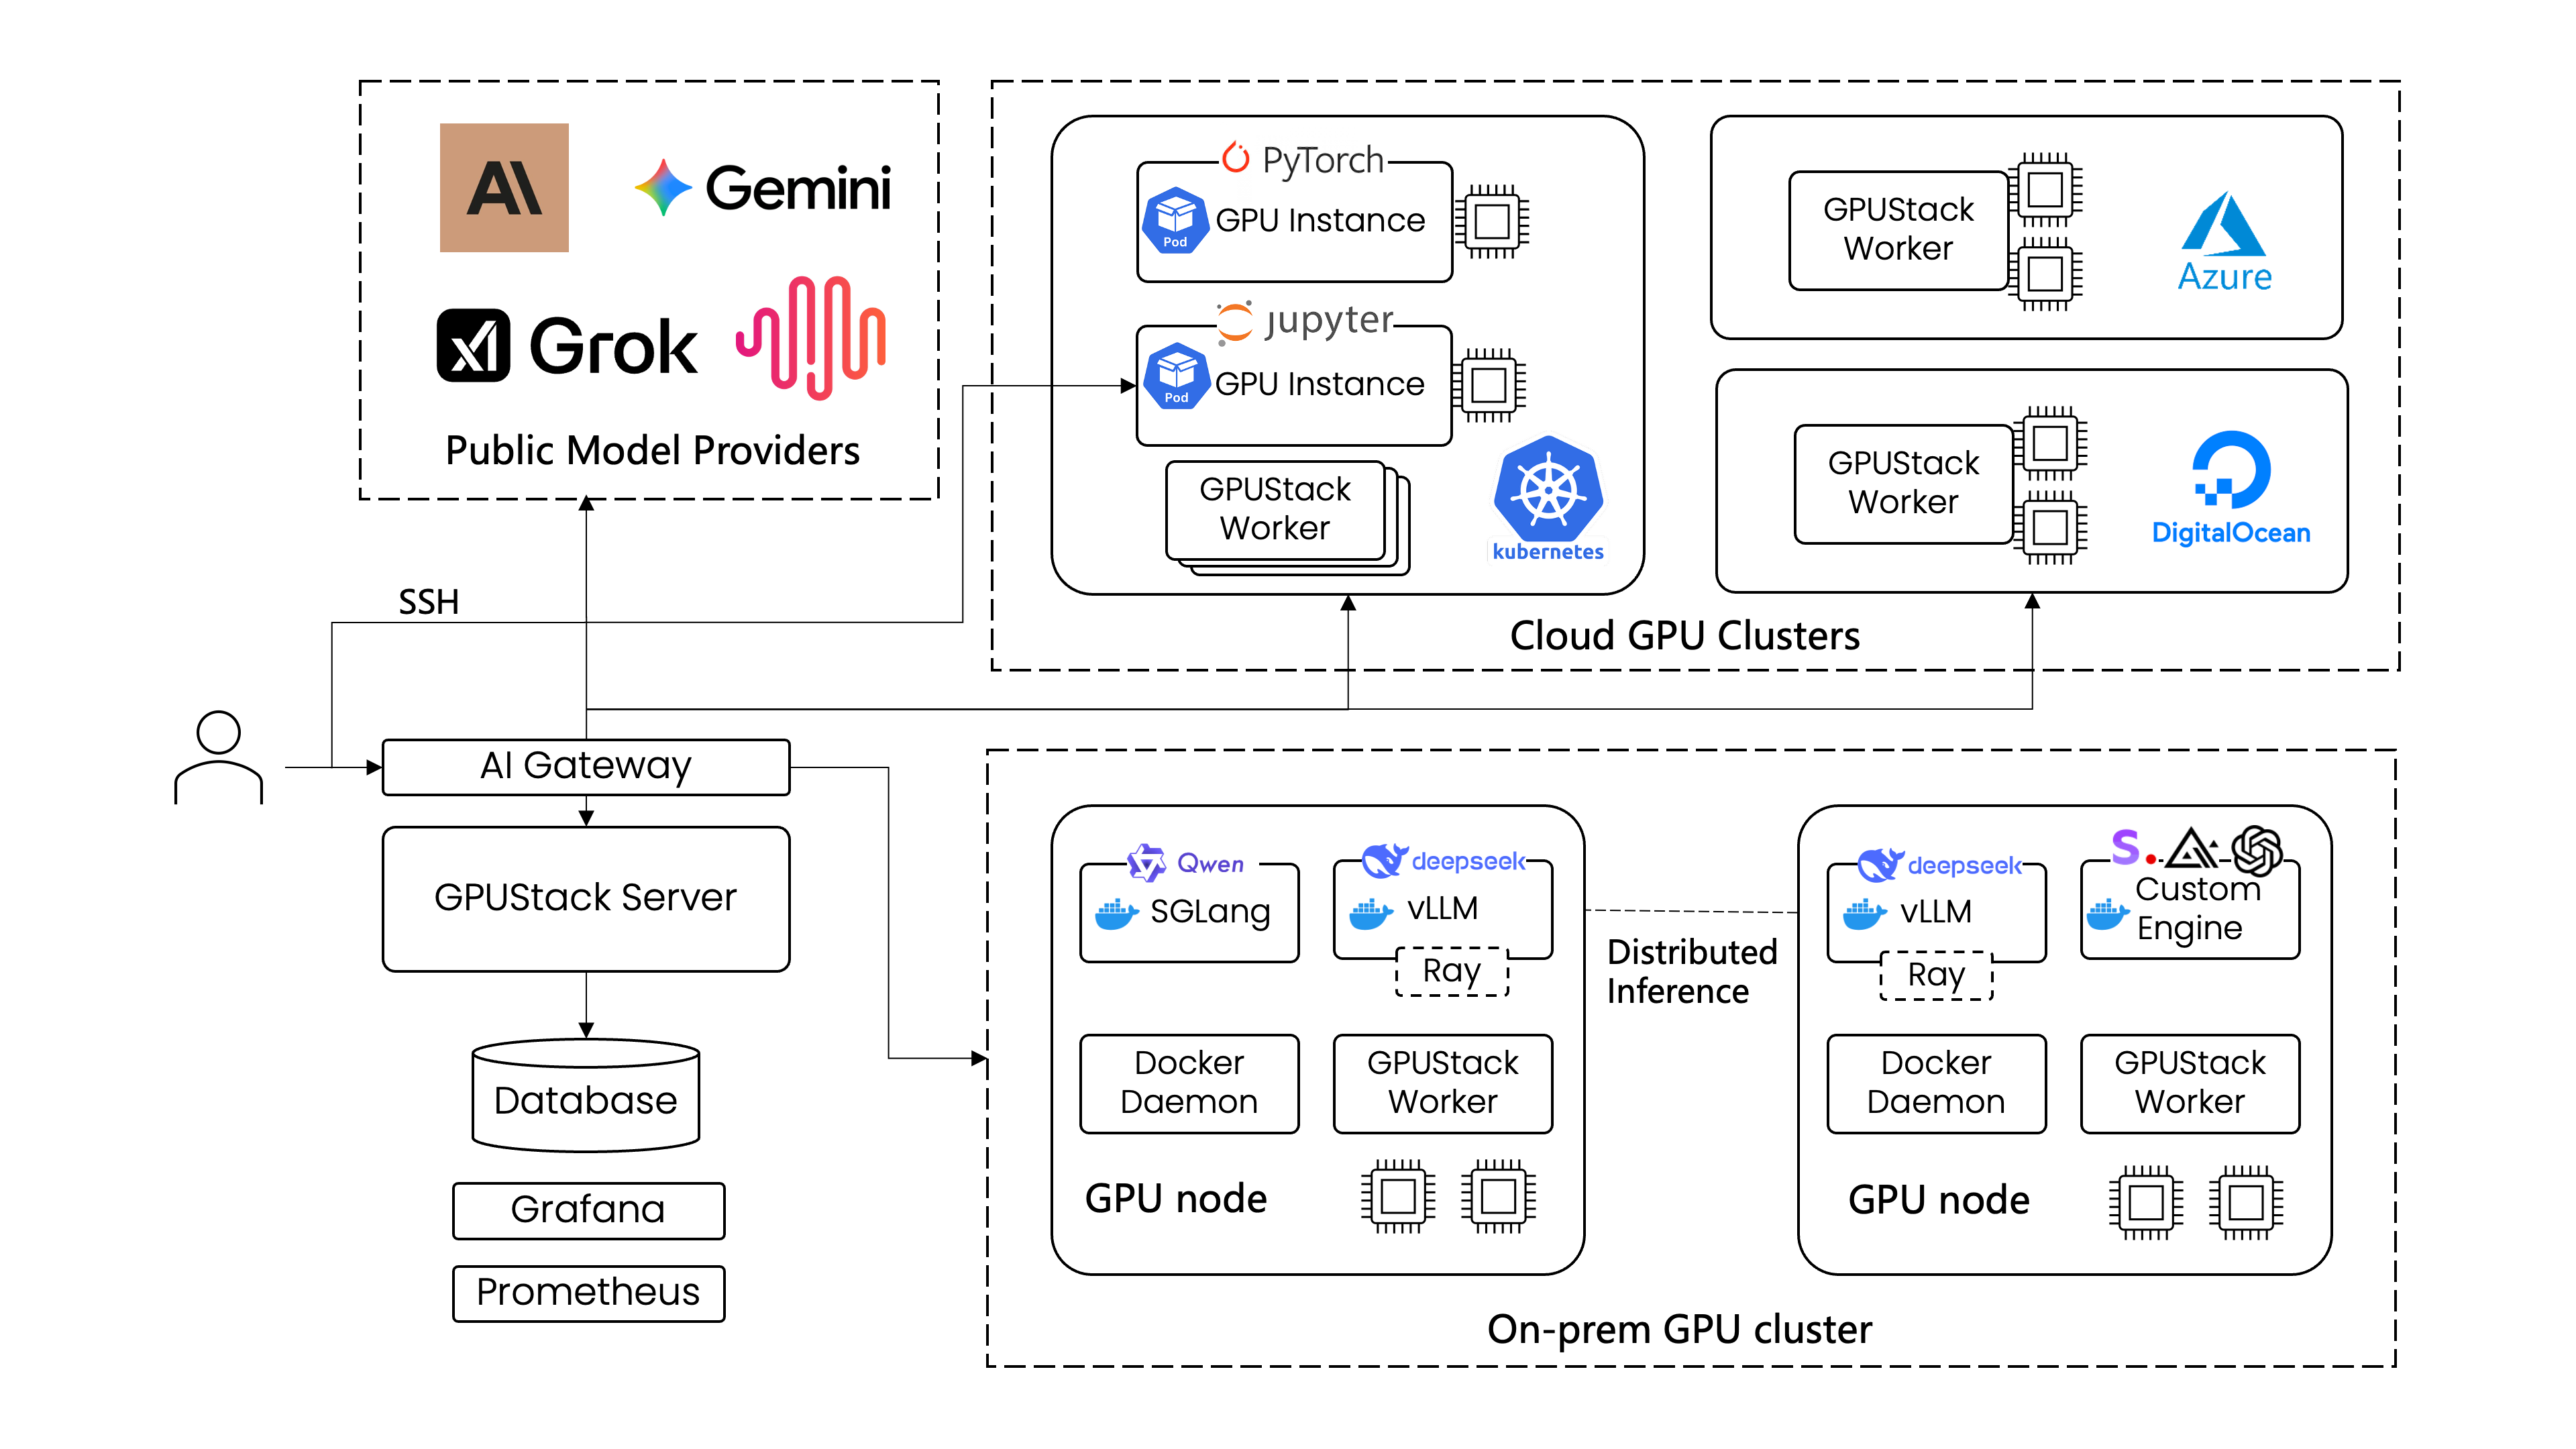
A GPU cluster manager for high-performance AI model serving (vLLM, SGLang) and on-demand SSH-accessible GPU instances.
- 6.1k
- Python
- Apache-2.0
- 11 h ago


project-maya
Run GLM-5.3 (744B), GLM-5.3-Flash (321B), DeepSeek-V4.1-Flash (748B) and MiniMax-M3.1-Flash (428B) on your own GPUs - one engine, one dashboard, OpenAI- and Anthropic-compatible API.
- 3k
- C++
- MIT
- 10 h ago

deepmd-kit
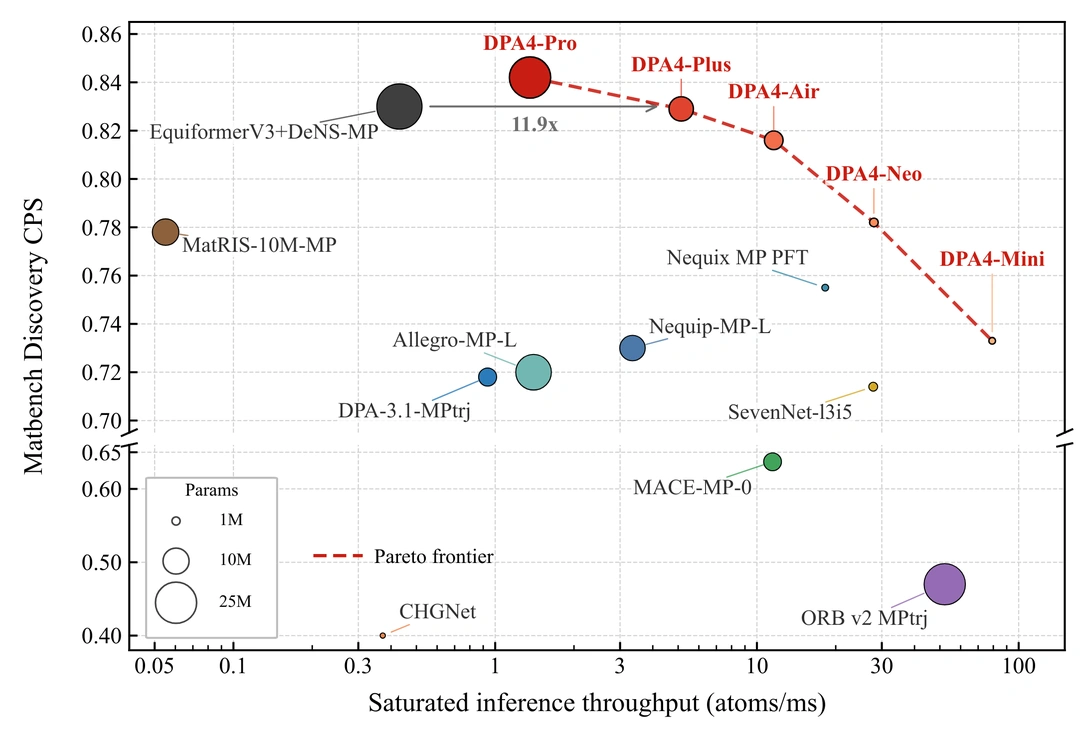
A deep learning package for many-body potential energy representation and molecular dynamics
- 2.1k
- Python
- LGPL-3.0
- 13 h ago

InferenceX
Open Source AI Accelerator Research Platform Standard / 开源推理研究平台
- 2.1k
- Python
- Apache-2.0
- 27 min ago

halogen-flash-server
Local inference that behaves like a frontier API: Qwen3.8-Flash-Next on AMD Strix Halo plus small NPU models, over the OpenAI and Anthropic APIs on one port.
- 1.4k
- Shell
- 10 h ago

inferssd
Run models larger than your RAM or VRAM by streaming MoE experts from SSD. Built on llama.cpp.
- 1.2k
- C++
- Apache-2.0
- 3 h ago

yzma
Go with your own intelligence - Write Go applications that directly integrate llama.cpp for local inference using hardware acceleration on Linux, macOS, Windows, & WebAssembly.
- 677
- Go
- 1 d ago

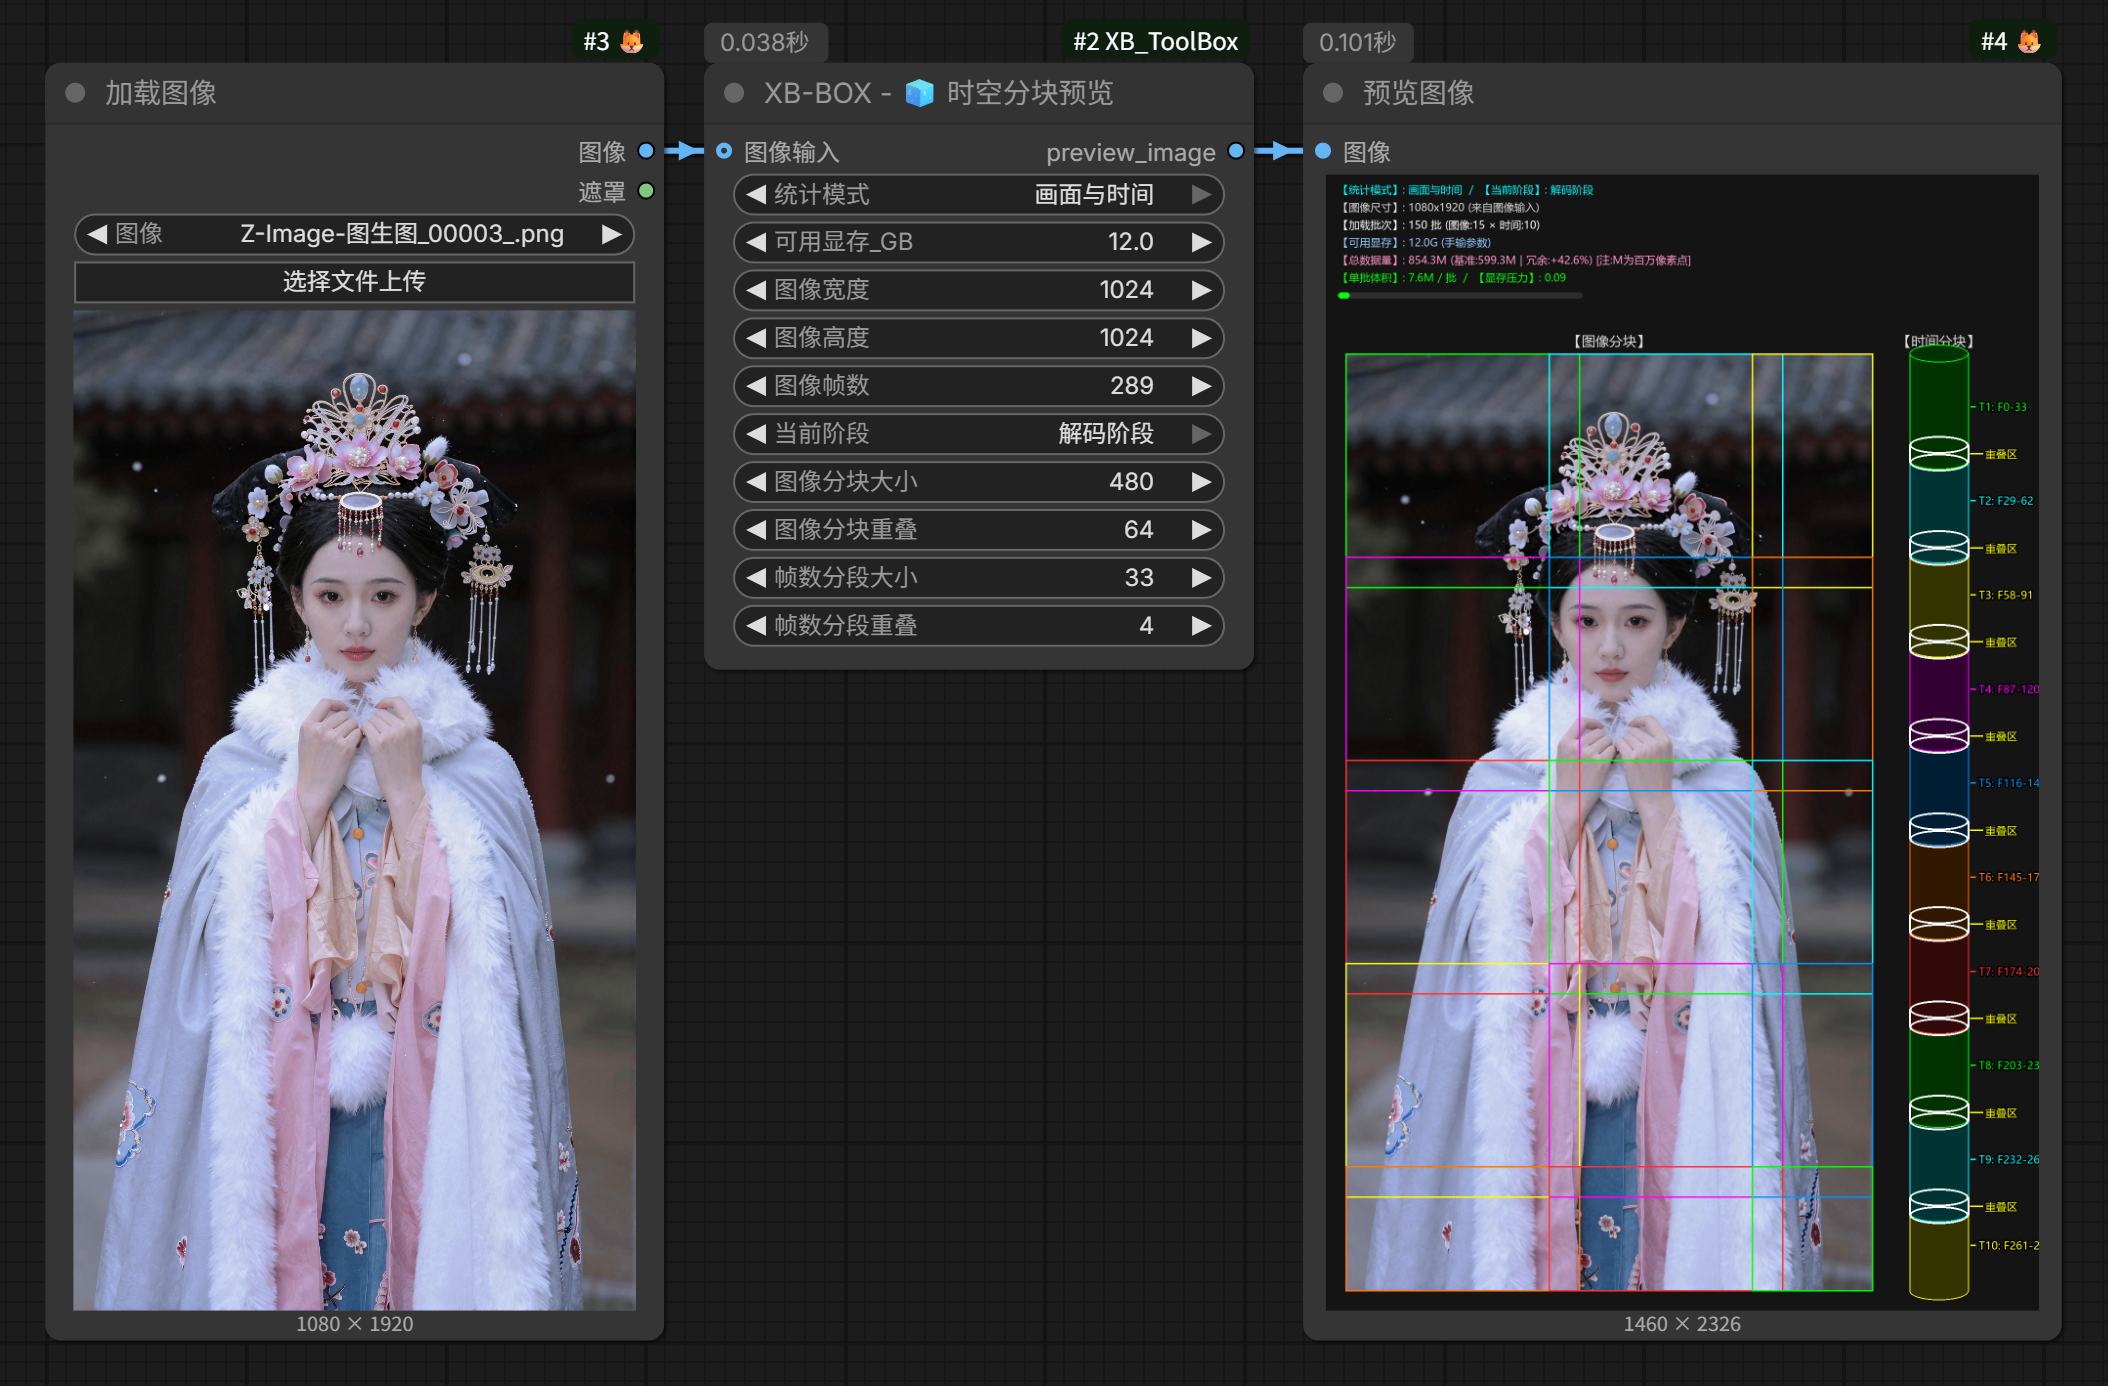
XB_ToolBox
XB_ToolBox: An easy-to-use ComfyUI custom node suite that streamlines workflow generation. Featuring exclusive data-flow logic and pioneering experimental kernel optimizations dedicated to the native AMD GPU ecosystem.
- 467
- Python
- Apache-2.0
- 2 d ago

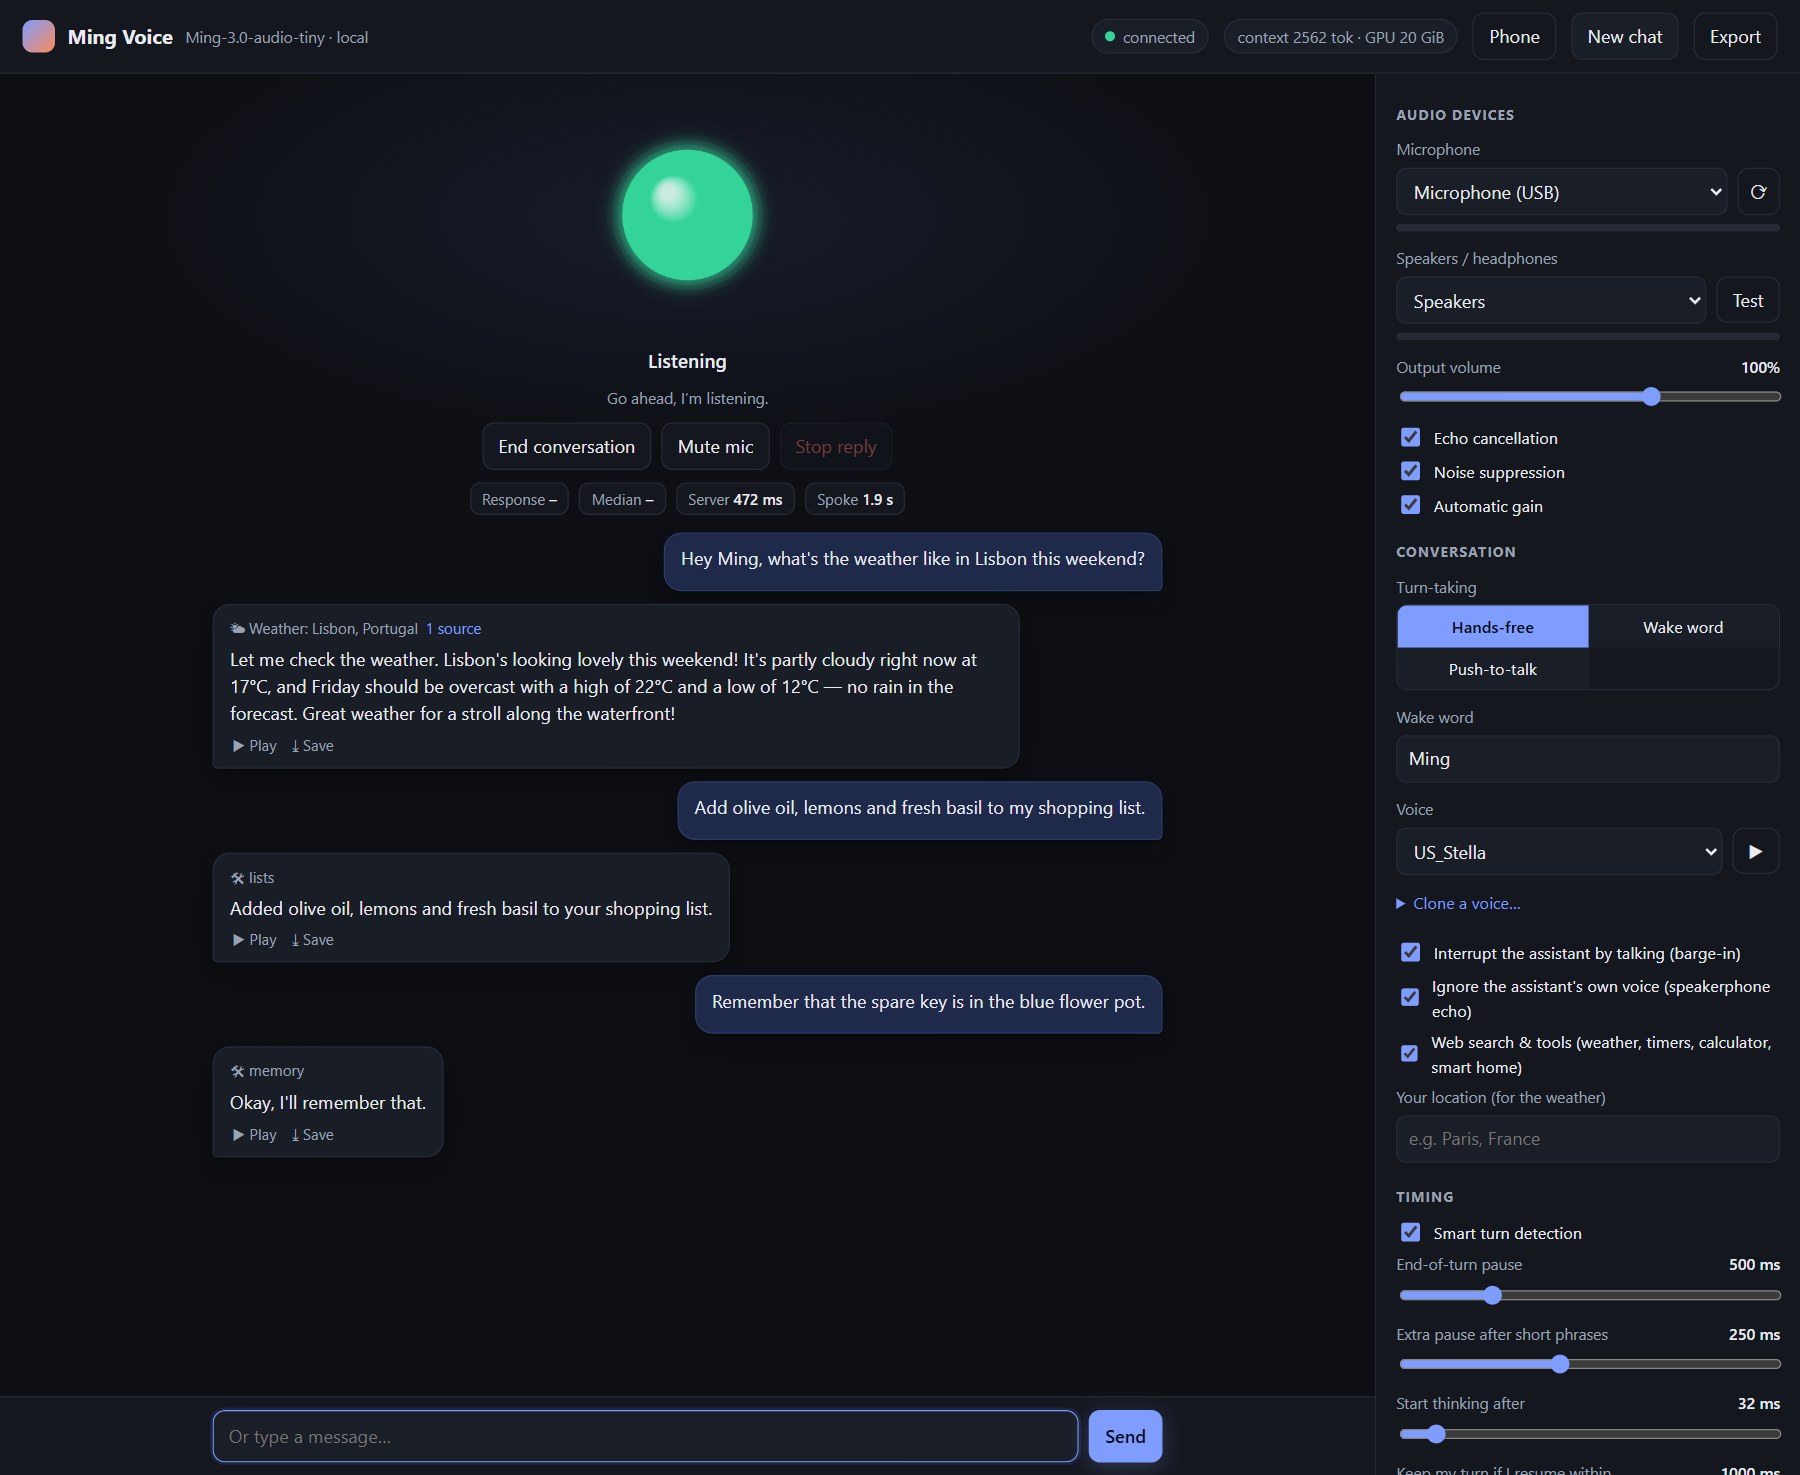
ming-voice
Low-latency local speech-to-speech voice assistant with Ming-3.0-audio-tiny on AMD and Nvidia GPUs. Easy setup on Windows and Linux
- 449
- Python
- MIT
- 5 h ago

strix-halo-guide
Evidence-backed AMD Strix Halo local-AI setup and benchmarks: Qwen3.8, Ollama, llama.cpp, Vulkan/ROCm, large GGUFs, and cross-OEM results.
- 372
- Python
- MIT
- 9 d ago

kyojin
Kyojin: open-source engine that runs 100 GB-class open models (GLM-5.3, Qwen3.8, DeepSeek V4.1) on one desktop machine. AMD Strix Halo, NVIDIA RTX and Apple Mac. OpenAI API, built on ExLlamaV3.
- 243
- Python
- MIT
- 1 d ago

llama-cpp-rdna-boosts
A set of performant RDNA/HIP patches against llama.cpp focusing on high speed inferencing with numerics assurance
- 270
- Shell
- MIT
- 3 h ago

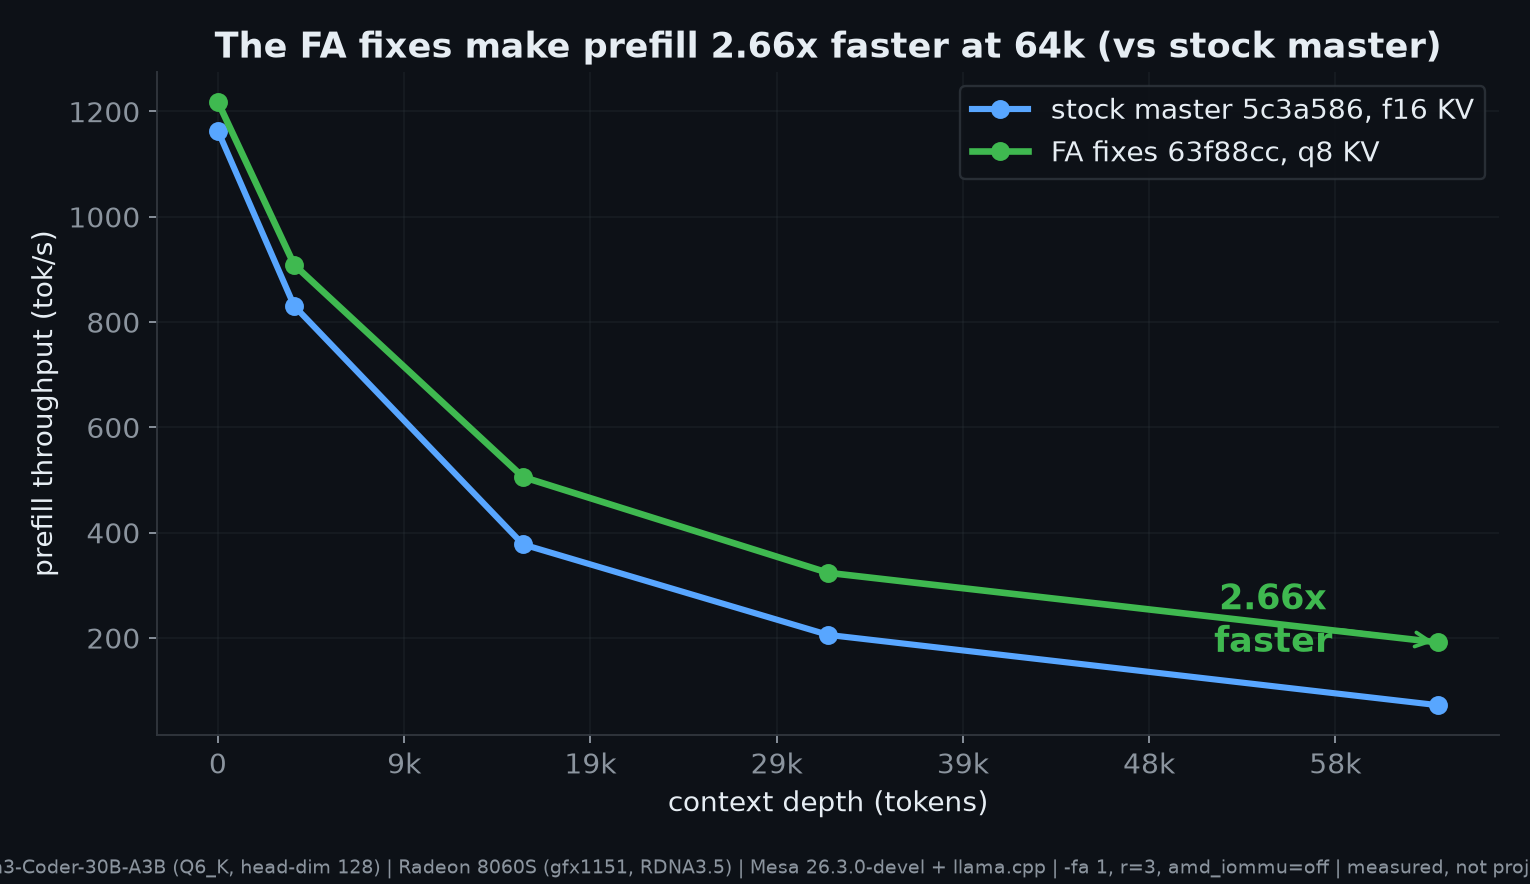
strix-halo-llamacpp
Performance-tuned llama.cpp for AMD Strix Halo (gfx1151): FA + MoE-prefill fixes with a bundled current Mesa driver. Vulkan and HIP; portable dir, Docker, and distrobox.
- 227
- Python
- 3 wk ago

MIVisionX
AMD MIVisionX is a computer vision toolkit built around a highly optimized, conformant open-source implementation of the Khronos OpenVX™ 1.3.2 specification. As of the 4.0.0 release, MIVisionX ships three components: the AMD OpenVX™ engine, the AMD RPP OpenVX extension, and the RunVX graph executor — across CPU, HIP, and OpenCL backends.
- 218
- C++
- MIT
- 3 h ago

COSMA
Distributed Communication-Optimal Matrix-Matrix Multiplication Algorithm
- 220
- C++
- BSD-3-Clause
- 3 wk ago

kindi
Kindi 0.6.1: fast local LLM inference on low-cost GPUs and CPUs. DeepSeek-V4.1-Flash (552B) at 18.7 tok/s on one RTX 3060 12 GB with a dual-Xeon DDR4 server. Ternary Bonsai 2B-27B, AH-Nanbeige4.3-33B, Nemotron 3.5 Lightning 30B-A3B. NVIDIA from the Quadro K420 to the RTX 50 series, AMD Radeon graphics, Windows and Linux. OpenAI-compatible server.
- 191
- Python
- AGPL-3.0
- 2 d ago

Qwenox
An inference framework customized for AI MAX 395, compatible with both Linux and Windows, and supports deploying only qwen3.8-flash-next. This project is for reference and learning purposes only. 为AI MAX 395定制的推理框架,Linux和Windows通用,只能部署qwen3.8-flash-next。本项目仅供参考学习使用。
- 147
- C++
- AGPL-3.0
- 11 h ago

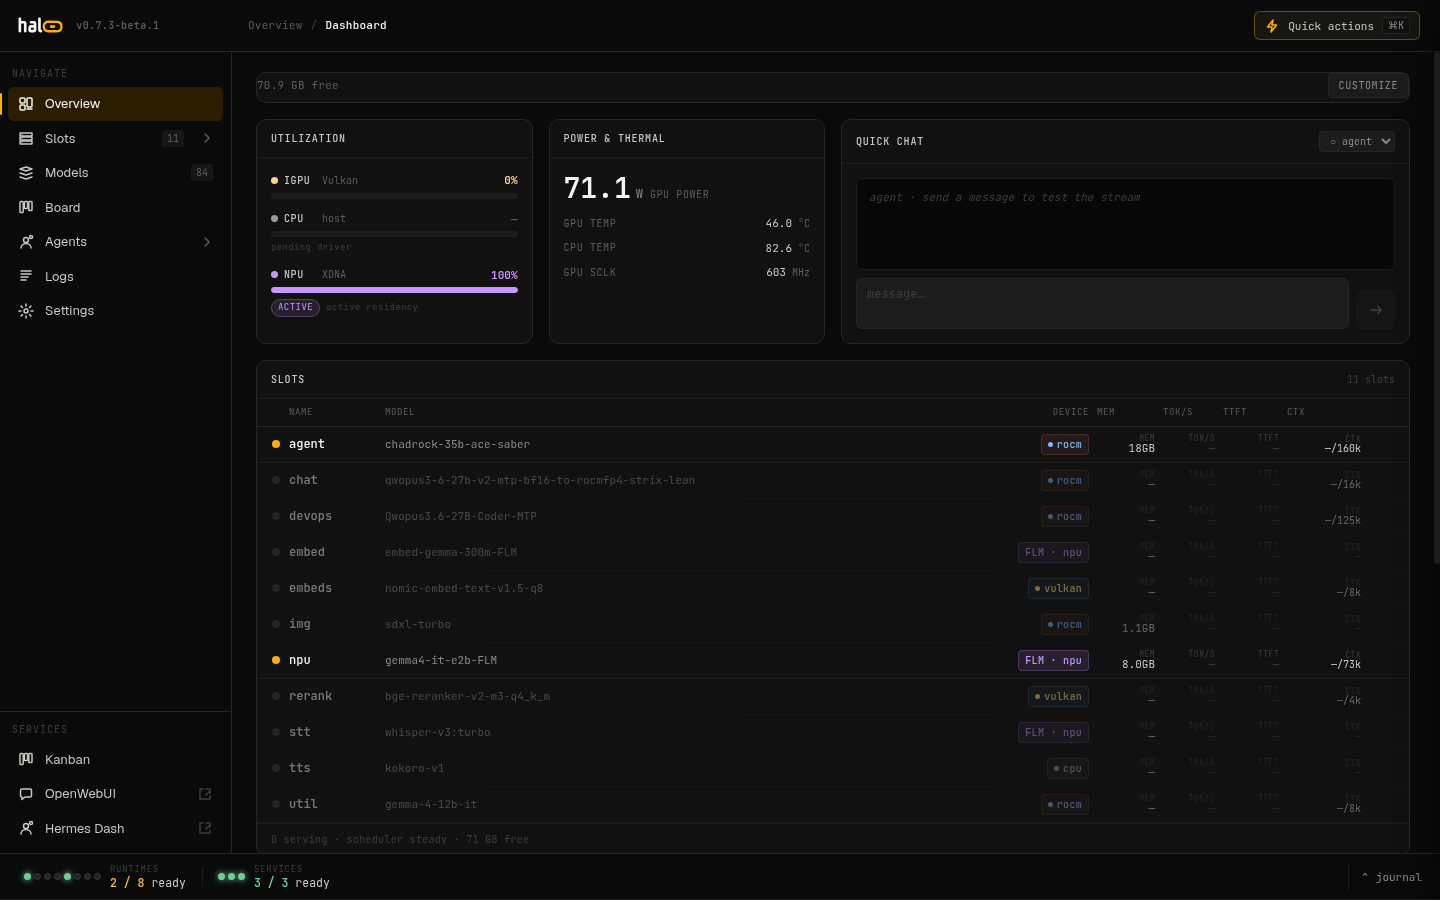
hal0
Open-source self-hosted home AI inference platform for AMD Strix Halo — multi-backend slots, OpenAI-compatible gateway, Vue 3 + FastAPI + systemd.
- 87
- Python
- Apache-2.0
- 6 h ago

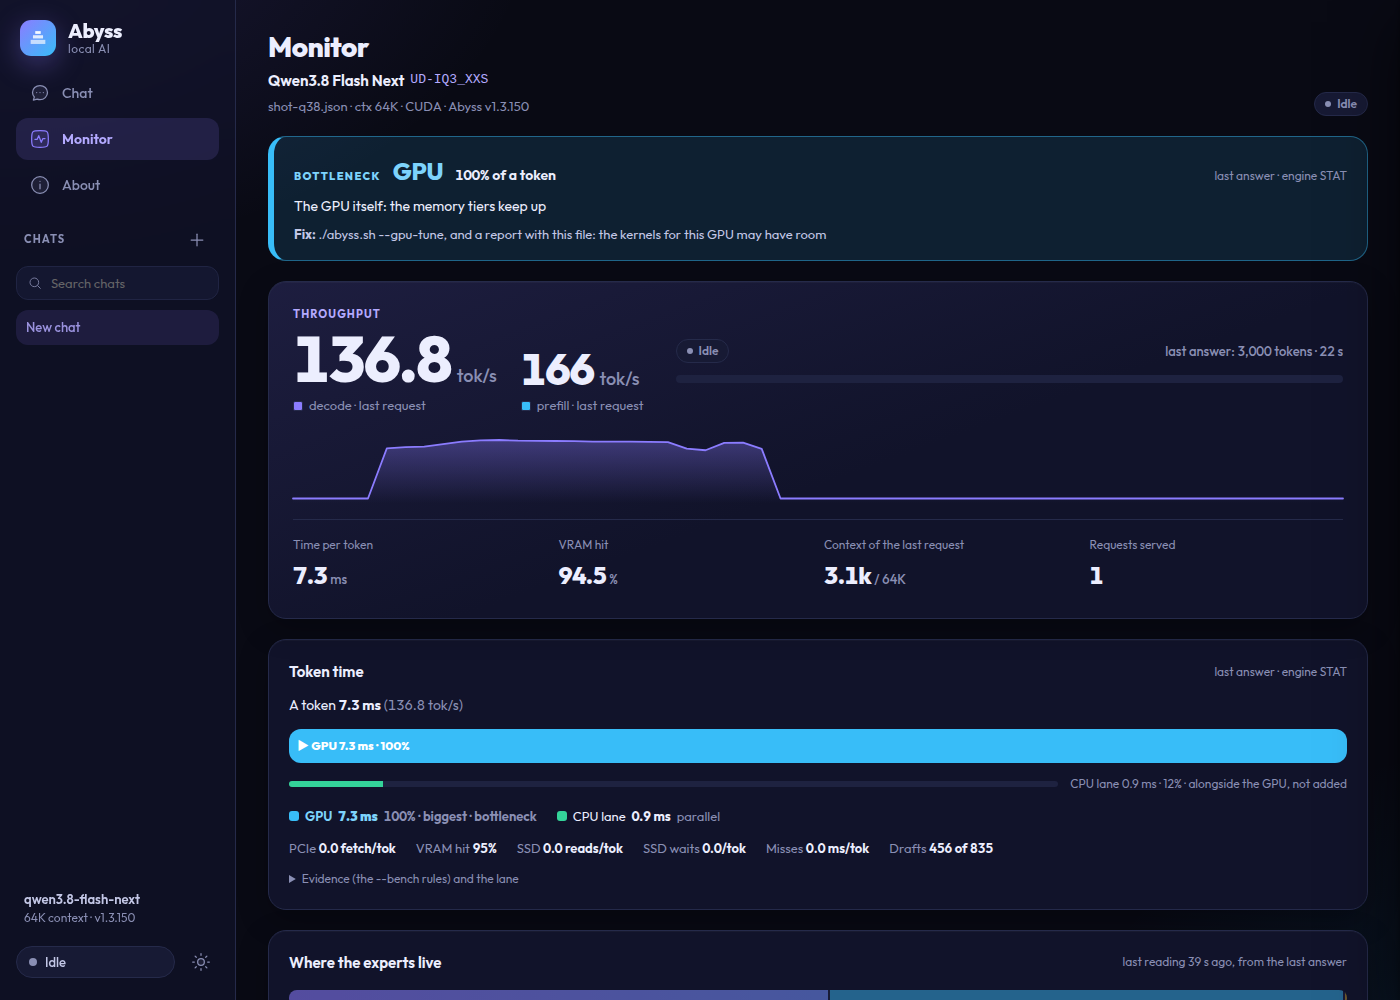
Abyss
Run 50-280 GB MoE LLMs (DeepSeek V4/V4.1 Flash, GLM-5.3-Flash, Qwen3.8-Flash-Next, Ornith) on one consumer GPU: experts spread over VRAM, RAM and NVMe SSD. Browser chat + OpenAI/Anthropic APIs. CUDA, ROCm, DGX Spark.
- 40
- C++
- MIT
- 4 h ago


radeon_compute_profiler
The Radeon Compute Profiler (RCP) is a performance analysis tool that gathers data from the API run-time and GPU for OpenCL™ and ROCm/HSA applications. This information can be used by developers to discover bottlenecks in the application and to find ways to optimize the application's performance.
- 85
- C++
- MIT
- 6 y ago

strix-halo-llm
DeepSeek-V4.1-Flash (1M context) and GLM-5.3-Flash on a BOSGAME M5 (Ryzen AI Max+ 395, Radeon 8060S, 128 GiB) with two RX 7900 XTX over OCuLink: pinned Ansible recipes and measured results. Also the M5-only Qwen and DeepSeek setups.
- 33
- Python
- MIT
- 5 h ago


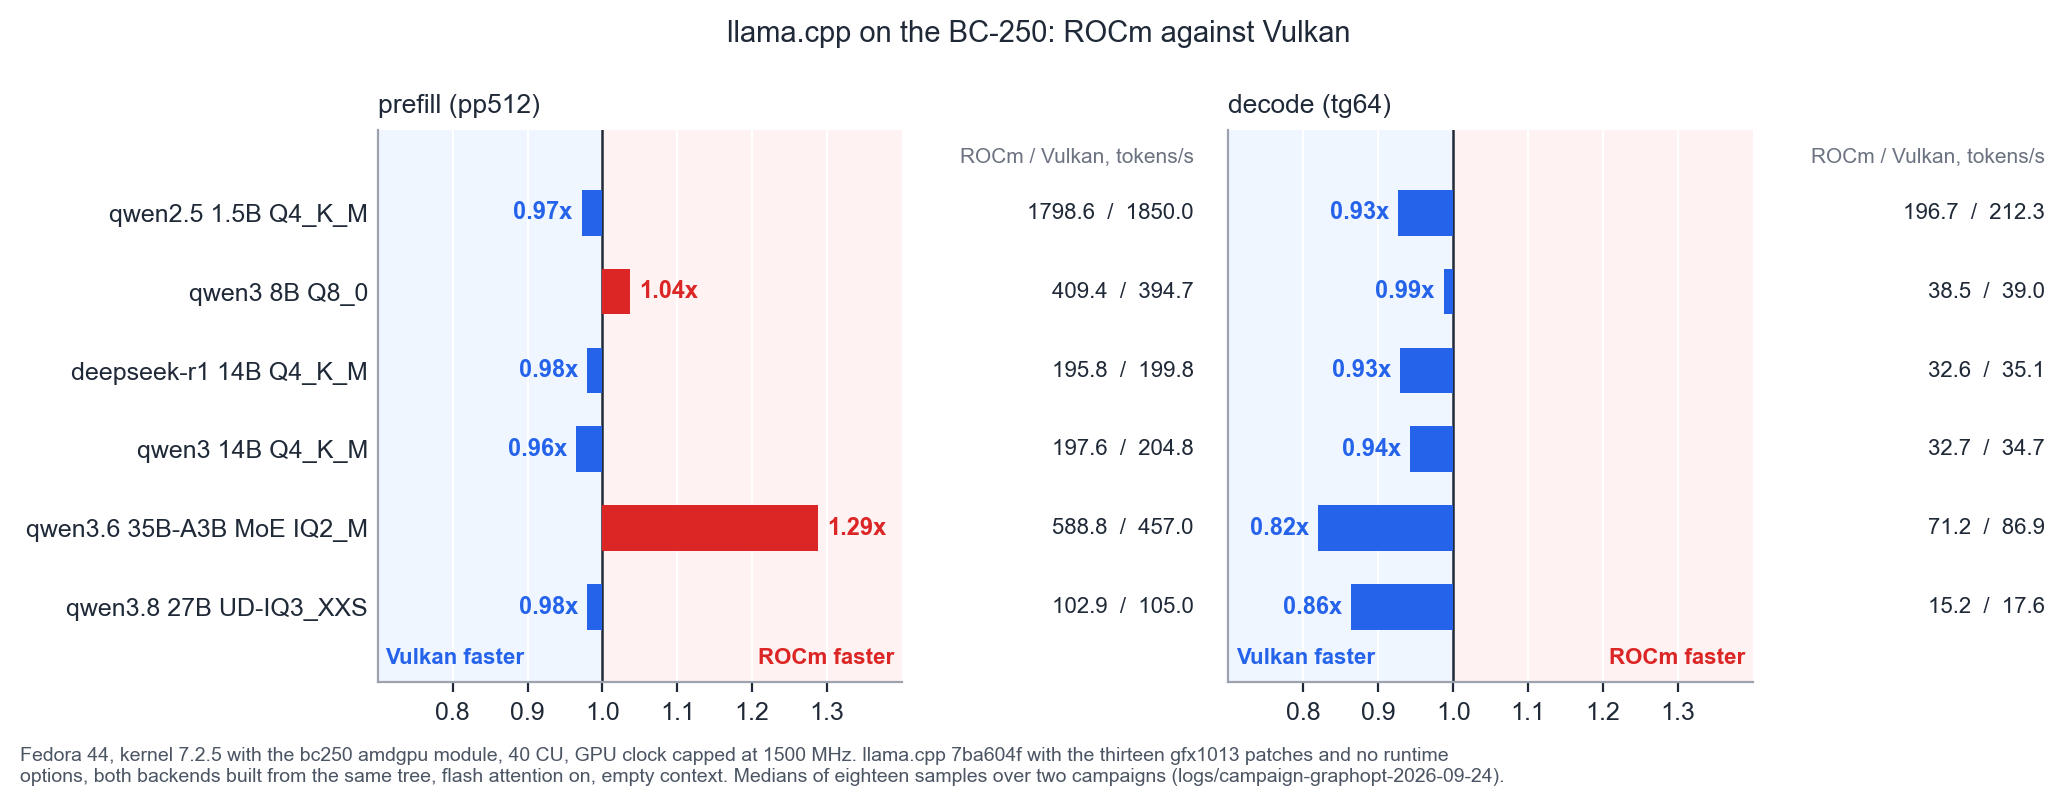
bc250-rocm
ROCm/HIP investigation on the AMD BC-250 (gfx1013 Cyan Skillfish), with a Vulkan comparison
- 29
- Shell
- 10 d ago

llama-vulkan-strix
Docker Compose for llama.cpp GGUF servers on AMD Strix Halo: Qwen, Gemma, and Laguna packages (abliterated and quantized), stock Vulkan plus ROCmFP4/MTP and ROCmFPX, parallel slots, with prefill/decode and quality metrics measured on this rig.
- 28
- Python
- 3 mo ago

libstrix
Fast vLLM on AMD Strix Halo: one docker command for Qwen, Gemma, LFM and more, up to 31x faster prefill and ~2x decode vs stock vLLM at long context.
- 22
- Python
- MIT
- 4 h ago

local-llm-benchmarks
Measured llama.cpp benchmarks on AMD Radeon RDNA4 with ROCm: RX 9070 XT + Radeon AI PRO R9700 (48 GB). Qwen3.8, Gemma 4, GLM, gpt-oss; GGUF quant quality (KLD), MTP speculative decoding, 128K context, Claude Code with local models.
- 18
- Python
- MIT
- 5 d ago

ComfyUI-CiruImageAccelerator
Qwen Image 2.1 Turbo Prediction and Strix Halo attention for ComfyUI
- 18
- Python
- GPL-3.0
- 8 wk ago

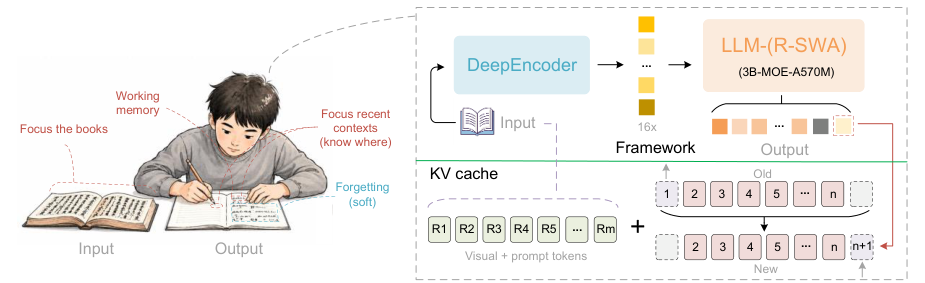
Unlimited-OCR-ROCm
Run Baidu Unlimited-OCR on AMD GPUs at 56 tok/s with zero accuracy loss — one command. Only 16GB VRAM required.
- 16
- Python
- MIT
- 4 mo ago


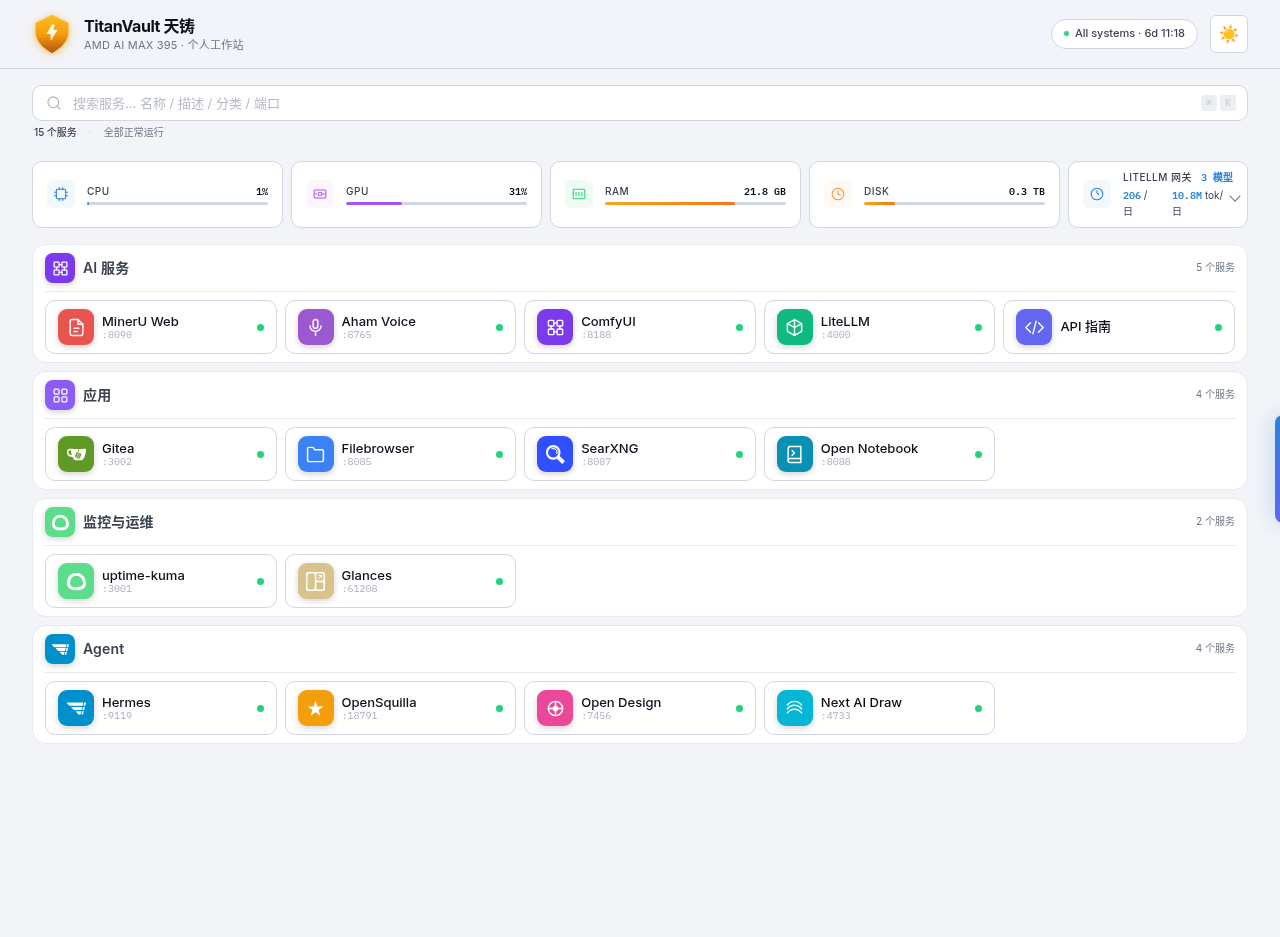
TitanVault
A turnkey, fully-local AI workstation engineered for the AMD Ryzen AI Max+ 395. LLM inference, voice, document parsing, browser automation, agents — all on-device.
- 7
- Python
- Apache-2.0
- 4 mo ago

navimed-umb
AWQ/W4A16 quantization, benchmarking and public release of Polish LLMs (PLLuM, Bielik) on AMD RDNA 4 (ROCm + vLLM-native) — reproducible methodology and hardware-envelope studies.
- 4
- Python
- CC-BY-4.0
- 3 d ago

beam
Pure-Python drop-in subset of Ray's API that makes vLLM distributed inference work across nodes. ~1,400 LoC, one dependency, bind-mount into the stock vLLM image. NVIDIA + AMD, validated cross-node.
- 2
- Python
- AGPL-3.0
- 5 wk ago

battle-game-agent-battle-grpo
- 2
- 11
- apache-2.0
- 3 mo ago
spmv-csr-triton-gpu-kernels
- 0
- 0
- other
- 2 mo ago