awesome-vlm-architectures
Curated visual catalog of 200+ vision-language model (VLM/MLLM) architectures: papers, diagrams, training recipes, datasets, and a release timeline for multimodal AI agents.
- 1.4k
- Markdown
- CC0-1.0
- 4 wk ago
Curated visual catalog of 200+ vision-language model (VLM/MLLM) architectures: papers, diagrams, training recipes, datasets, and a release timeline for multimodal AI agents.
Open, source-backed catalog of computer-use agents: reviewed papers, GUI models, datasets, benchmarks, tools, and reusable JSONL/SQLite data.
An open-weight 11B model series for long-form and real-time video understanding
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository. Continuous updates.
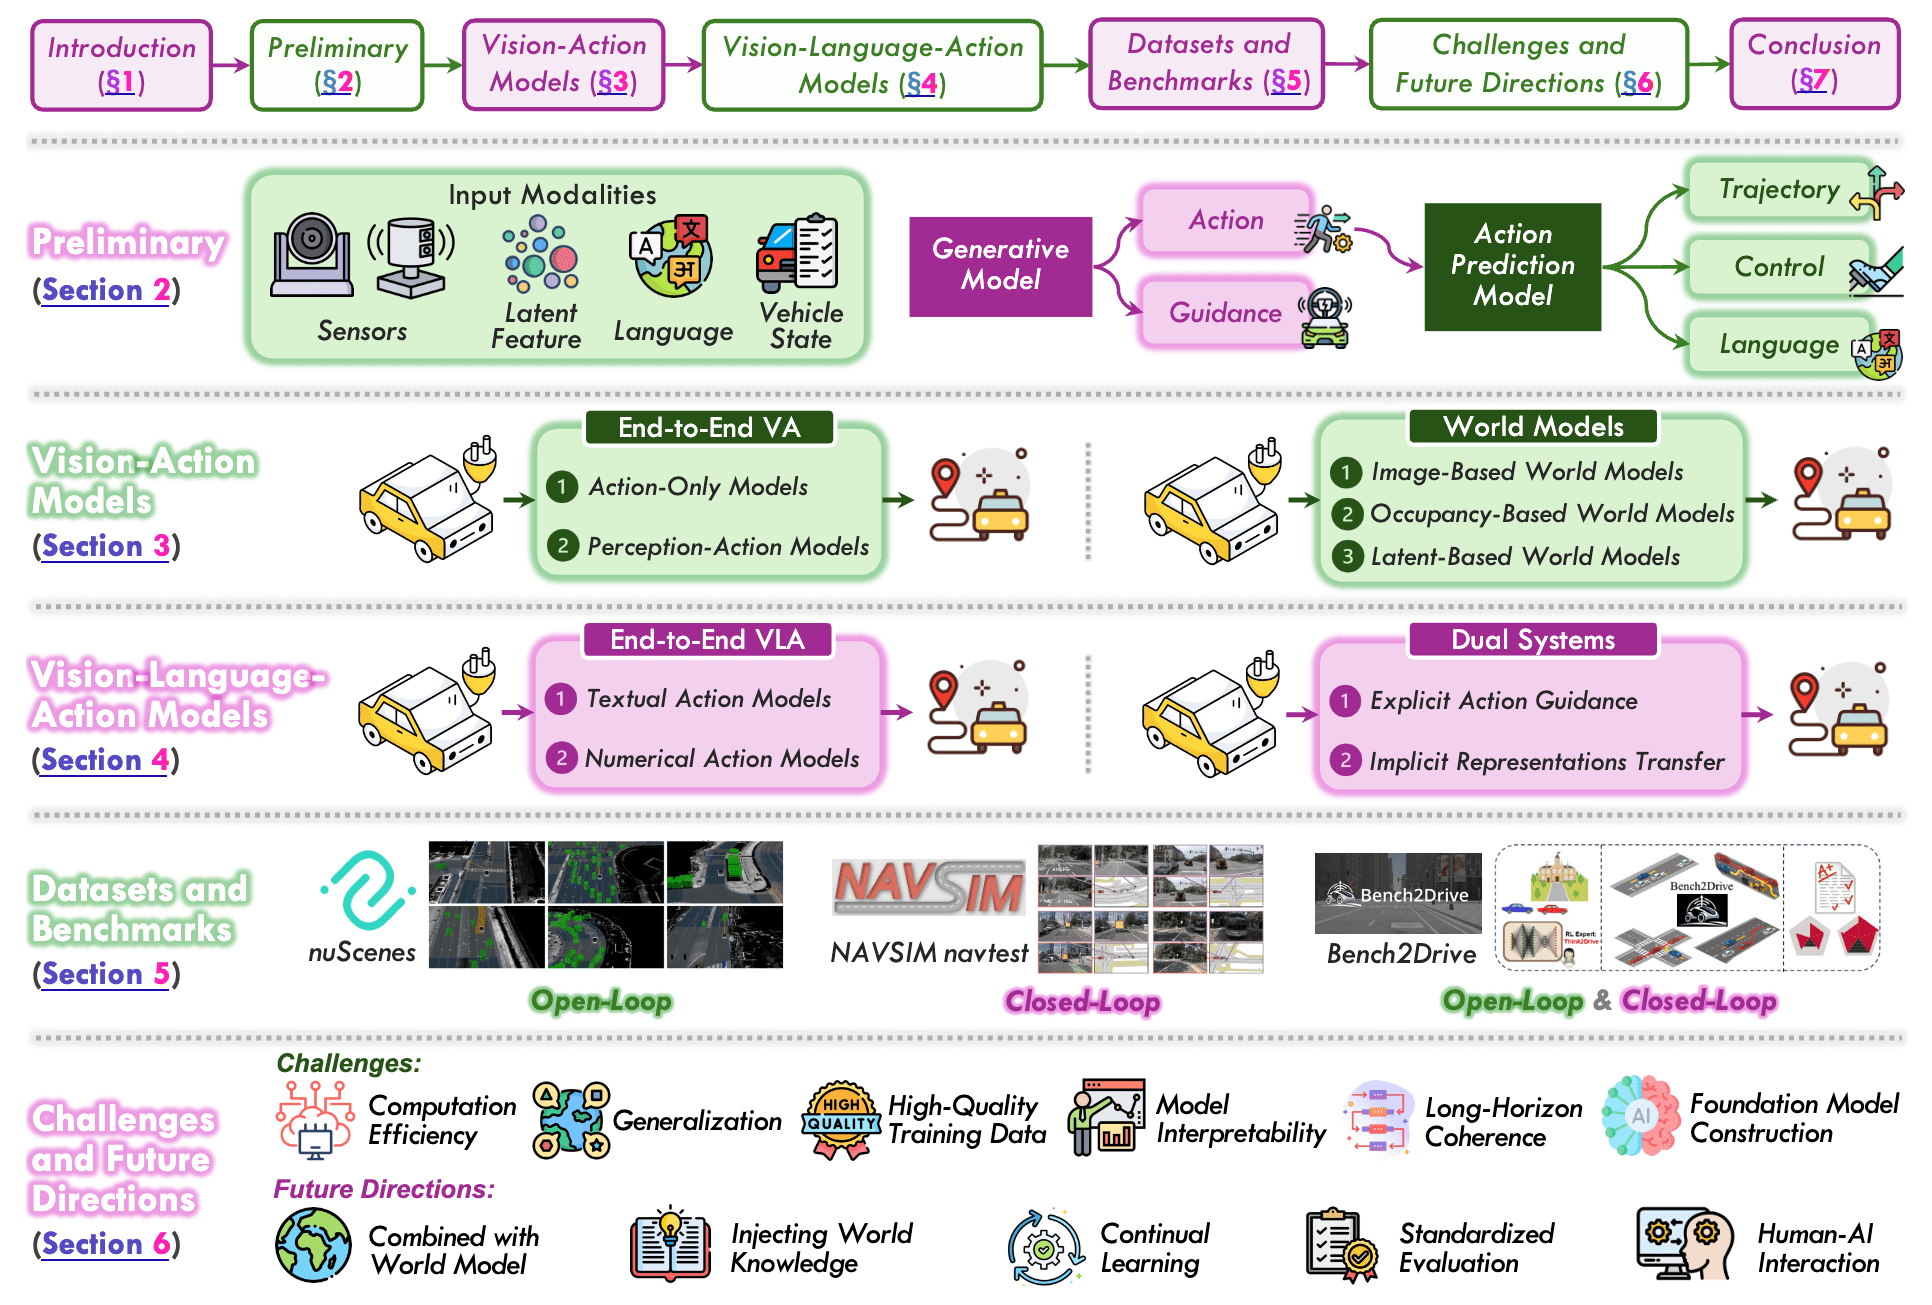
🌐 Vision-Language-Action Models for Autonomous Driving: Past, Present, and Future
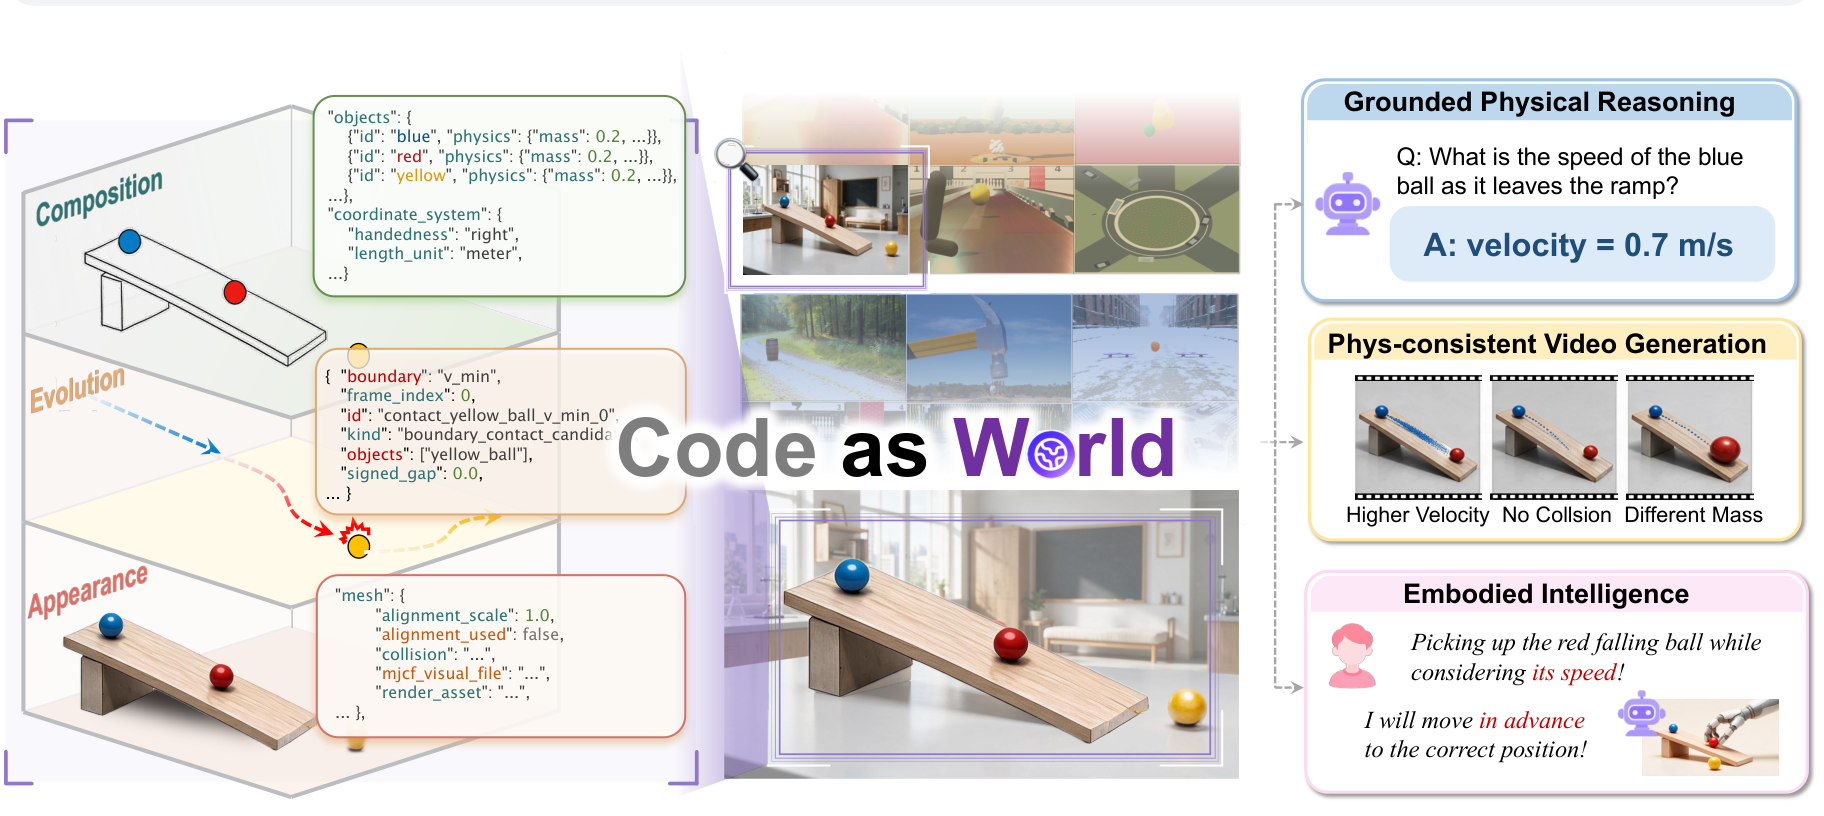
Code as World: Agentic Discovery of Executable World Representations for Physical Reasoning
up-to-date curated list of state-of-the-art Large vision language models hallucinations research work, papers & resources
[ICCV 2025] Are VLMs Ready for Autonomous Driving? An Empirical Study from the Reliability, Data, and Metric Perspectives
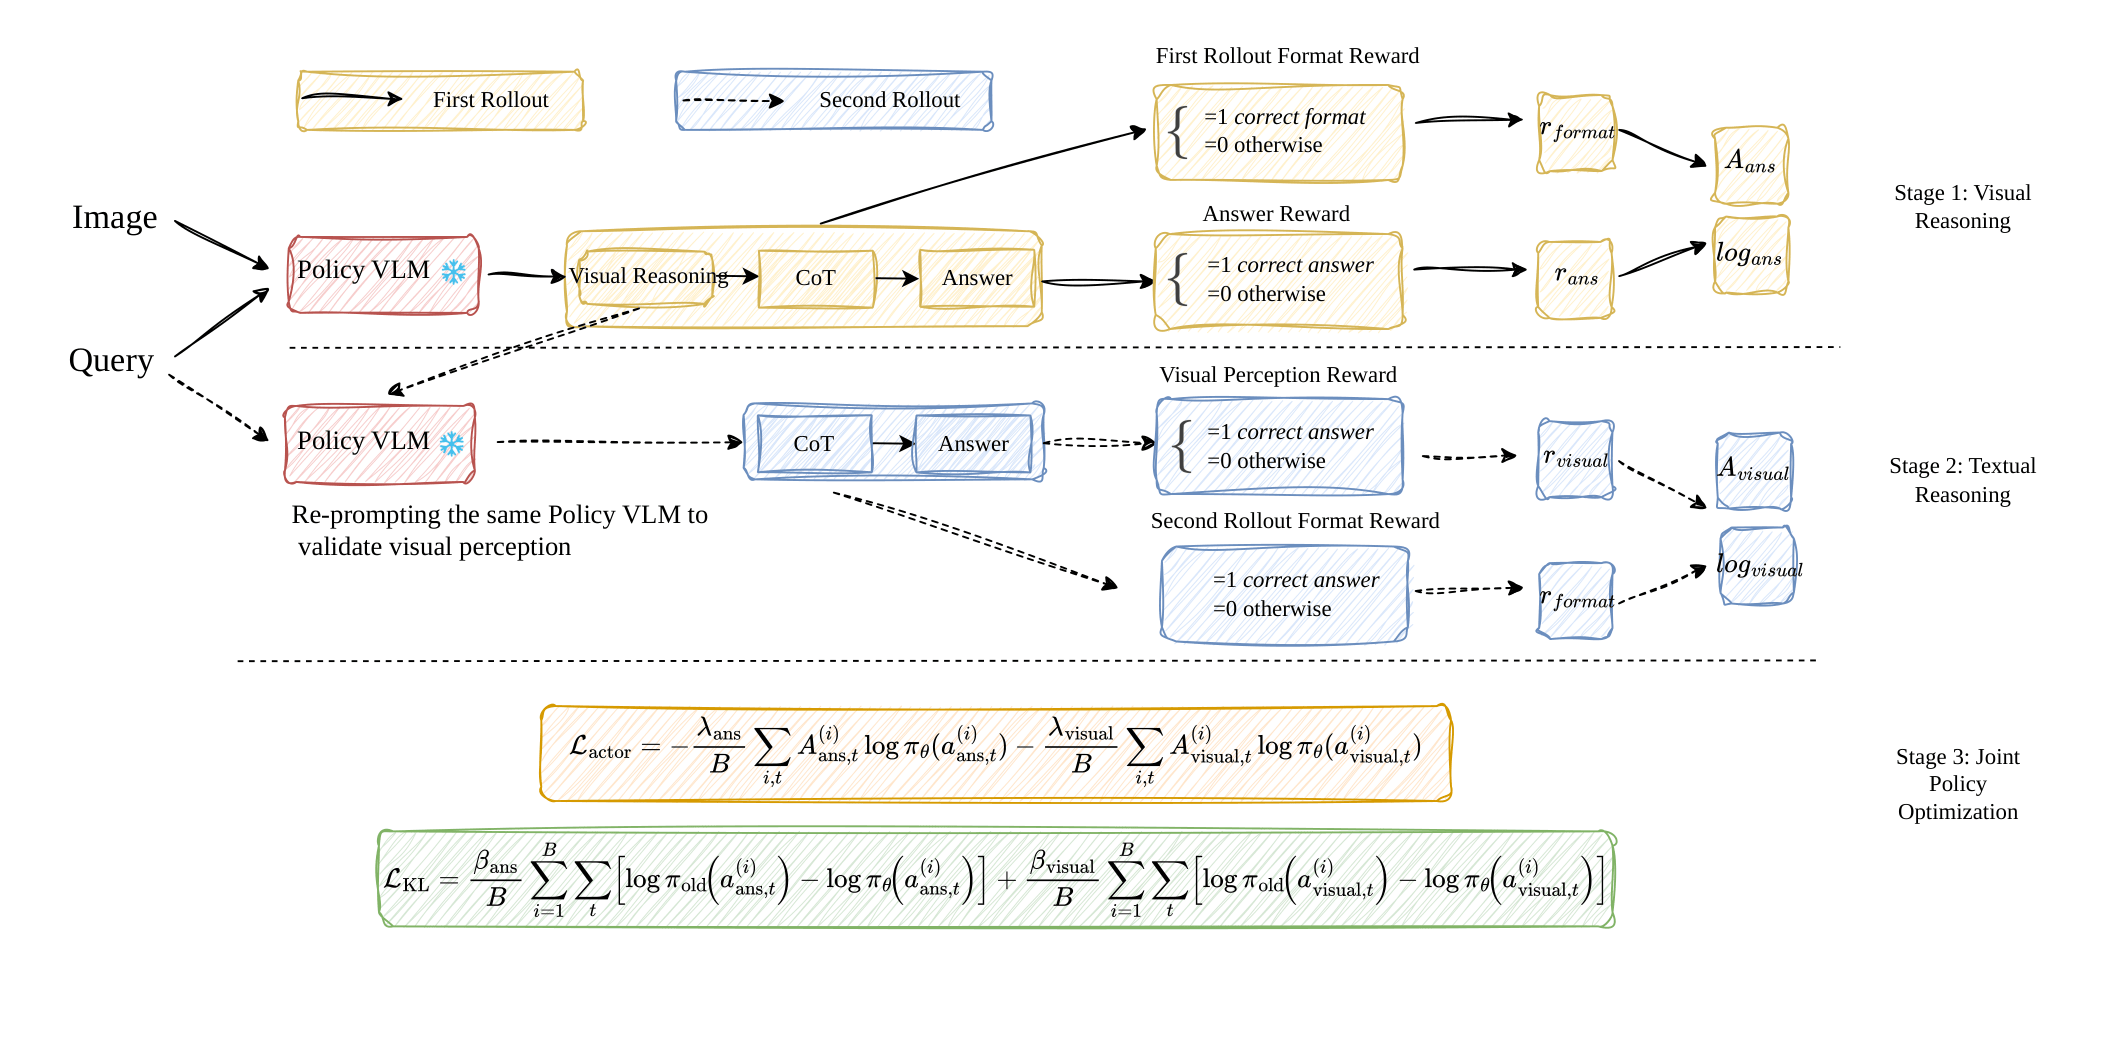
Reinforcement Learning of Vision Language Models with Self Visual Perception Reward
🌐 Forging Spatial Intelligence: A Roadmap of Multi-Modal Data Pre-Training for Autonomous Systems
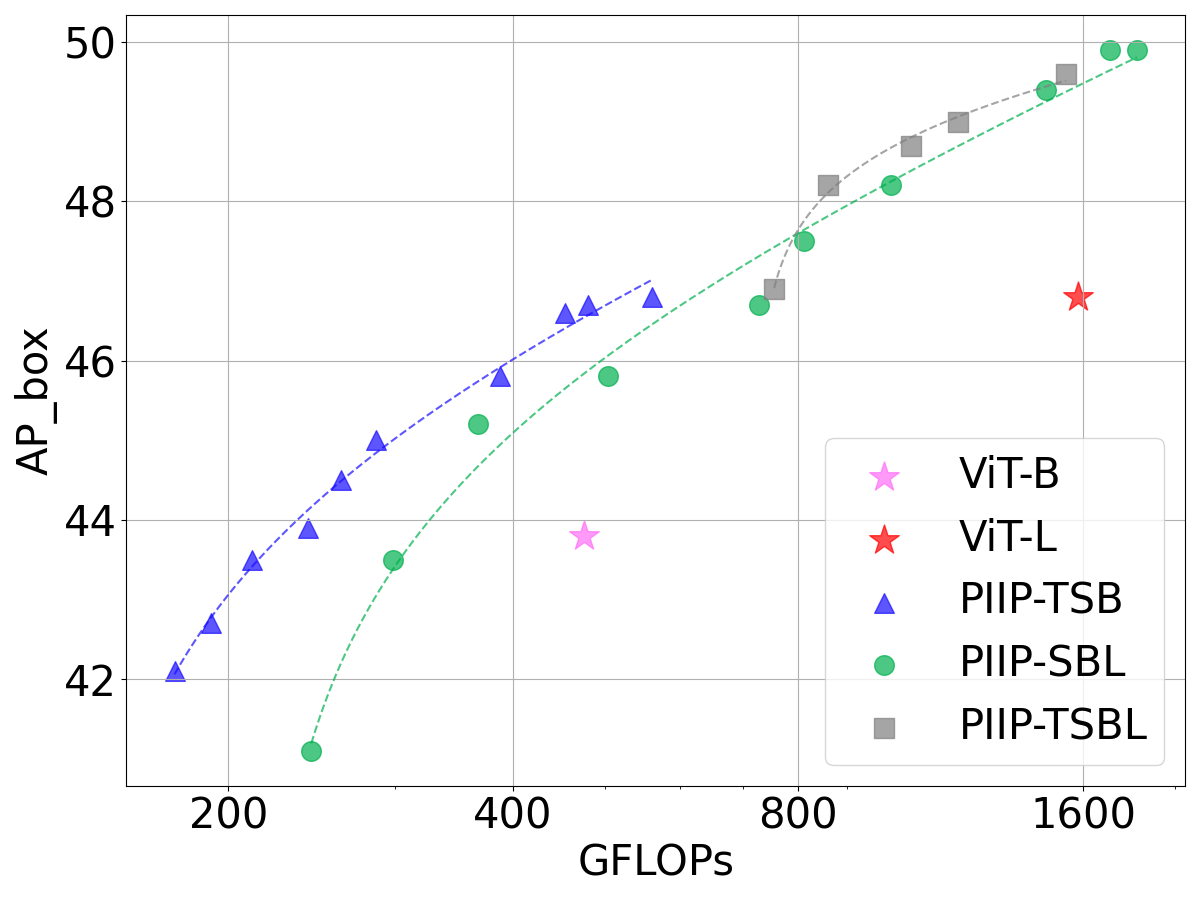
[NeurIPS 2024 Spotlight ⭐️ & TPAMI 2025] Parameter-Inverted Image Pyramid Networks (PIIP)
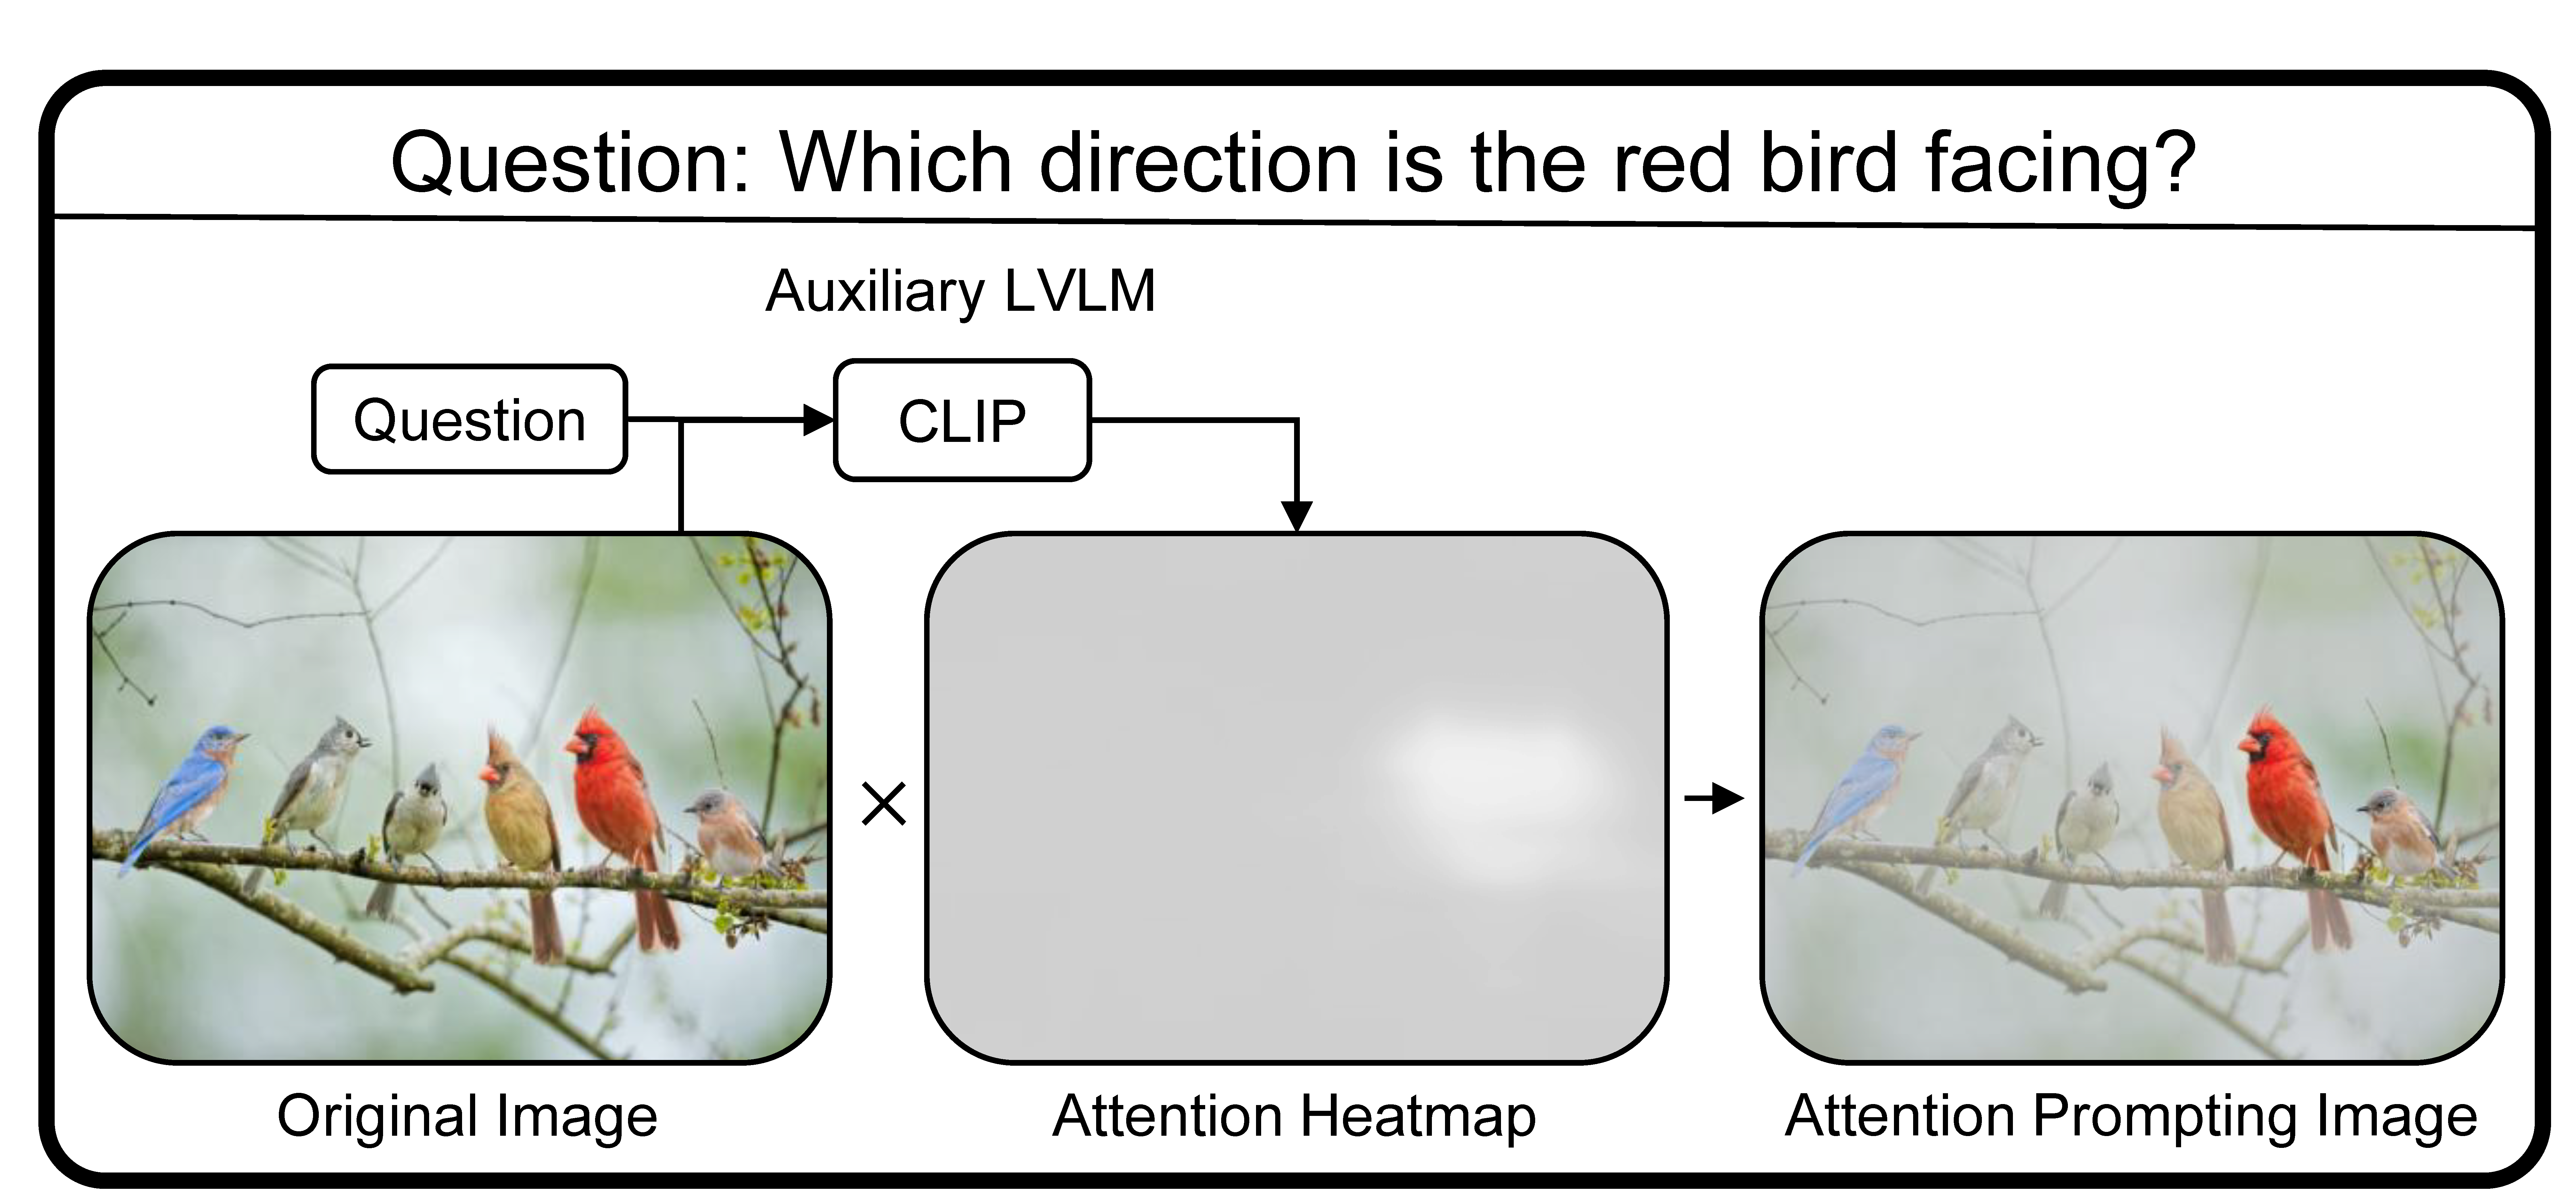
[ECCV 2024] API: Attention Prompting on Image for Large Vision-Language Models
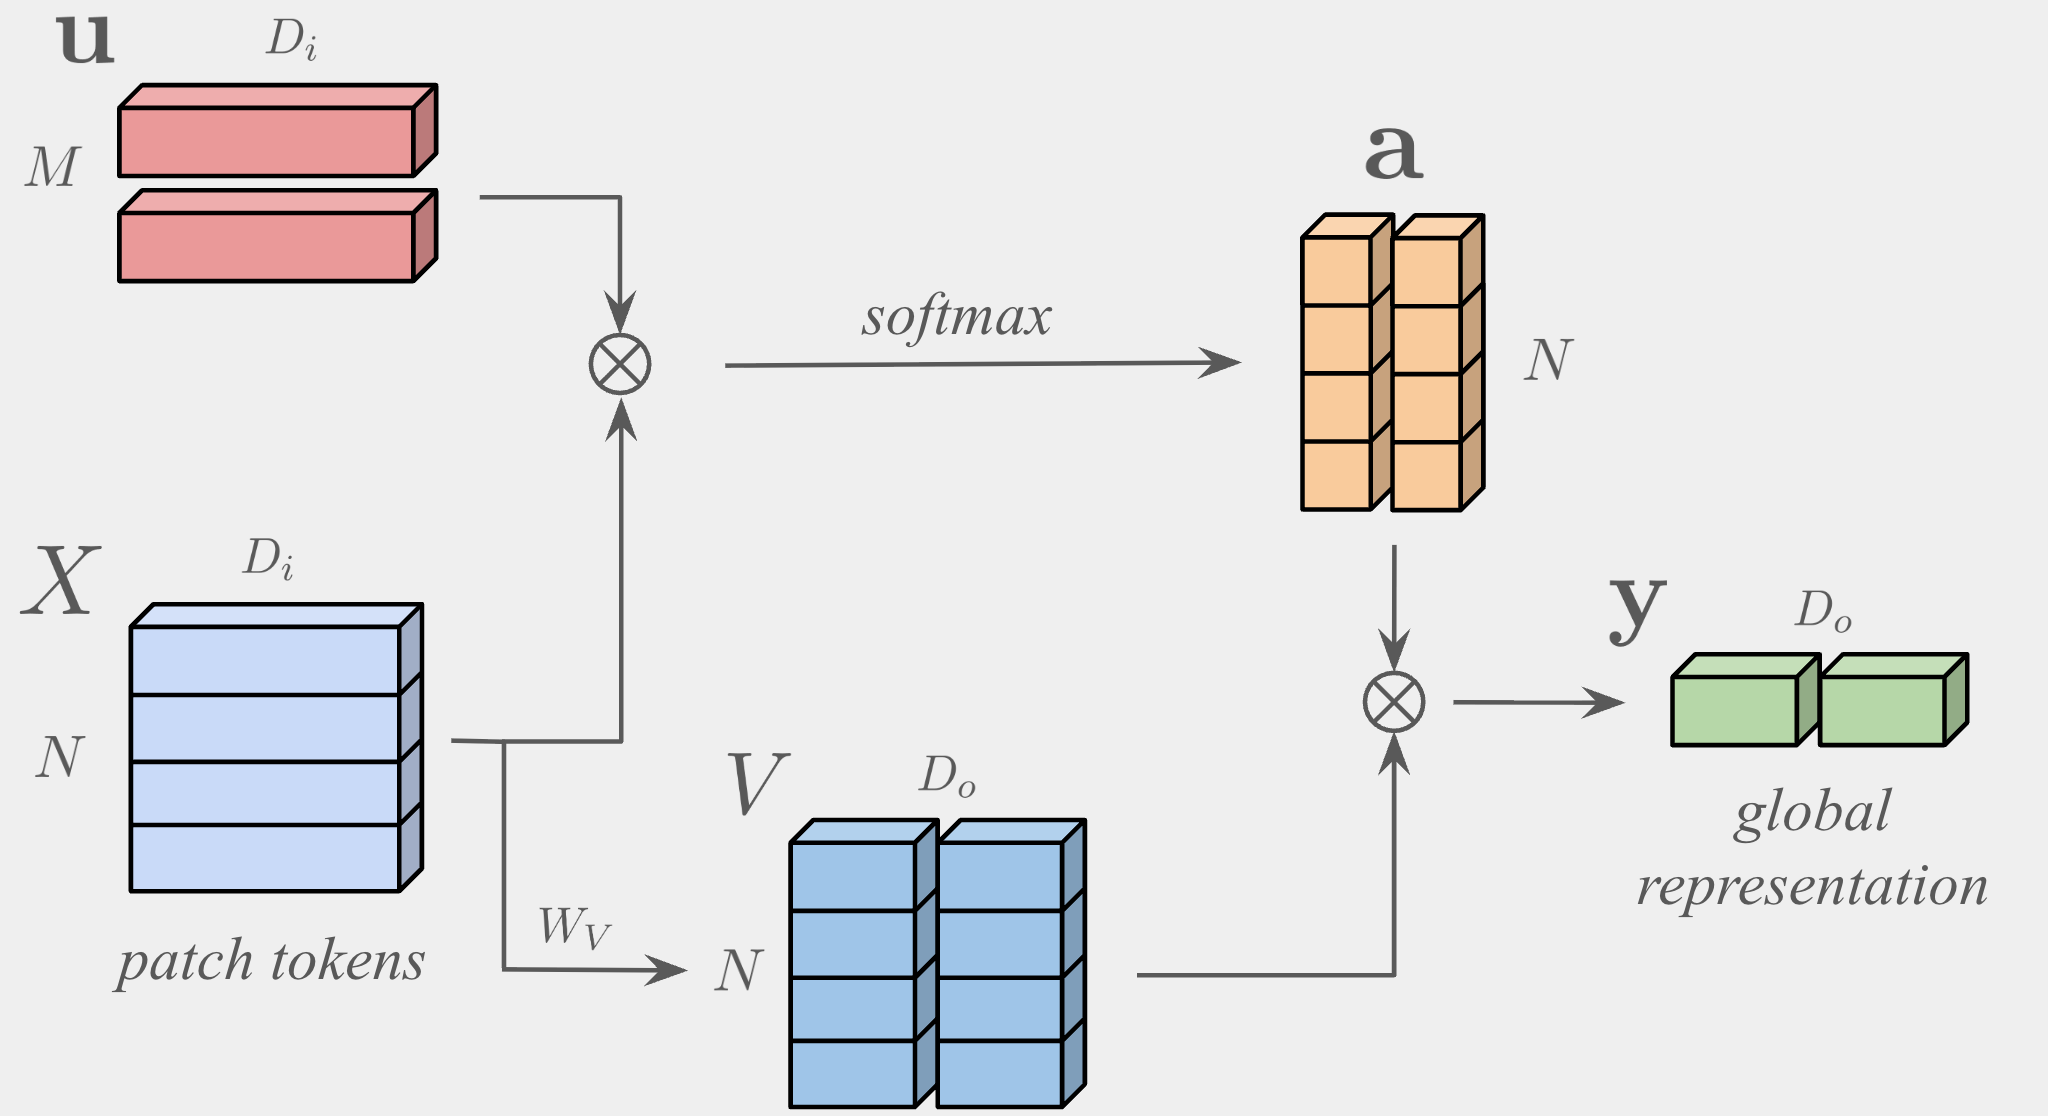
[ICLR 2026] - Official implementation of "Attention, Please! Revisiting Attentive Probing Through the Lens of Efficiency"
[CVPR 2026] Wavelet-based Frame Selection by Detecting Semantic Boundary for Long Video Understanding
A curated list of 640+ papers and tools on multimodal coding agents: visual feedback → models as tools → bridging digital and physical worlds. Towards physical AGI.
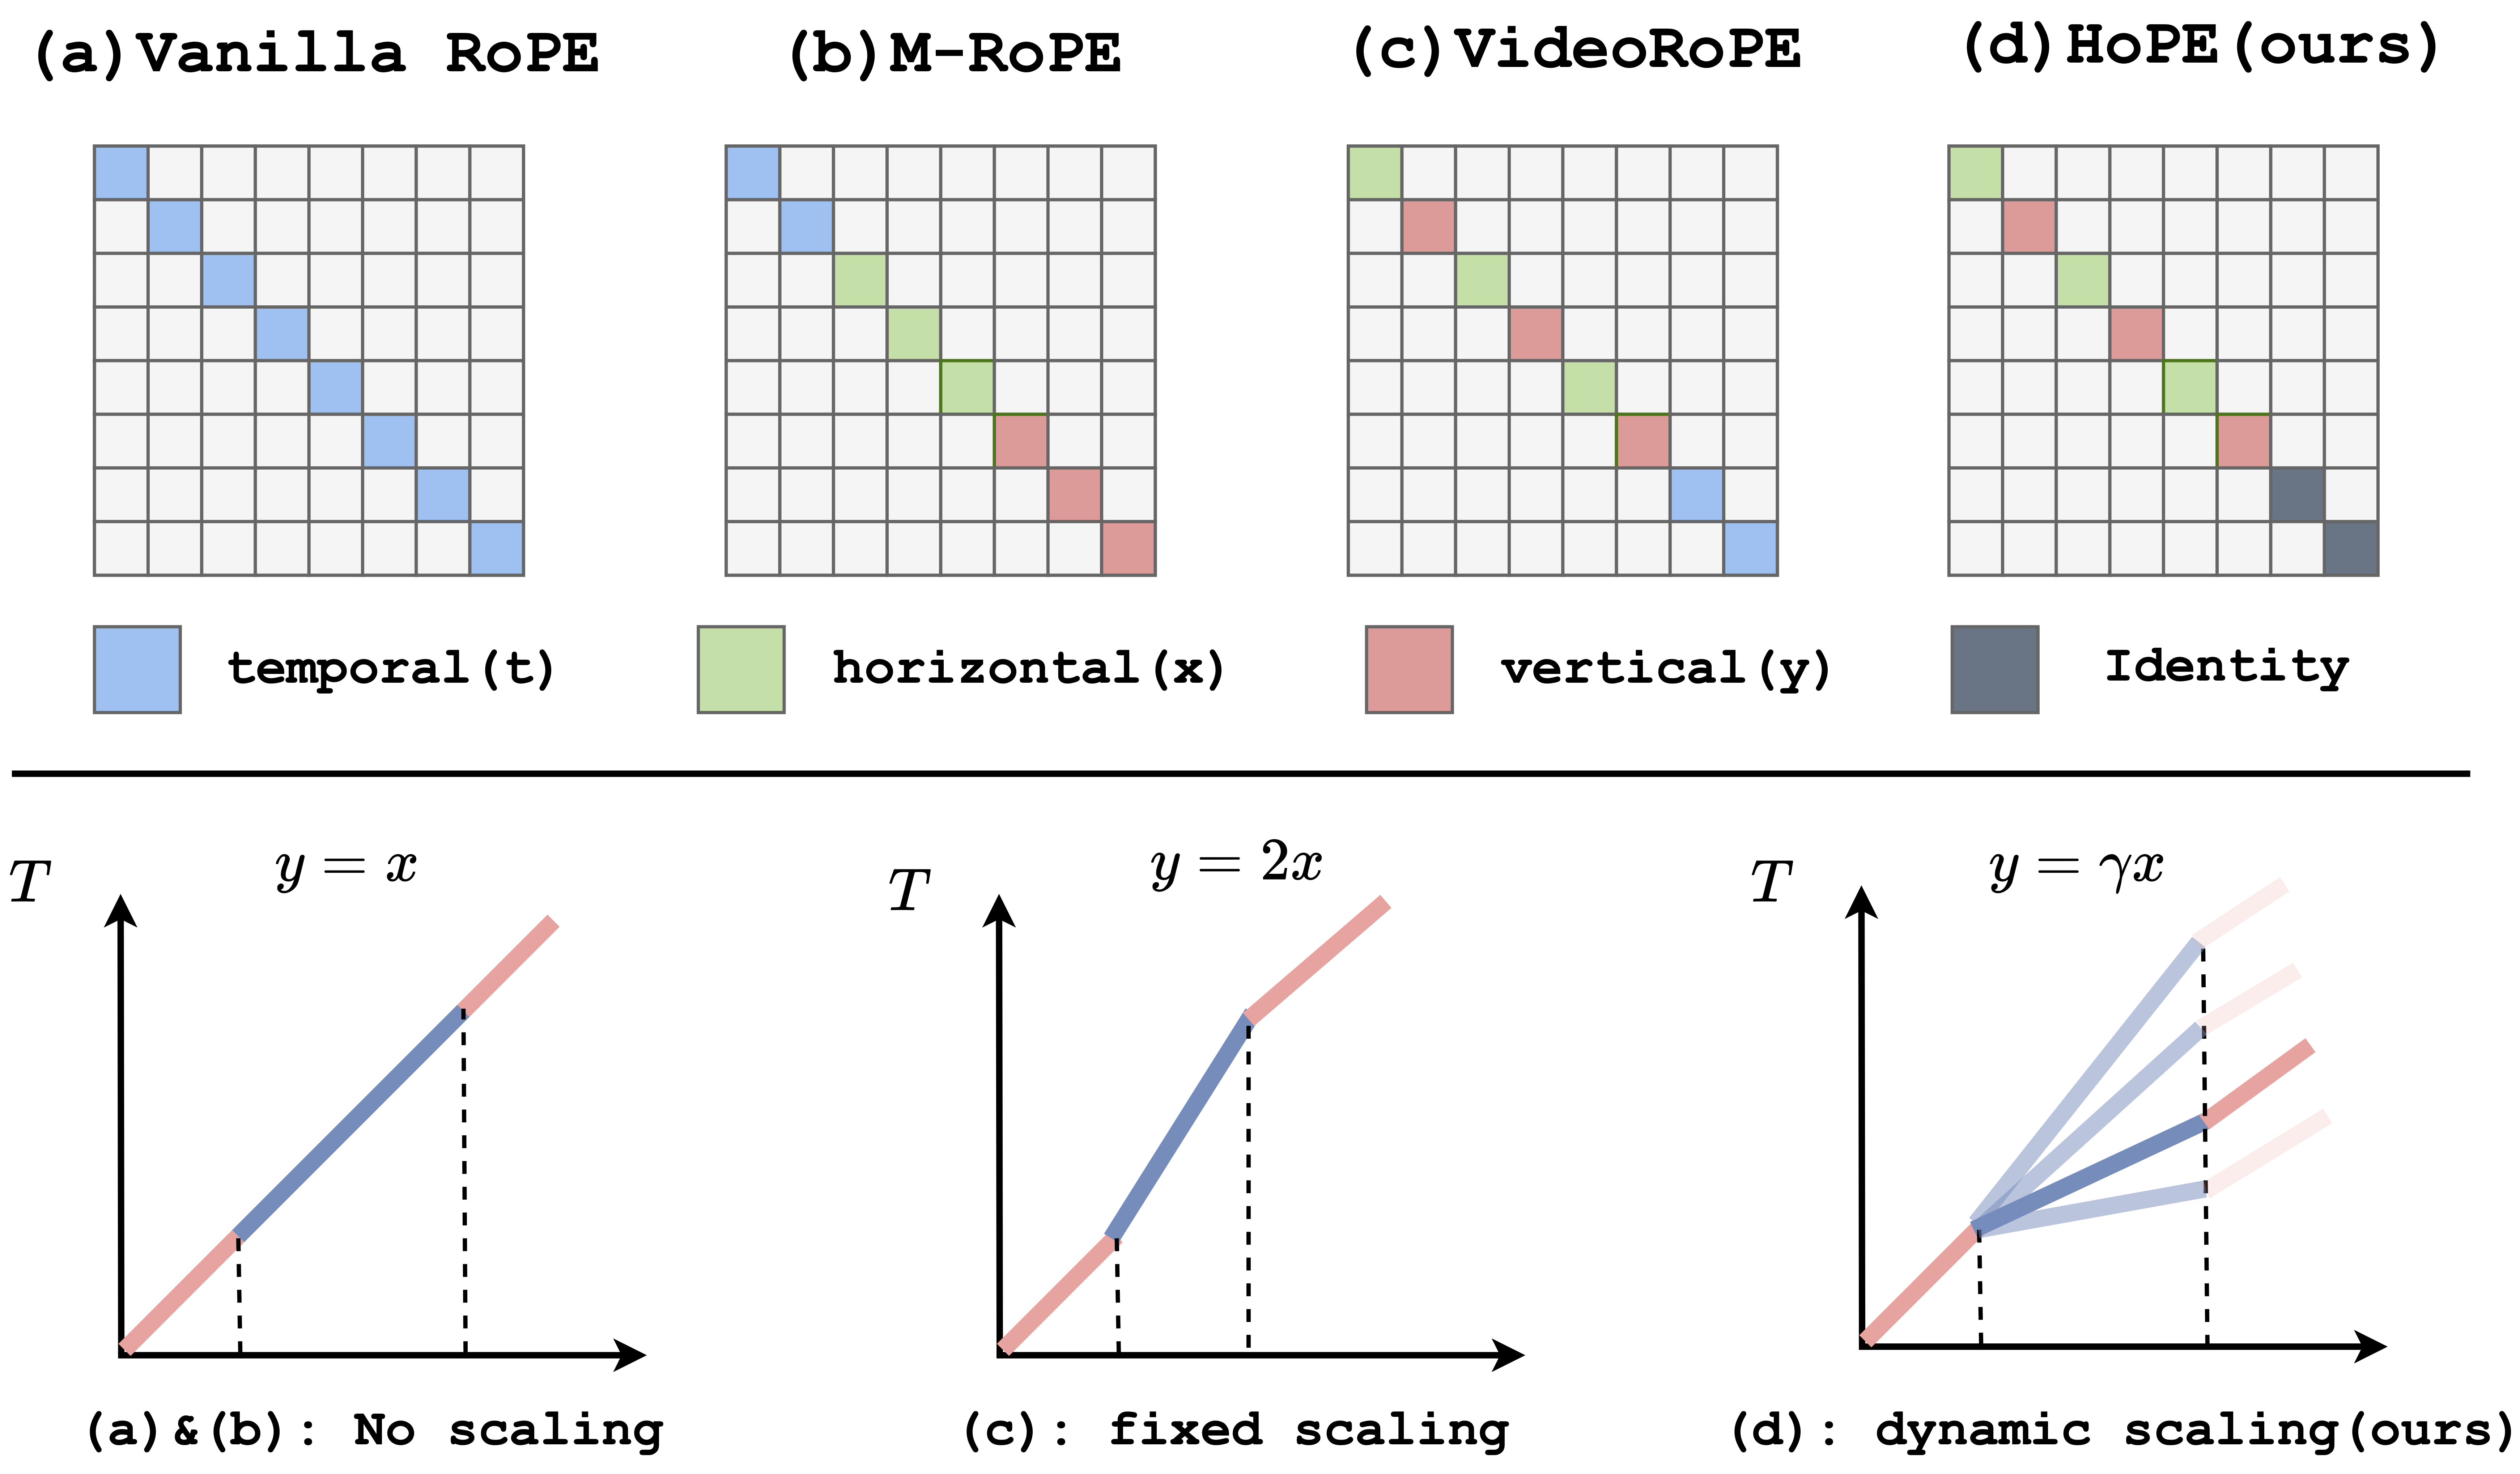
[NeurIPS 2025] HoPE: Hybrid of Position Embedding for Long Context Vision-Language Models
[NeurIPS 2025 Spotlight] Talk2Event: Grounded Understanding of Dynamic Scenes from Event Cameras
Multimodal prompt generator nodes for ComfyUI, designed to generate prompts for QwenImageEdit and Wan2.2. Supports local LLM / local GGUF models (Qwen2.5-VL, Qwen3-VL, Qwen3.5, Qwen3.6 and Qwen3.8) and Qwen API for image and video prompt generation and enhancement.
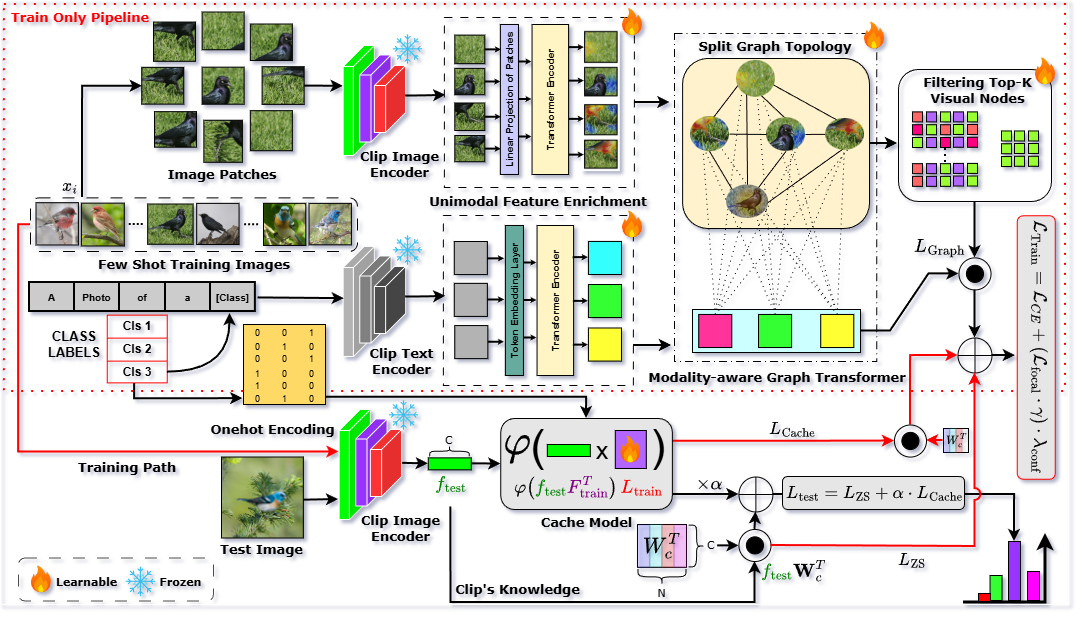
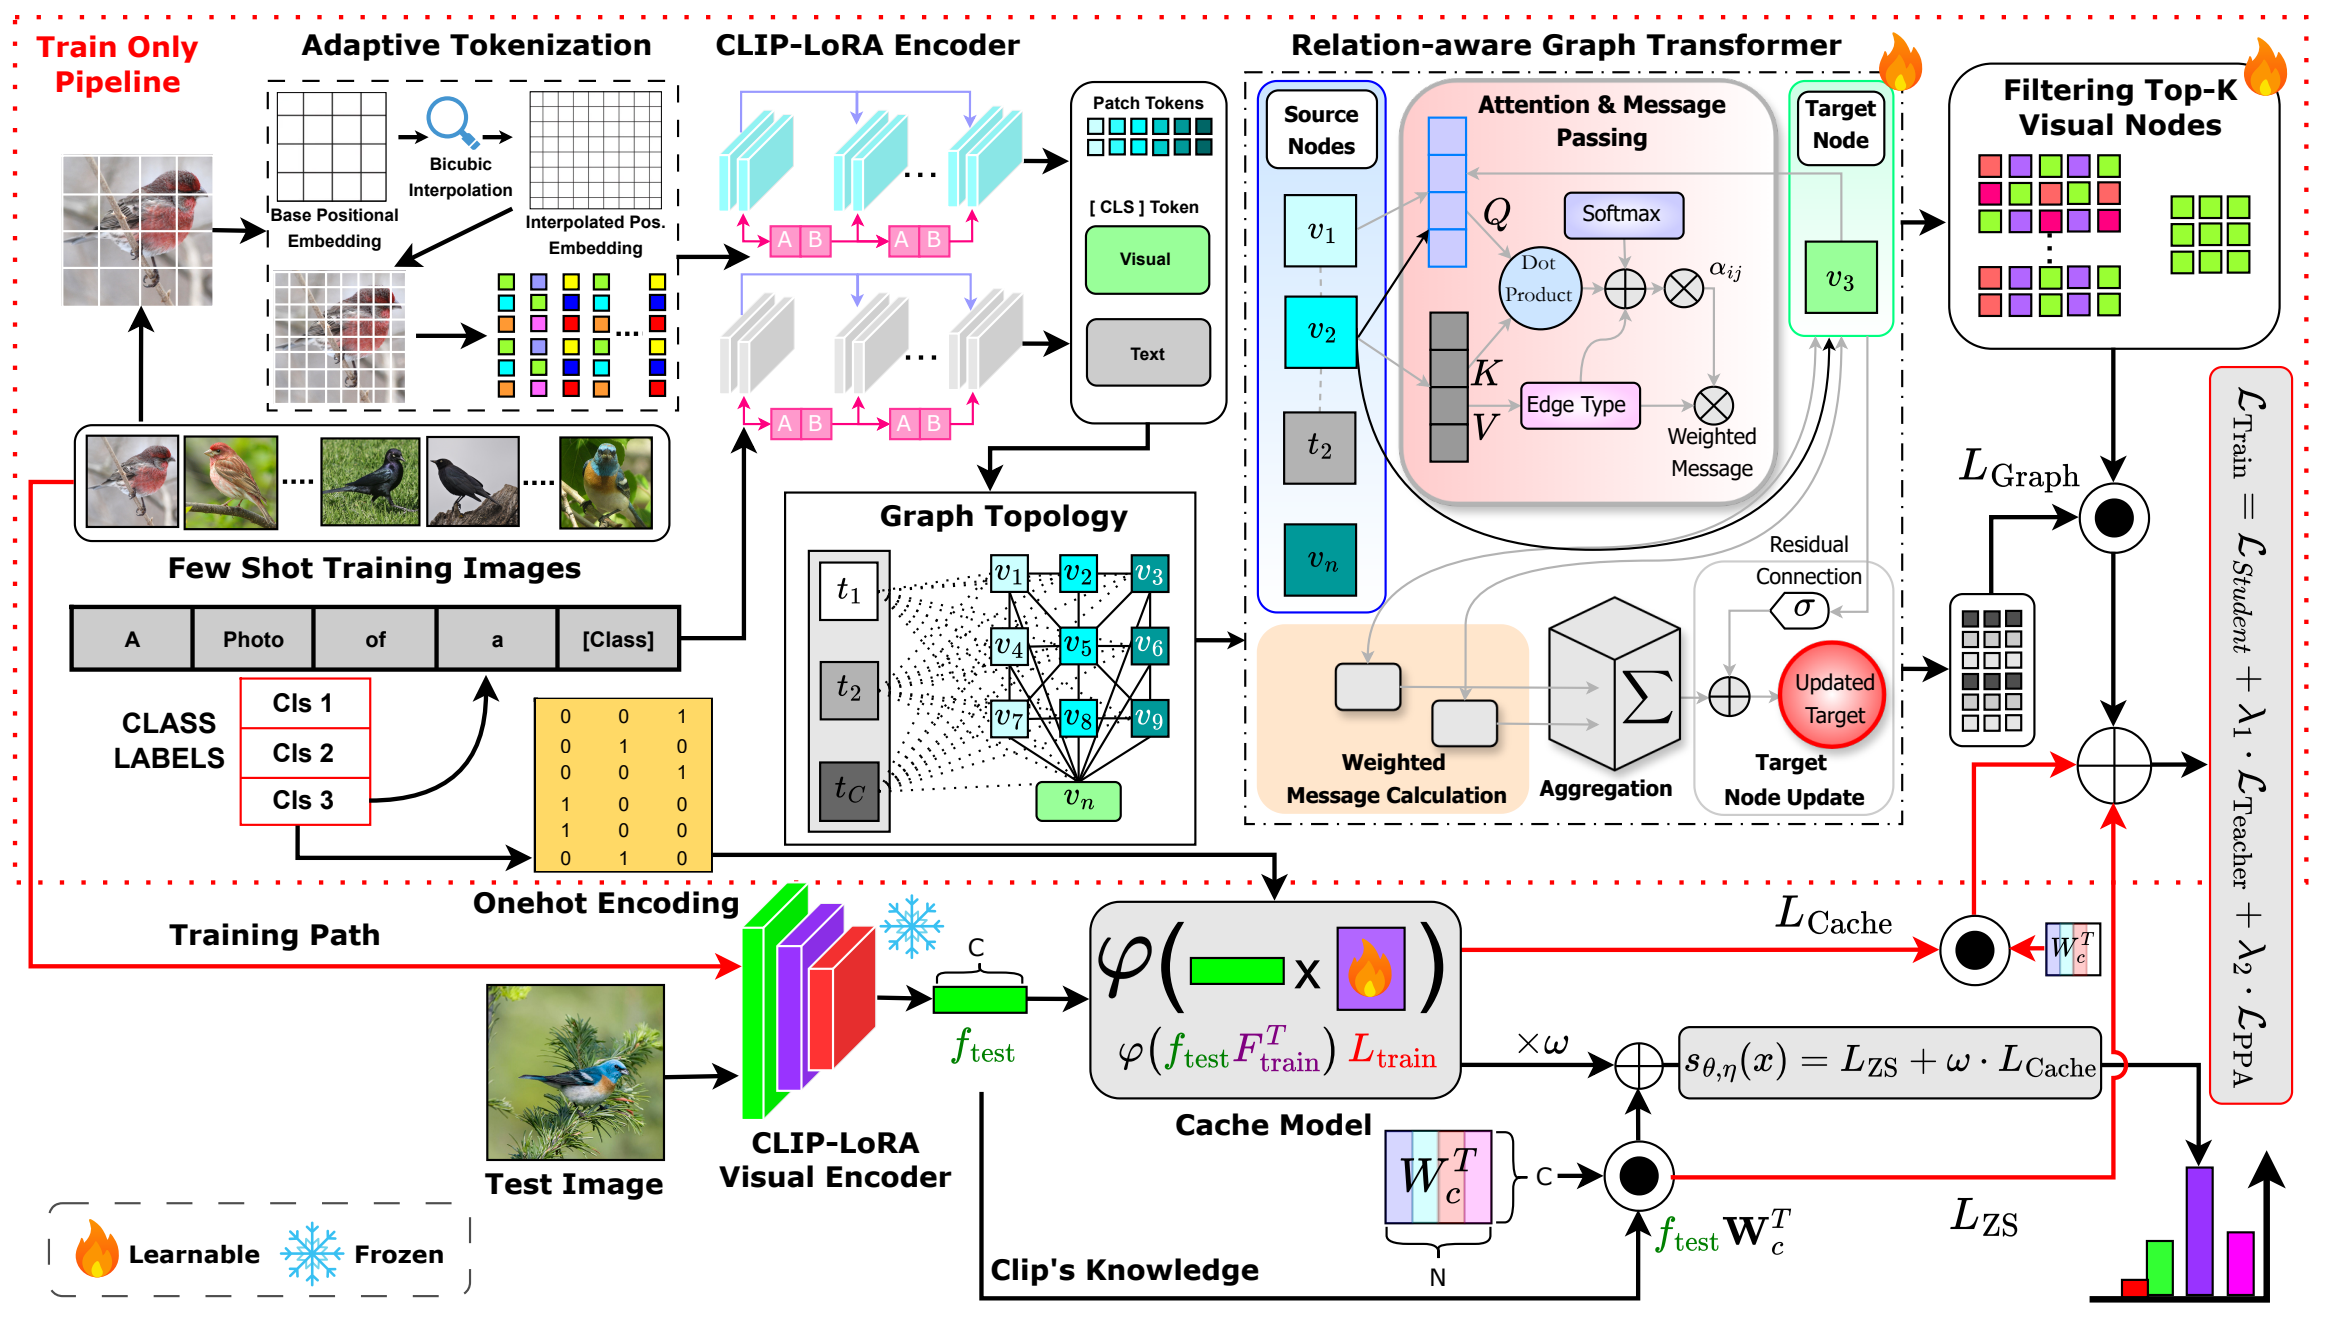
[CVPR 2026] Official PyTorch implementation of "Training-Only Heterogeneous Image-Patch-Text Graph Supervision for Advancing Few-Shot Learning Adapters" (TOGA).
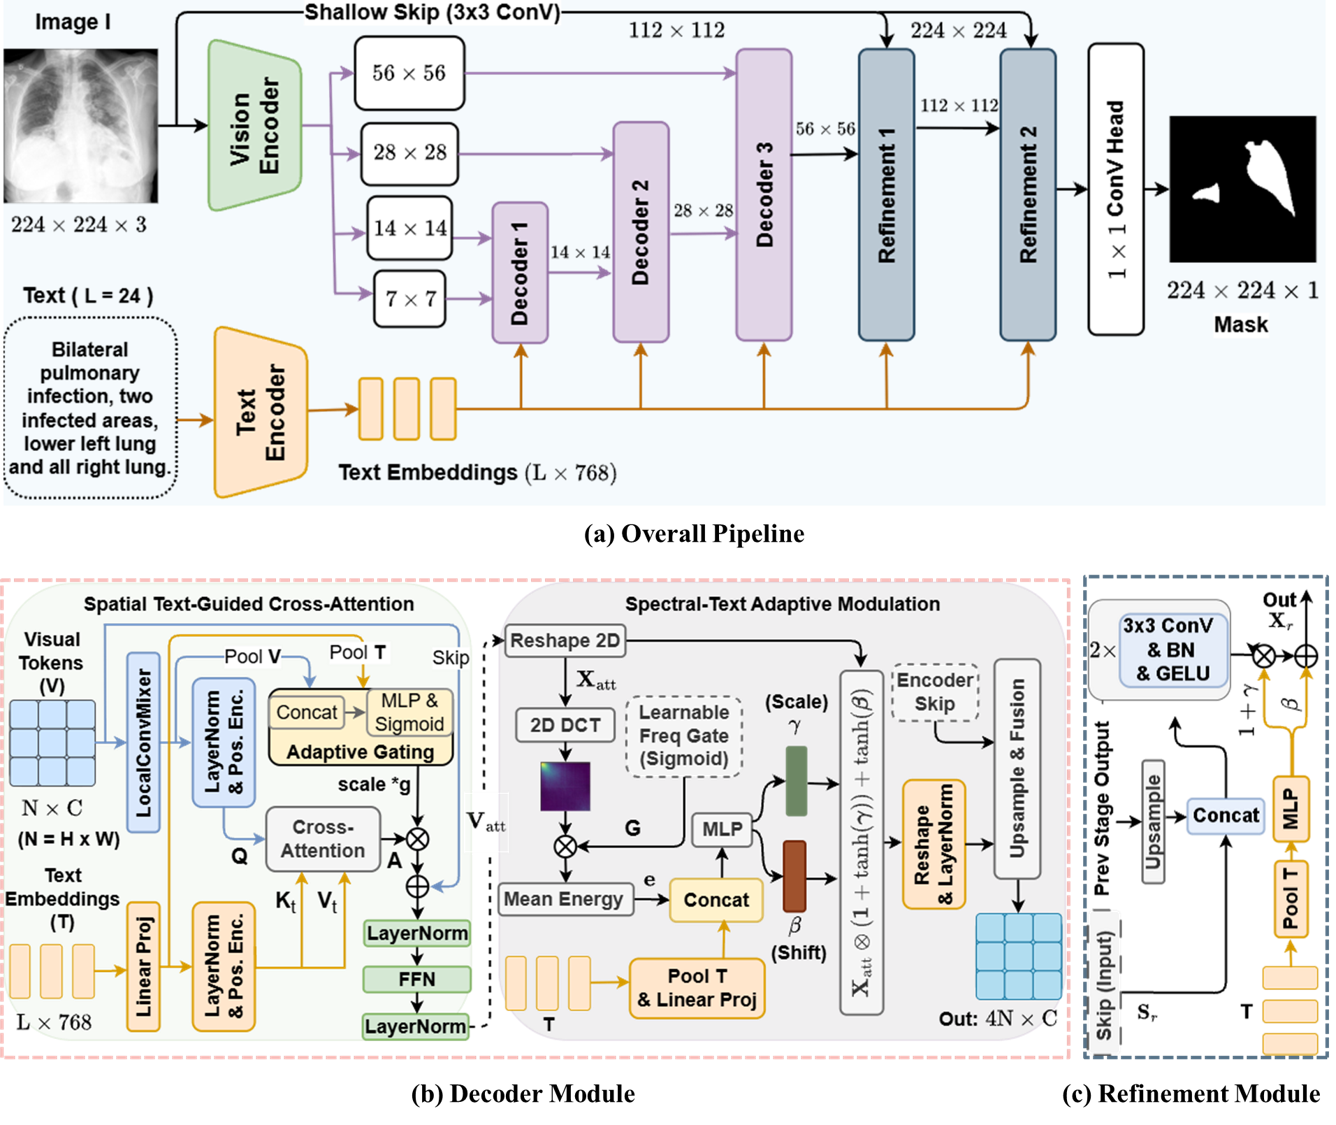
MICCAI 2026 (Main): Dual-Domain Cross-Modal Decoding for Clinical Text-Guided Medical Image Segmentation
This paper introduces BloomBench, a new bilingual (English-Arabic), cognitively-informed benchmark based on Bloom's Taxonomy to systematically evaluate the reasoning abilities of Vision-Language Models across different hierarchical cognitive levels.
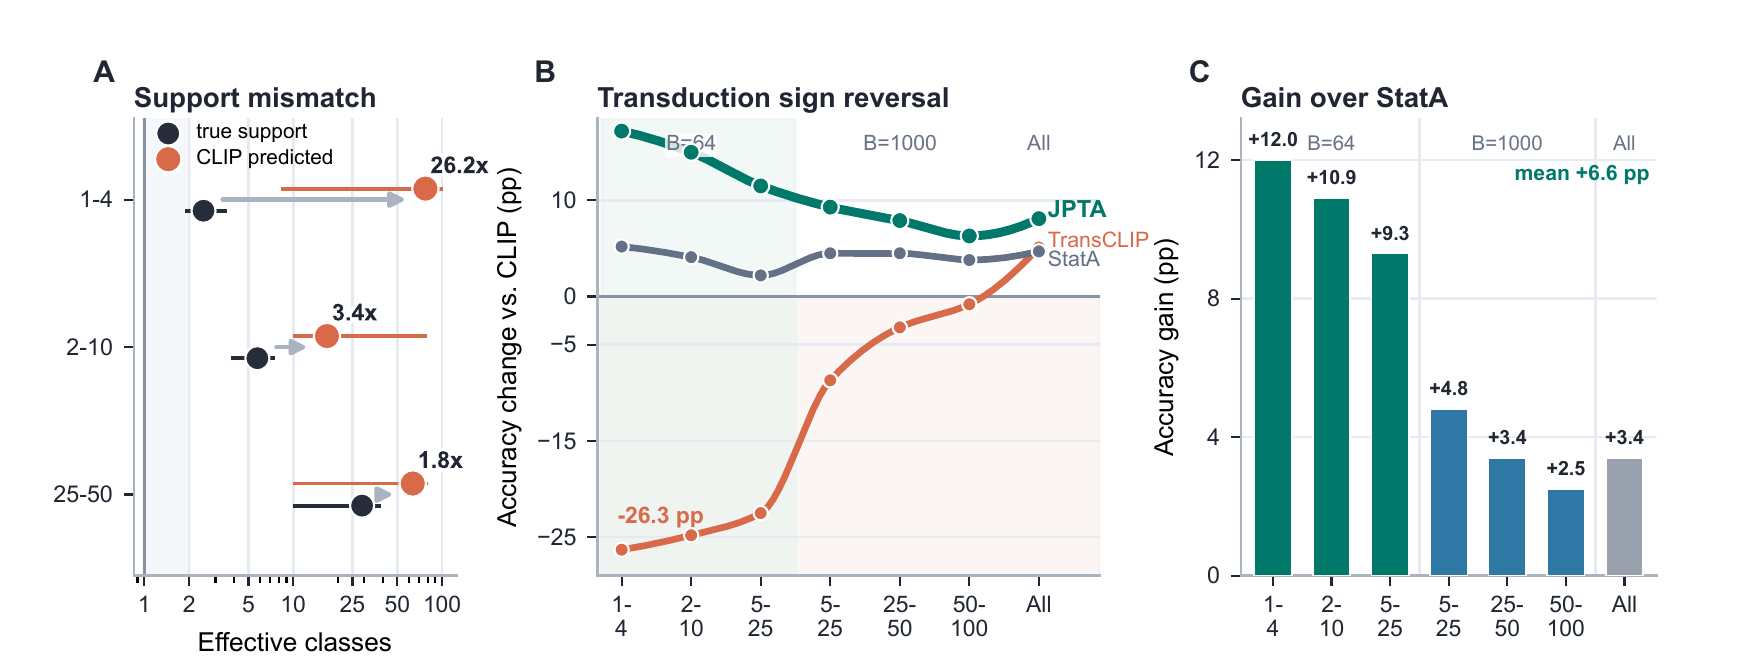
[NeurIPS 2026] Official PyTorch implementation of "Batch-Conditioned Semantic Anchors for Robust Transductive Adaptation of Vision-Language Models" (JPTA).
[NeurIPS 2026] Official PyTorch implementation of SD-LoRA: Training-Time Structural Distillation into LoRA for Few-Shot Vision-Language Adaptation.
LoRA-based fine-tuning pipeline for Pixtral‑12B on multimodal instruction tasks using Hugging Face and vision-language templates.
This 2.7GB Local OCR Model Changed My Workflow! (LightOnOCR-3 Review) - High-accuracy offline document understanding pipeline with Ollama and GGUF.
Demo for state-of-the-art Vision-Language Models (VLMs) for both image and video understanding tasks. This application offers a unified interface to interact with various specialized models for OCR, document analysis, visual reasoning, and multimodal understanding.
EMNLP 2026 • Rarity beyond popularity for multilingual multimodal entity linking, with training-free reasoning and Wikipedia retrieval.
Code and artifacts for "The Cost of Language: Centroid Erasure Exposes and Exploits Modal Competition in Multimodal Language Models" (COLM 2026). Centroid replacement, a training-free probe for text-vs-visual dependence in multimodal LMs, and text centroid contrastive decoding (TCCD) are included.
An agentic real estate consultant built for a hackathon that leverages image-based analysis to assess property features, all through a natural language interface. Built using OpenAI’s Agents SDK, this system integrates multimodal understanding (images + text) to deliver contextual property insights, value suggestions, and neighborhood analysis.
This reporsitory contains all the Homeworks, and Projects from the Deep Learning Course by Prof. Chinmay Hegde, in Spring 2025, at NYU.
🐍 Miru — Multimodal reasoning tracer 👁️. Answers questions over images/docs 🖼️📄 while visualizing step-by-step attention and reasoning 🔍. Built for explainable vision-language AI 🤖✨
Official Repository & Benchmark Portal for MM-RegCheck: Training-Free Causal-Aware Multimodal Reasoning for Regulatory Evasion Detection (ACM Multimedia 2026)
4.76x Faster Attribution Graph Generation for LLMs and VLMs - Achieves 79% speedup by eliminating Python loops and vectorizing GPU operations. Works with GPT, LLaMA, Qwen, LLaVA, CLIP