transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
- 169k
- Python
- Apache-2.0
- 5 h ago
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
SGLang is a high-performance serving framework for large language models and multimodal models.
https://arxiv.org/abs/2606.28344. The end of web parsing. The beginning of scalable pixel-native search. link: https://pixelrag.ai/
A collection of tutorials on state-of-the-art computer vision models and techniques. Explore everything from foundational architectures like ResNet to cutting-edge models like RF-DETR, YOLO11, SAM 3, and Qwen3-VL.
Easily fine-tune (SFT/RL), evaluate, and deploy Qwen, Gemma, or any open agentic LLM/VLM!
Run frontier LLMs and VLMs locally on Qualcomm devices across NPU, GPU, and CPU with a few lines of code
The official repository for ERNIE 4.5 and ERNIEKit – its industrial-grade development toolkit based on PaddlePaddle.
A Low-Code MCP Framework for Building Complex and Innovative RAG Pipelines
One-for-All Multimodal Evaluation Toolkit Across Text, Image, Video, and Audio Tasks
An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.
[CVPR 2026] PromptEnhancer is a prompt-rewriting tool, refining prompts into clearer, structured versions for better image generation.
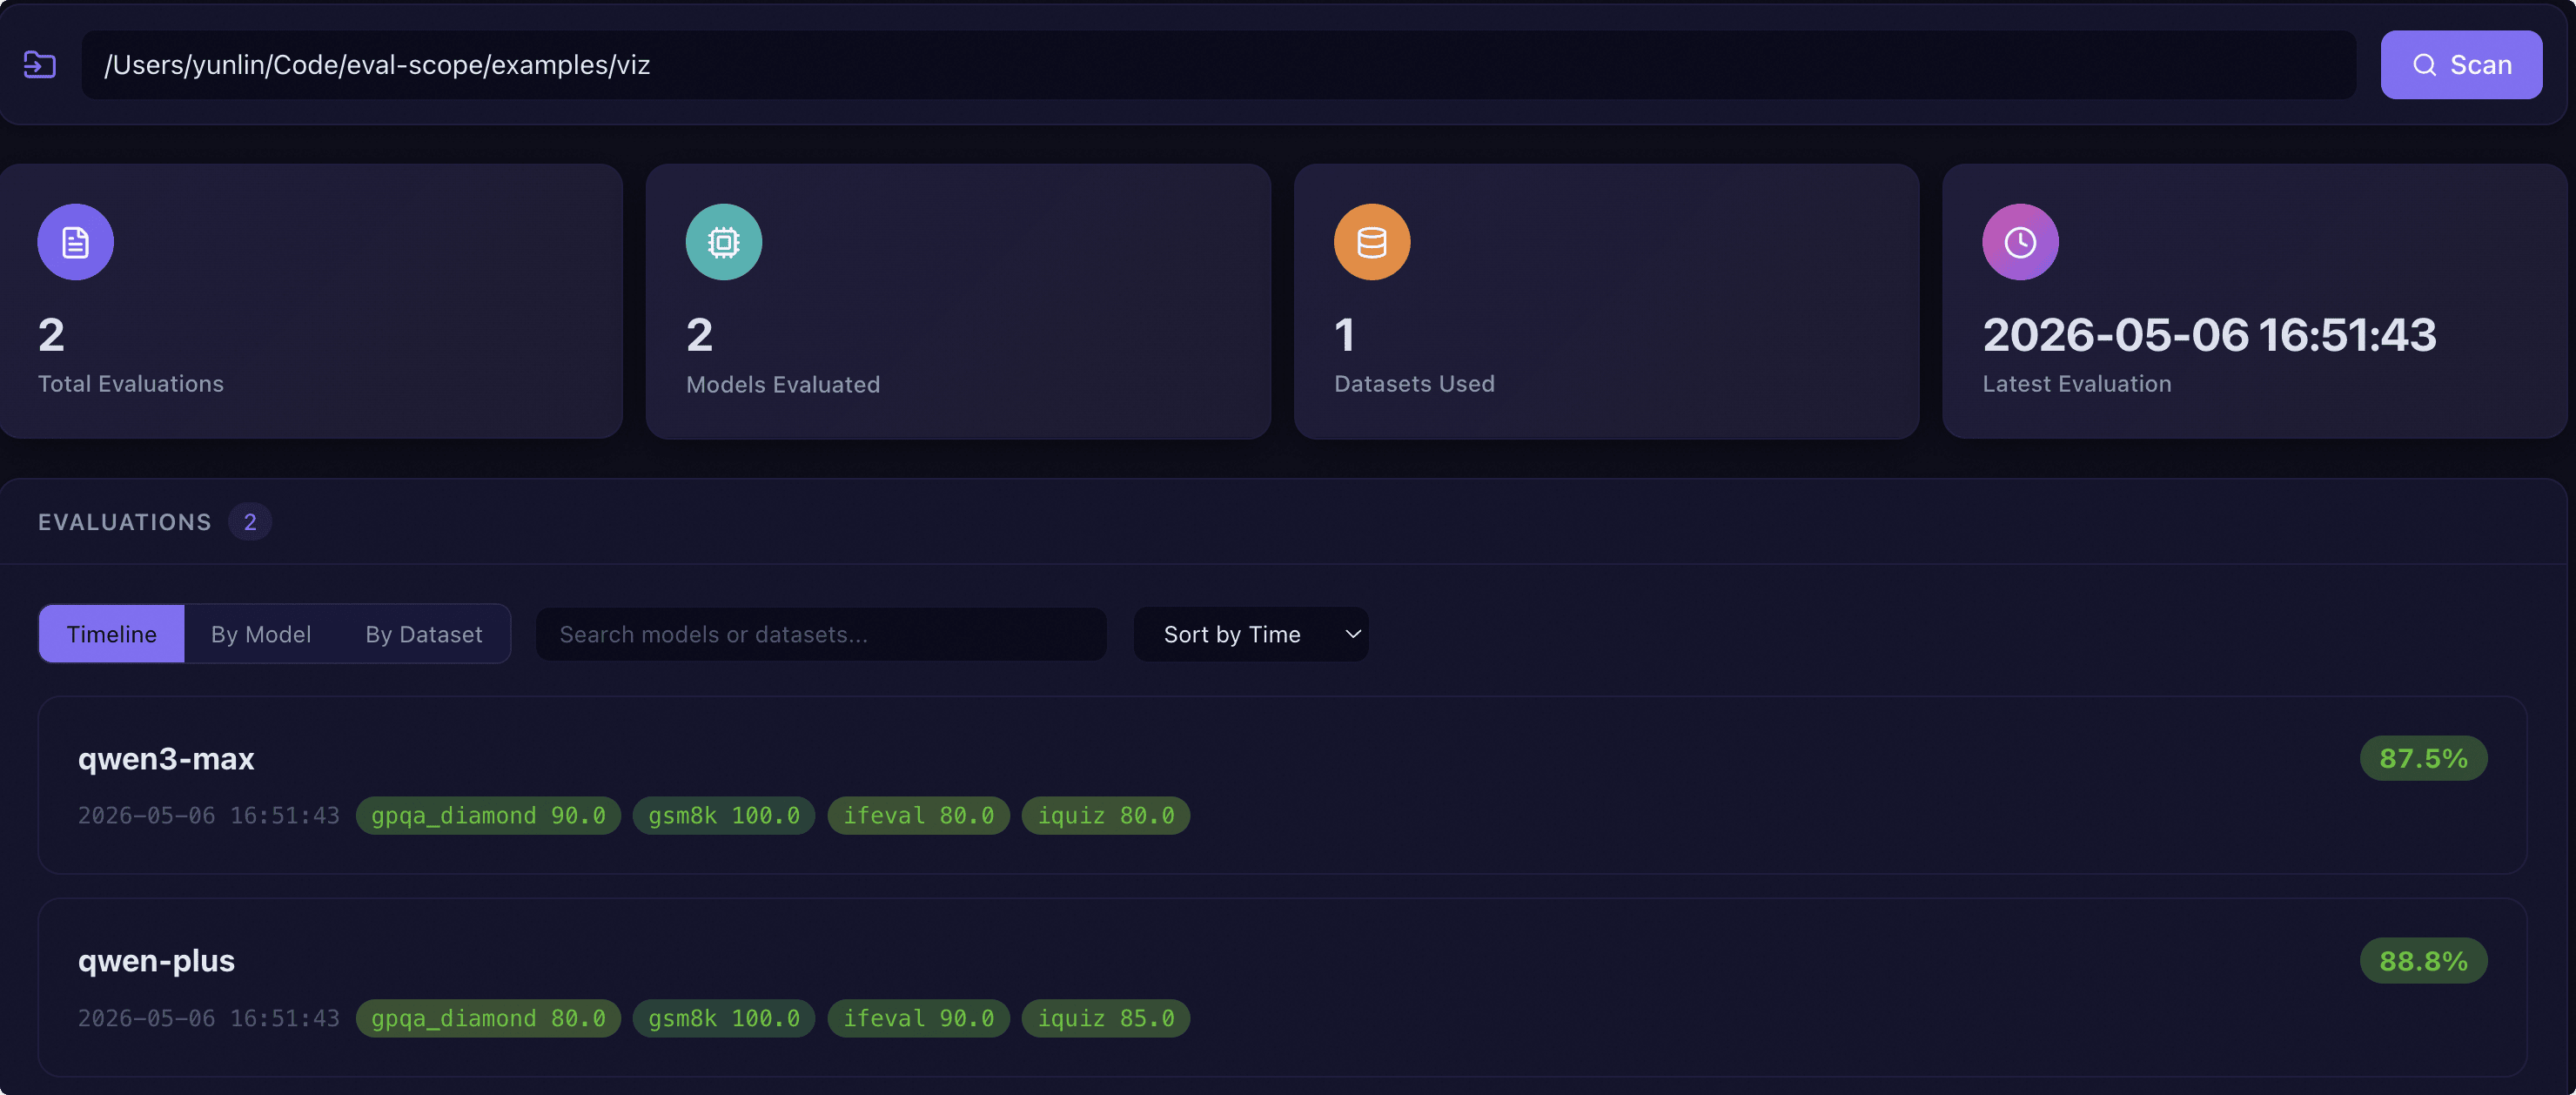
A streamlined and customizable framework for efficient large model (LLM, VLM, AIGC) evaluation and performance benchmarking.
The official repo of MiniMax-Text-01 and MiniMax-VL-01, large-language-model & vision-language-model based on Linear Attention
An AI-powered file management tool that ensures privacy by organizing local texts, images. Using Llama3.2 3B and Llava v1.6 models with the Nexa SDK, it intuitively scans, restructures, and organizes files for quick, seamless access and easy retrieval.
[NeurIPS 2024] OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
Skywork-R1V is an advanced multimodal AI model series developed by Skywork AI, specializing in vision-language reasoning.
[EMNLP-2024] Build multimodal language agents for fast prototype and production
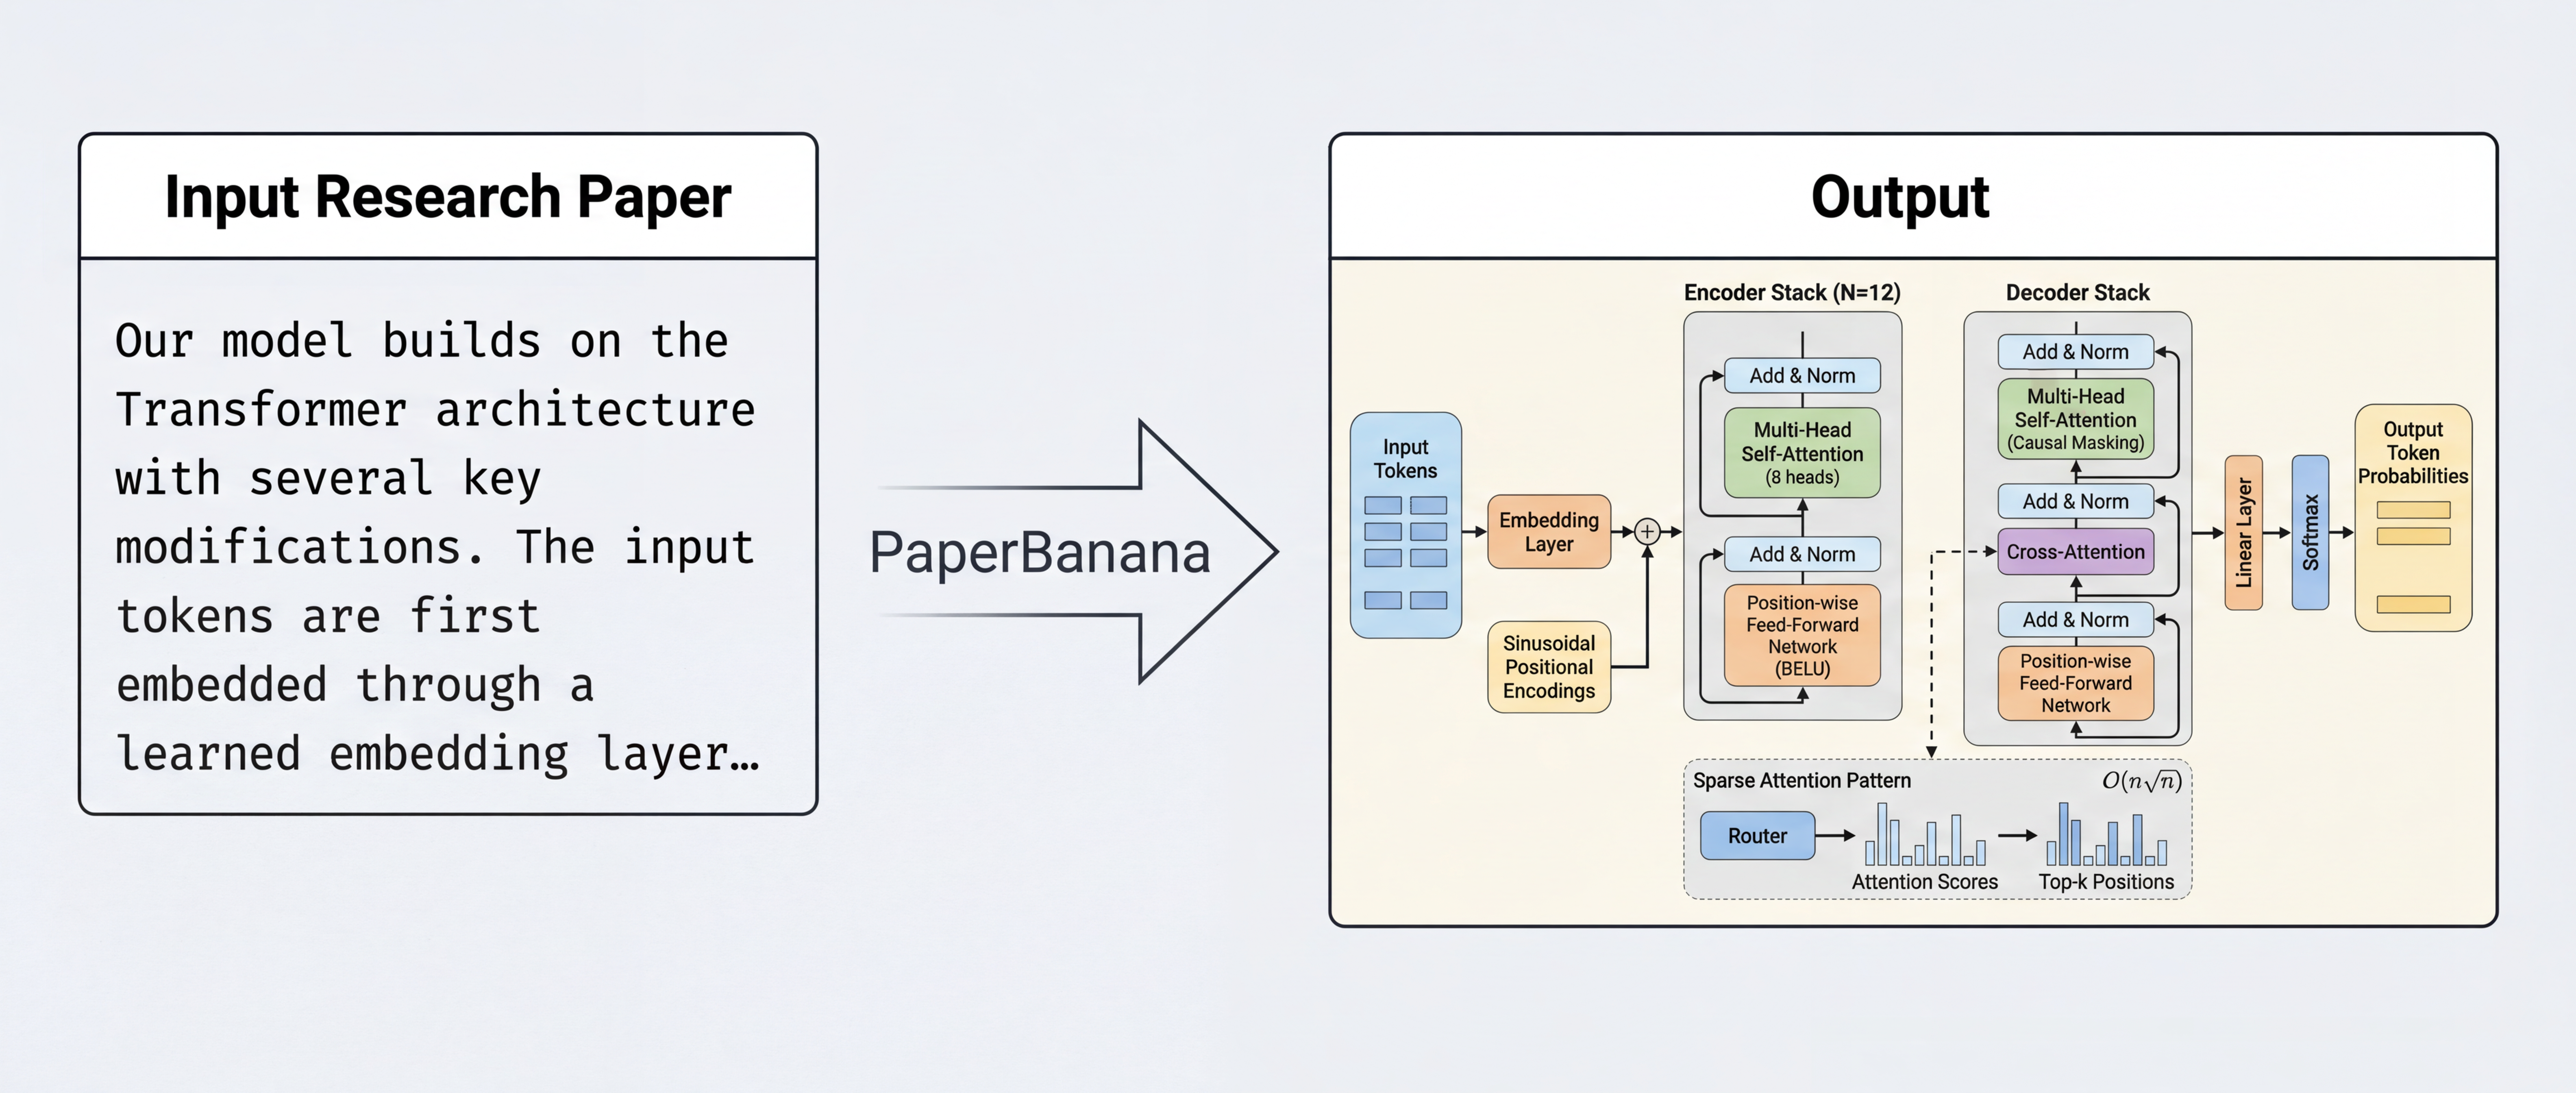
Open source implementation and extension of Google Research’s PaperBanana for automated academic figures, diagrams, and research visuals, expanded to new domains like slide generation.
GLM-4.6V/4.5V/4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning
LLM Agent Framework in ComfyUI includes MCP sever, Omost,GPT-sovits, ChatTTS,GOT-OCR2.0, and FLUX prompt nodes,access to Feishu,discord,and adapts to all llms with similar openai / aisuite interfaces, such as o1,ollama, gemini, grok, qwen, GLM, deepseek, kimi,doubao. Adapted to local llms, vlm, gguf such as llama-3.3 Janus-Pro, Linkage graphRAG
A reading list for large models safety, security, and privacy (including Awesome LLM Security, Safety, etc.).
Production-grade C++ edge AI engine for video analytics and on-device VLM across Sophon, Rockchip RKNN, and x86, with visual orchestration, real-time OSD, events, and reproducible benchmarks.
NVIDIA AI Blueprint for video search and summarization (VSS) is a GPU-accelerated reference architecture for building video analytics agents with real-time verified alerts, visual Q&A, and automated reporting. The VSS Blueprint uses vision language models (VLMs) such as NVIDIA Cosmos, LLMs such as NVIDIA Nemotron, RAG, and NVIDIA NIMs.
An open-source implementaion for fine-tuning Qwen-VL series by Alibaba Cloud.
OpenGUI is an Android GUI agent framework for phone-use AI that can see, plan, and operate real mobile apps through the GUI.
🚀🚀🚀 A collection of some awesome public YOLO object detection series projects and the related object detection datasets.
Model compression toolkit engineered for enhanced usability, comprehensiveness, and efficiency.
High-performance, privacy-first on-device AI inference library for React Native, powered by PyTorch's ExecuTorch runtime
Aircraft design optimization made fast through computational graph transformations (e.g., automatic differentiation). Composable analysis tools for aerodynamics, propulsion, structures, trajectory design, and much more.
Curated visual catalog of 200+ vision-language model (VLM/MLLM) architectures: papers, diagrams, training recipes, datasets, and a release timeline for multimodal AI agents.
全网最全的、持续更新的、最火爆的 100+ 人格 蒸馏skills 合集| 多agent系统 |名人/导演/天涯大神/古籍/二次元/职场/情感全品类
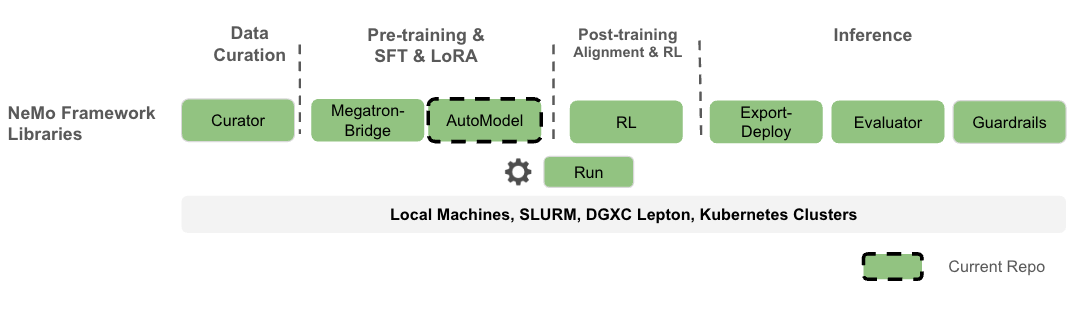
🚀 Pytorch Distributed native training library for LLMs/VLMs with OOTB Hugging Face support
Image text to text model, used with transformers.
Image to text model, used with transformers.
Weight-Native OS with a kill switch inside the model
Runs in the browser on Hugging Face
DNA lineage test of Korean LLM & VLM foundation models
Runs in the browser on Hugging Face
Slovenian-Language OCR Benchmark Leaderboard
Runs in the browser on Hugging Face
Run & Train Small LMs for Free w/ GGUF, PEFT & more!
Runs in the browser on Hugging Face