mtp


DeepSeek-V4-Pro-Qwen3.5-9B-UNCENSORED-heretic
Text generation model, used with transformers.
- 9.7k
- 41k
- apache-2.0
- 8 d ago

MTPLX
The fastest way to run Qwen 3.8 Flash Next, Qwen 3.8 27B and Ternary Bonsai 2 27B on a Mac: 125 tok/s in OpenCode on an M5 Max, and a 27B model on 16 GB Macs. Native MTP speculative decoding on Apple Silicon, exact at any temperature. OpenAI and Anthropic compatible local server.
- 2.7k
- Python
- Apache-2.0
- 13 d ago

Qwen3.8-27B-Uncensored-HauhauCS-Aggressive-MTP-GGUF
Image text to text model.
- 2.7k
- 1.6M
- apache-2.0
- 3 mo ago

Qwen3.8-27B-Uncensored-FP8
Image text to text model, used with transformers.
- 1.9k
- 53k
- apache-2.0
- 3 mo ago
Qwen3.8-27B-Uncensored-GGUF
Image text to text model, used with gguf.
Gated access
- 1.9k
- 116k
- apache-2.0
- 3 wk ago
testfx
This repository holds the source code of Microsoft.Testing.Platform (MTP), a lightweight alternative to VSTest, as well as MSTest adapter and framework.
- 1.1k
- C#
- MIT
- 3 h ago

skyward
An Android recovery written in Rust from scratch: decryption, installs and OTA updates, backup, WLAN, MTP, adb and fastbootd. Runs the phone's own drivers and services from its stock firmware.
- 563
- Rust
- GPL-3.0
- 6 d ago

NVIDIA-Nemotron-3-Super-120B-A12B-BF16
Text generation model, used with transformers.
- 440
- 853k
- other
- 9 mo ago
llamAmpere
llama.cpp fork for significantly improved performance on Ampere generation Nvidia cards (especially RTX 3090 / 3090 Ti): example: 110+ tok/s over a 100K-token generation at temperature 1 for qwen3.8, supporting full 262K ctx. Supports low memory (12gb) configs for 200k+ ctx. 120+ TPS, 3300+ prefill for QFN 3.8.
- 403
- C++
- MIT
- 8 h ago

NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16
Text generation model, used with transformers.
- 388
- 1M
- other
- 6 mo ago
RustingStrata
Pure-Rust LLM inference engine for GGUF (Qwen, DeepSeek, GLM, Hy4, Flint). Runs models bigger than your VRAM on CUDA and Vulkan, with MTP drafts and an OpenAI/Anthropic server. 12 GB RTX 3060 vs llama.cpp: Qwen3.6-35B-A3B UD-Q5_K_M 80.5 vs 64.4 tok/s, Flint UD-Q5_K_XL 64.6 vs 48.6. With MTP: 108 tok/s (UD-Q3_K_M), up to 160 (UD-Q2_K_XL).
- 306
- Rust
- 5 h ago

q38rocm
Qwen 3.8 27B ROCmFP4 on AMD Strix Halo (Ryzen AI Max+ 395). Up to 36 tok/s via MTP Speculation, TurboQuant & Mesa RADV Wave64.
- 270
- Python
- 3 mo ago

intel-arc-pro-b70-inference-cookbook
Pinned Intel Arc Pro B60/B70 inference recipes, engine patches and measurement records: Qwen3.8-27B EXL3 on one card (262,144 context, 63 tok/s; MTP3 measured lossy on 27% of a fixed 329-item set), Nemotron Bolt 74B, Flash-Next, dual-card routes, and a machine-checked catalog where each speculative row states whether the drafter changes the answer.
- 202
- Python
- MIT
- 24 h ago

qwen38-flash-next-2x3090
Qwen3.8-Flash-Next on 2× RTX 3090: with 128 GB RAM up to 4,191 tok/s prefill · 111.5 tok/s decode (131K prompt), full 256K window at 2,865 tok/s; with 64 GB RAM 3,410 tok/s prefill · 84 tok/s decode. New: opt-in uncensored mode (runtime abliteration, no new weights).
- 146
- Python
- Apache-2.0
- 5 wk ago

llama.cpp-turboq-mtp
Qwen4-Exp (Qwen3.8-Flash-Next) SWA + MTP + PLE-on-iswa — bounded deep-context decode w/ long-range recall, TBQ4 4.25 bpv KV, DSpark + RotorQuant. Main (master) = Qwen4-Exp build; the Qwen35 SWA hybrid lives on the qwen35 branch. RTX 4090.
- 94
- C++
- MIT
- 8 wk ago

llama.cpp-v100
llama.cpp optimized for NVIDIA Tesla V100 (SM70). Qwen3.8-Flash-Next (MoE) with MTP on 1/2/3/6x V100-16GB at 262K context (6 GPUs: prefill 3402 tok/s at 200K; 2 GPUs on one socket: 2152 tok/s). Qwen3.8-27B with DFlash2 on 1-6 GPUs, up to 512K context. Multimodal, thinking, concurrent serving, built-in web UI.
- 83
- C++
- GPL-3.0
- 8 d ago

NeveAI
NeveAI é uma plataforma de IA local privacy-first, desenvolvida para oferecer uma experiência de alta performance na execução de LLMs, reduzindo a dependência de grandes plataformas, assinaturas caras e APIs externas e servindo como uma alternativa offline, privada e independente.
- 66
- Python
- 2 d ago


strix-halo-engine-lab
Exact LLM inference engine written from scratch for AMD Strix Halo (gfx1151, ROCm/HIP). Qwen3.8-Flash-Next on one node or two replicas; DeepSeek V4.1 Flash across two nodes over USB4 with an optional RTX PRO. Speculative decoding bit-identical to greedy, up to 255 tok/s on coding chat. MiniMax and GLM next.
- 37
- C++
- Apache-2.0
- 2 d ago

llmash
Ollama-compatible LLM server. Beats vllm by 40% on single stream decode, and by 20% on multi stream decode, and beats ollama by much 2-4x. Made possible with custom CUDA kernels, MTP, speculation and its own 3-bit builds. Uncensors models in one command. Windows and Linux, NVIDIA. Optimized to not eat up ram.
- 37
- C++
- Apache-2.0
- 8 d ago

openExpress
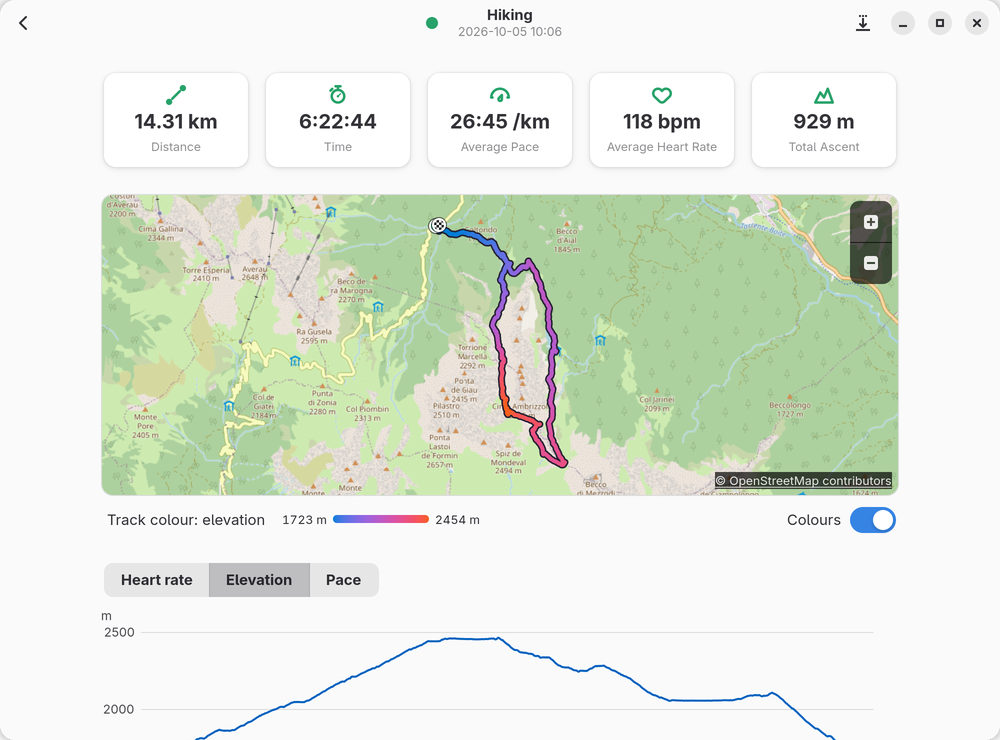
Unofficial Linux app for Garmin watches: Garmin Connect sync, software updates, maps, Connect IQ apps and music over USB
- 33
- Python
- GPL-3.0
- 19 h ago

Octavo
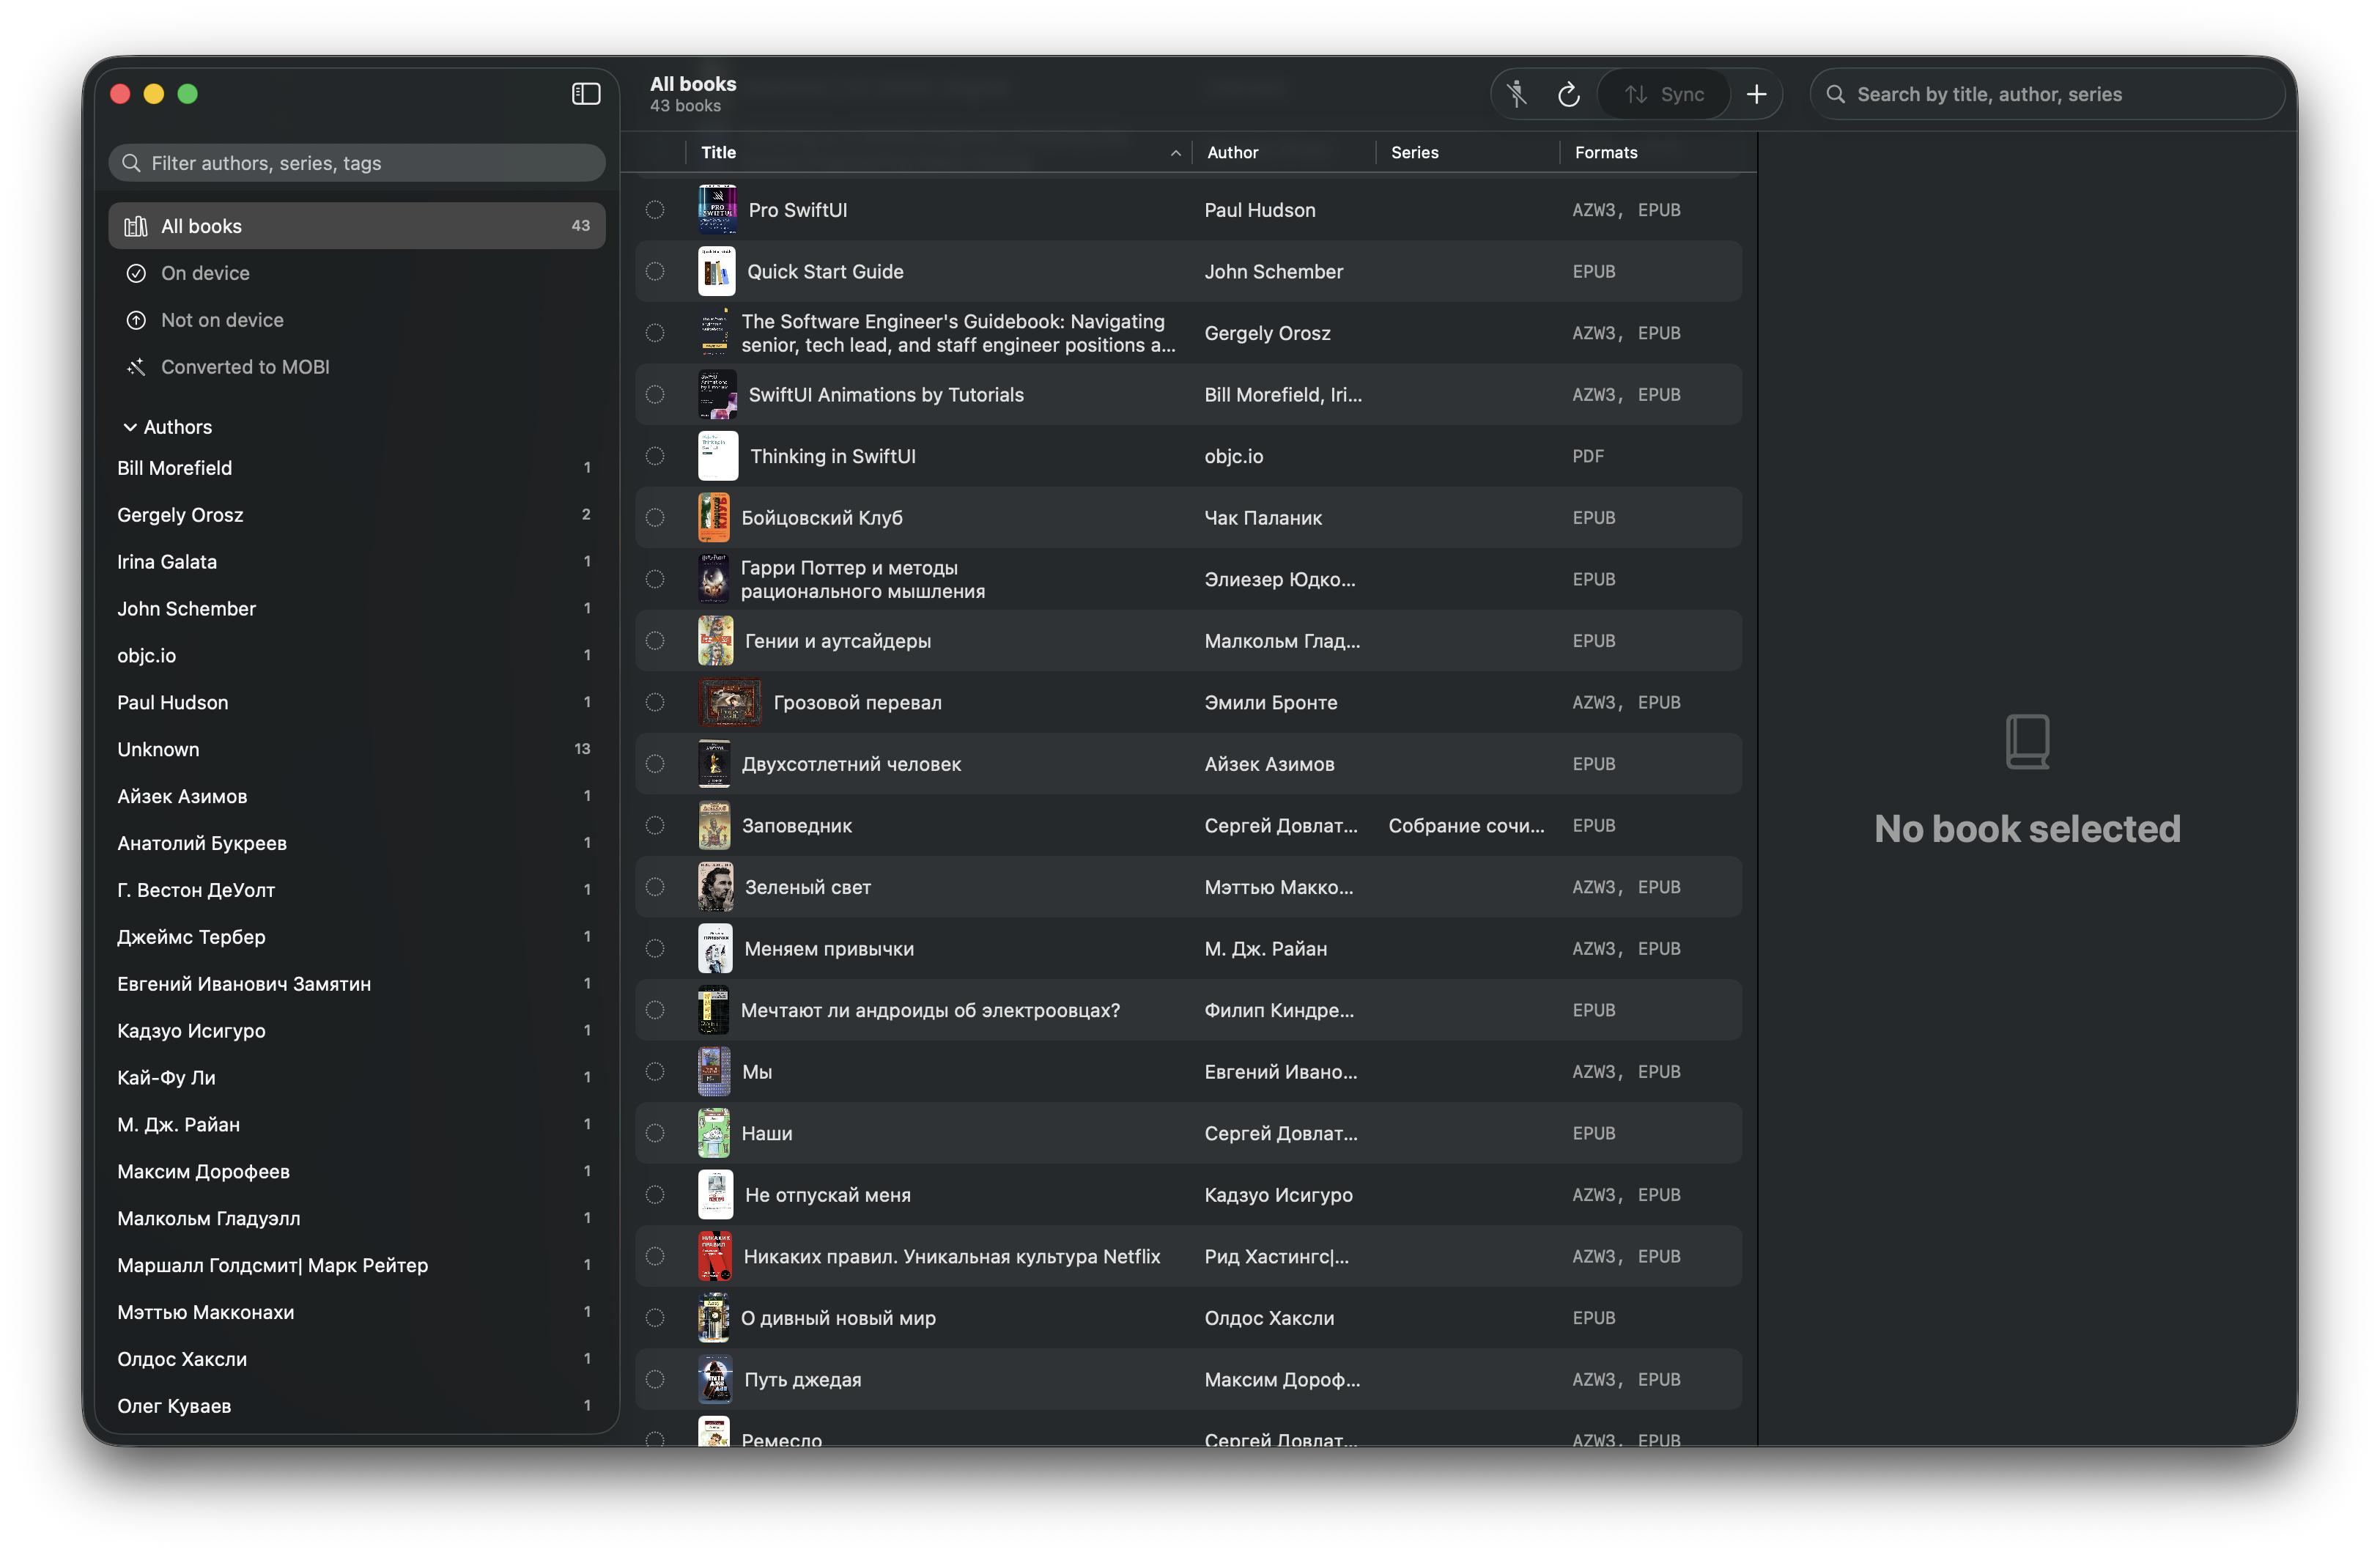
Native macOS replacement for calibre: syncs an ebook library to a Kindle over MTP and edits metadata. No dependencies, 3 MB.
- 28
- Swift
- MIT
- 3 wk ago

llama-vulkan-strix
Docker Compose for llama.cpp GGUF servers on AMD Strix Halo: Qwen, Gemma, and Laguna packages (abliterated and quantized), stock Vulkan plus ROCmFP4/MTP and ROCmFPX, parallel slots, with prefill/decode and quality metrics measured on this rig.
- 28
- Python
- 3 mo ago

qwen3.8-27b-5090-laptop-24gb-coder390-ninfer
Qwen3.8-27B on RTX 5090 Laptop 24GB — TWIN-TURBO NVFP4 (native llama.cpp) vs Coder390 Q3 LynnStyle (.ninfer + NInfer engine in WSL2/Docker): 86 tok/s decode, 262K context, C4 aggregate 228 tok/s. Every number a controlled measurement.
- 24
- Python
- 5 wk ago

GLM-5.2-R9-Adaptive-MTP-FULL-CUDA-4x-DGX-Spark
GLM-5.2 on 4x DGX Spark with adaptive MTP K2/K4/K5, FULL CUDA graphs, DCP2, 520K context, and a downloadable ARM64 runtime image.
- 13
- Python
- Apache-2.0
- 3 mo ago

aviary-1m
Open models extended to 1M context with YaRN and certified needle by needle: Ornith, Gemma 4 uncensored, Qwen3.6 uncensored. MTP speculative decoding grafts, vision, full test harness.
- 3
- Python
- 2 mo ago

qwen38-27b-flash-mtp
Own your tokens: Qwen3.8-27B-Flash-MTP - a 27B ternary model on an 8 GB laptop GPU at 70 t/s. Launchers, features.ini and a chat client. Binaries on Releases, weights on Hugging Face.
- 8
- C++
- Apache-2.0
- 3 wk ago

GGUF-to-NVFP4-SM120
Lna-Lab production pipeline: GGUF -> modelopt-format NVFP4 + working MTP head for vLLM on RTX PRO 6000 Blackwell (SM120). Stages 2 (NVFP4) and 3 (MTP graft) are Lna-Lab originals; stage 1 (GGUF->bf16) reuses li-yifei/gguf-to-nvfp4.
- 9
- Python
- 7 mo ago

sensenova-loop-9b-nvfp4-dgx-spark
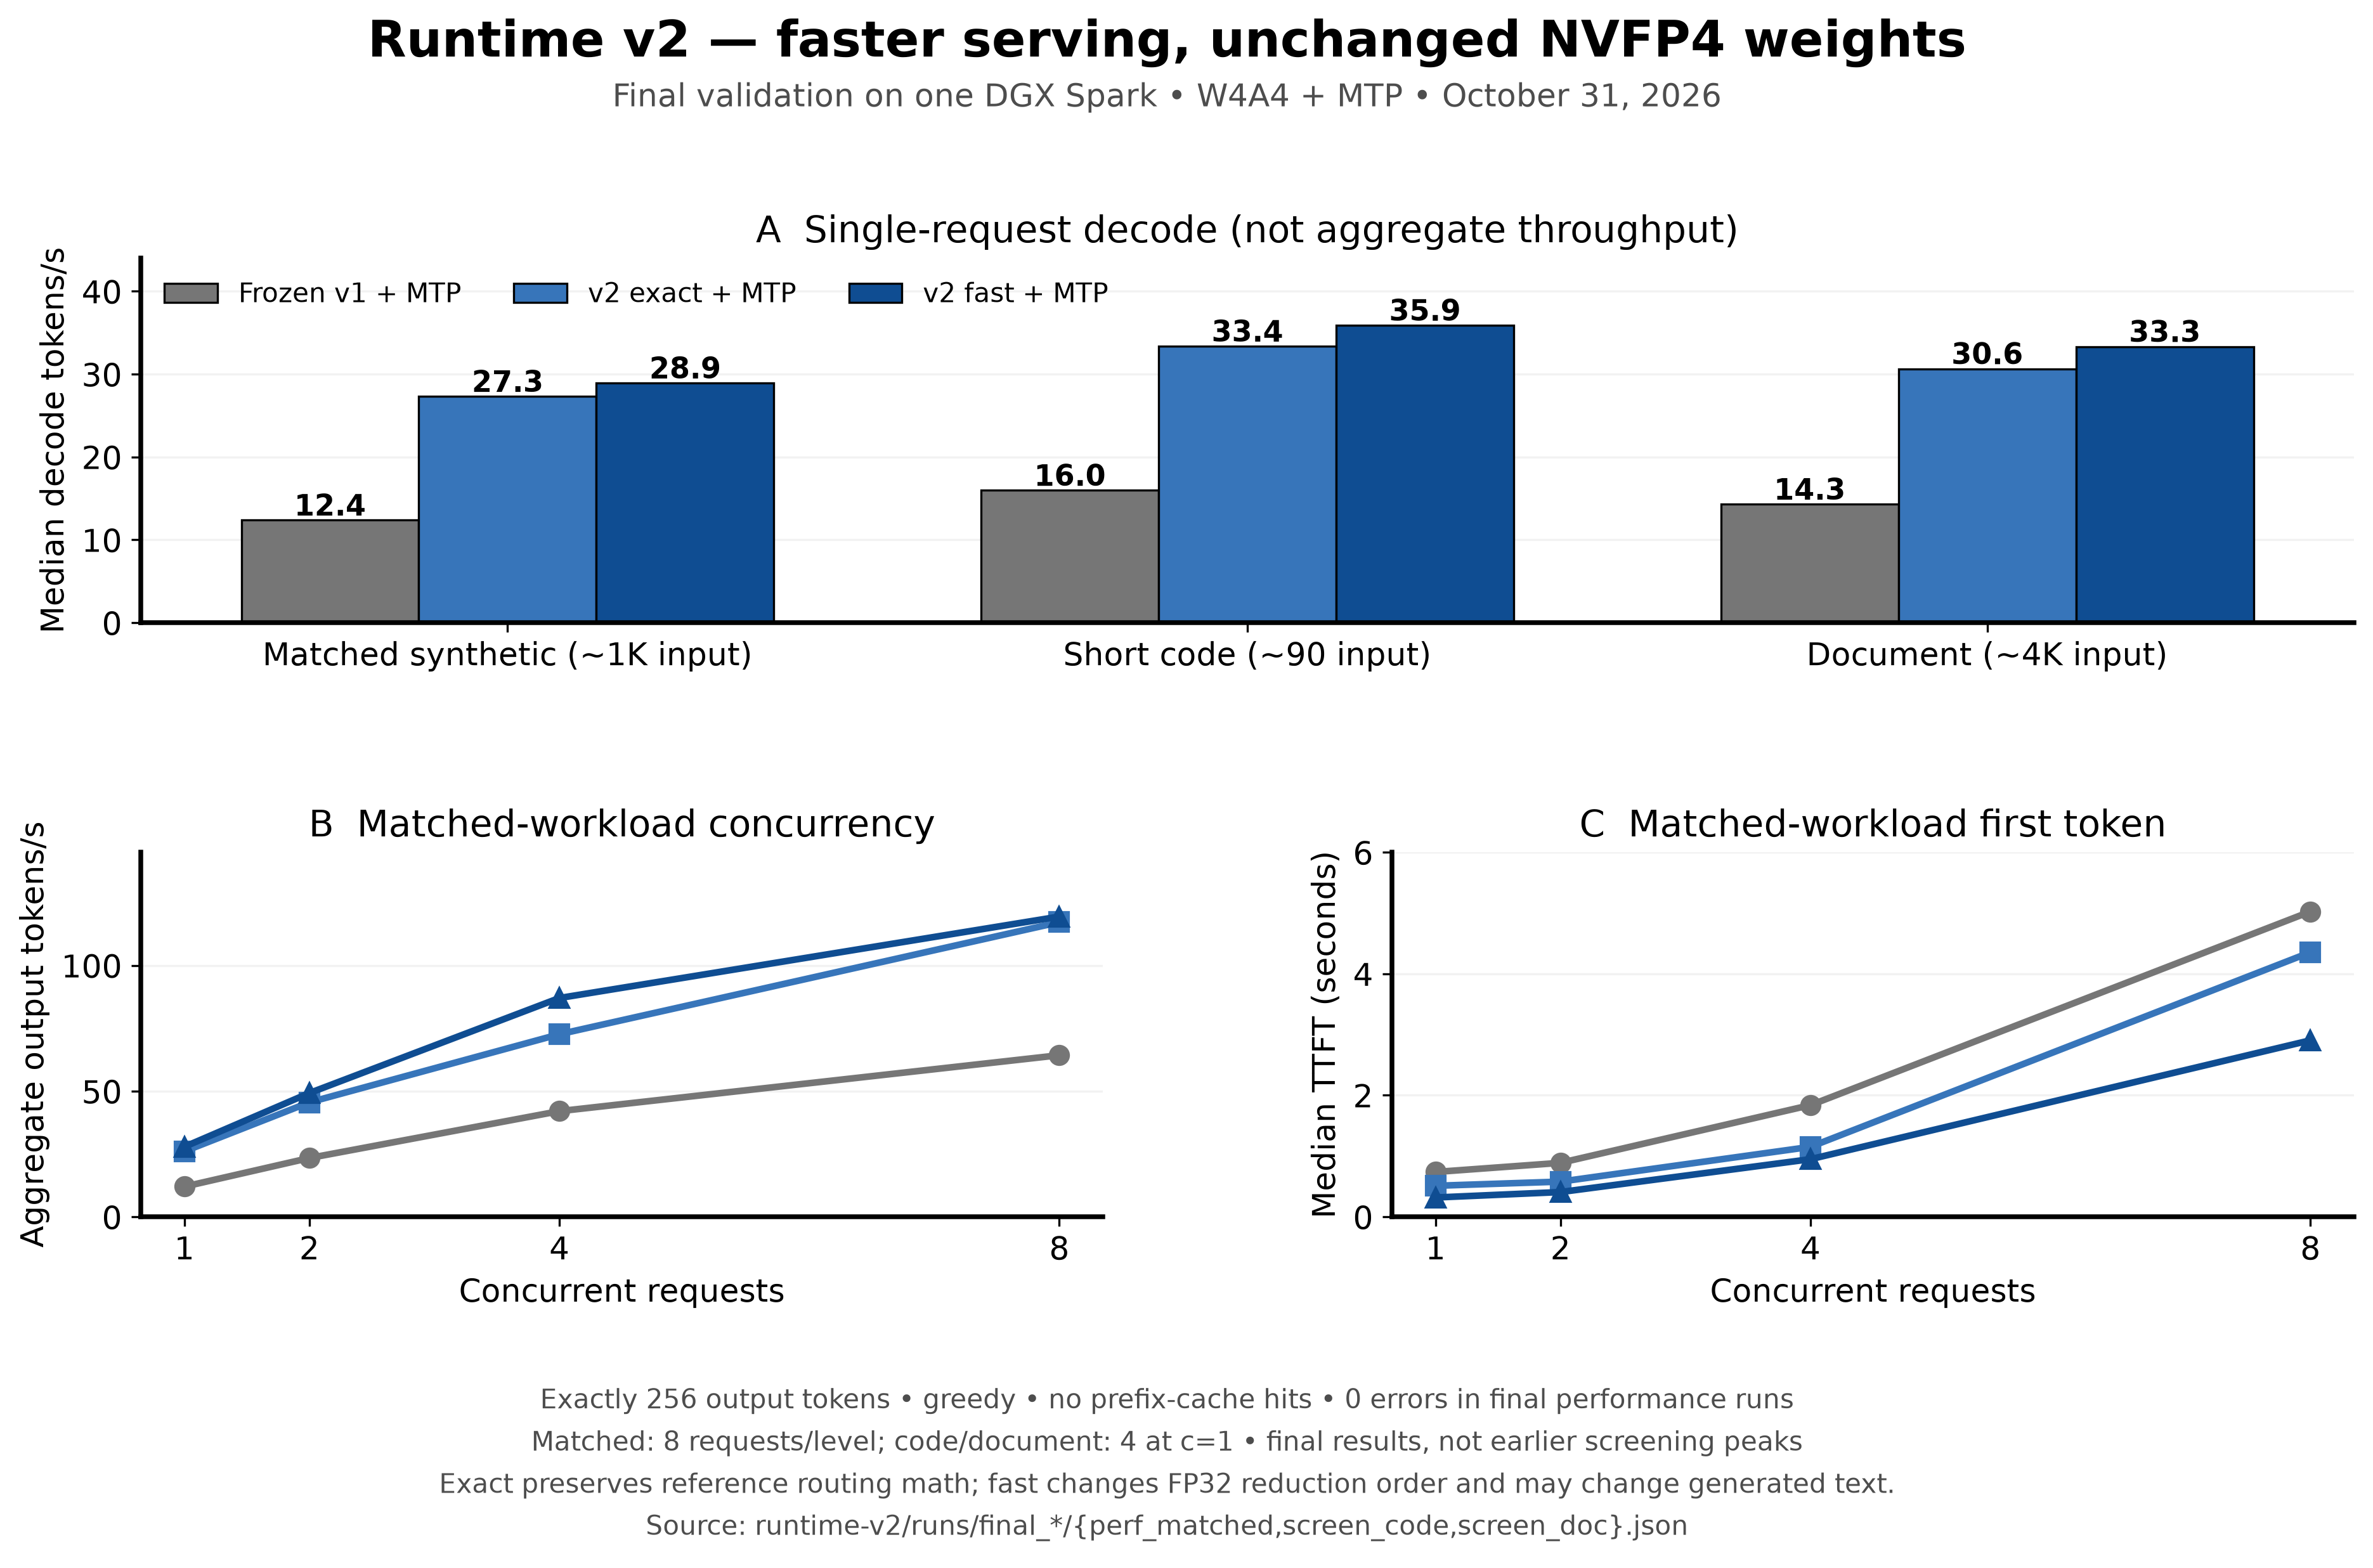
SenseNova Loop 9B NVFP4 + MTP on DGX Spark: calibrated checkpoint recipe, native FP4 runtime, reproducible evaluation and figures.
- 1
- Python
- Apache-2.0
- 3 wk ago

Nemotron-Puzzle-75B-NVFP4-1x-DGX-Spark
Nemotron Puzzle 75B-A9B NVFP4 on 1× DGX Spark (GB10): MTP, prefix cache, 4 concurrent seqs — ~40 tok/s solo, ~75 tok/s aggregate ×4
- 2
- Shell
- MIT
- 5 mo ago

SJF-Swift1.5-NInfer-GSQ-RCO-IQ3_S-MTP
Unofficial Swift 1.5 GSQ-RCO IQ3_S MTP conversion for WaveCut NInfer v3
- 1
- Python
- 8 wk ago

imatrix-gguf-quantizer
Bash script that turns a Hugging Face model into a full set of imatrix-quantized GGUF files for llama.cpp. It can also produce the vision projector (mmproj) and an MTP (multi-token prediction) head. Everything specific to one model lives in a small config file, quantizer.conf, so the same script works for any model llama.cpp can convert.
- 0
- Shell
- MIT
- 2 d ago

qwen38-flashnext-abliterated-spark
First usable Qwen3.8-Flash-Next abliterated NVFP4-PLE on a single DGX Spark. A multi-node assembly product that loaded fine but produced garbage, patched into single-node usability: healthy payloads, broken metadata (reciprocal scale_2, 73728 missing input_scale, PLE global off 3400x) fixed with 4-byte scalar patches. MTP 0 to 54.9%.
- 0
- Python
- 7 d ago

Qwen3.8-27B RTX 5090 128K Recipe
Dual-runtime 128K agent recipe for one RTX 5090
Runs in the browser on Hugging Face
- 0
- mit
- 3 mo ago
Qwen3.8-Flash-Next-Single-DGX-Spark
Serve Qwen3.8-Flash-Next NVFP4 on a single DGX Spark with TP=1 using this self-contained recipe.
- 0
- Python
- AGPL-3.0
- 5 wk ago

