turboquant


taOS
Self-hosted AI agent OS. Your memory, chat, agents, and files stay on hardware you own, offline by default, cloud by choice. Offline AI memory (taOSmd), self-hosted multi-framework group chat, a full web desktop + app store, and auto-clustering across the consumer hardware you already have (Orange/Raspberry Pi, Mac mini, gaming PC).
- 609
- Python
- AGPL-3.0
- 12 h ago

quant.cpp
LLM inference with 7x longer context. Pure C, zero dependencies. Lossless KV cache compression + single-header library.
- 407
- C
- Apache-2.0
- 7 mo ago

llamAmpere
llama.cpp fork for significantly improved performance on Ampere generation Nvidia cards (especially RTX 3090 / 3090 Ti): example: 110+ tok/s over a 100K-token generation at temperature 1 for qwen3.8, supporting full 262K ctx. Supports low memory (12gb) configs for 200k+ ctx. 120+ TPS, 3300+ prefill for QFN 3.8.
- 403
- C++
- MIT
- 12 h ago

q38rocm
Qwen 3.8 27B ROCmFP4 on AMD Strix Halo (Ryzen AI Max+ 395). Up to 36 tok/s via MTP Speculation, TurboQuant & Mesa RADV Wave64.
- 270
- Python
- 3 mo ago

llama.cpp-turboq-mtp
Qwen4-Exp (Qwen3.8-Flash-Next) SWA + MTP + PLE-on-iswa — bounded deep-context decode w/ long-range recall, TBQ4 4.25 bpv KV, DSpark + RotorQuant. Main (master) = Qwen4-Exp build; the Qwen35 SWA hybrid lives on the qwen35 branch. RTX 4090.
- 94
- C++
- MIT
- 8 wk ago

vllm-windows-build
Native Windows vLLM 0.33.0 (Python 3.13/CUDA 13.0), plus a Python 3.14/CUDA 13.2 build; older versions on the Releases page. PyTorch 2.14, FlashAttention/Rust, OpenAI serving, 10 KV formats, Multi-TurboQuant, experimental CPU/NVMe KV offload. No WSL or Docker.
- 68
- Python
- MIT
- 1 d ago

gemma-4-E4B-Agentic-Opus-Reasoning-GeminiCLI-mlx-4bit
Text generation model, used with mlx.
- 37
- 1.2k
- gemma
- 4 mo ago
multi-turboquant
Unified KV-cache compression for LLM inference: 12 Python-native methods, guarded add-on composition and routing, analytical capacity simulation, Godzilla KVarN/TriAttention with SM86/SM89 qualification, CUDA weight sharing, and multi-GPU planning.
- 30
- Python
- MIT
- 6 wk ago
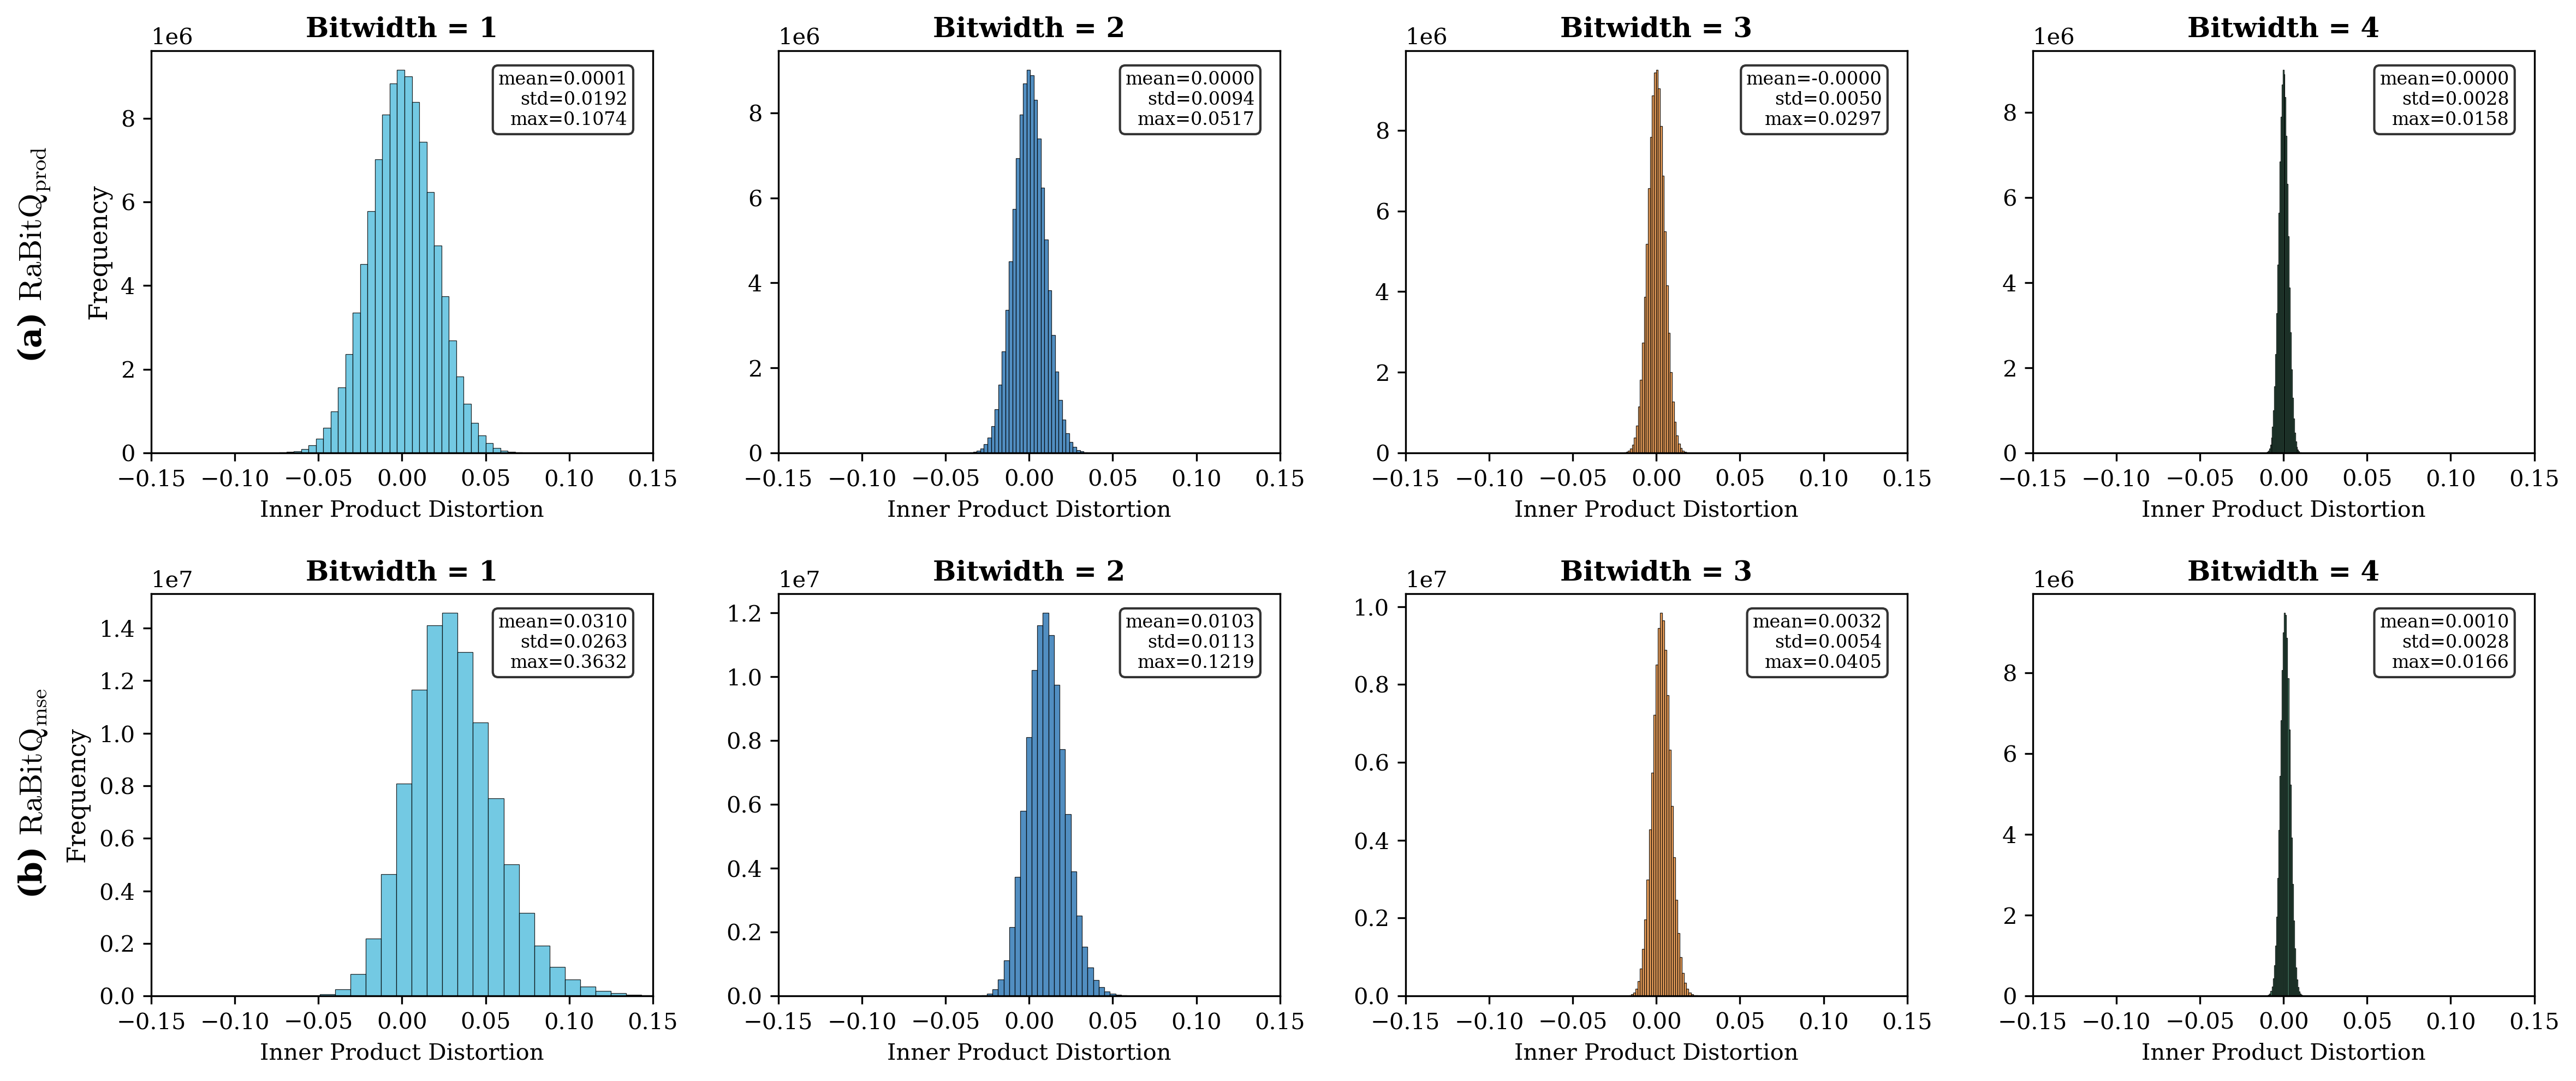
rabitq-turboquant-comparison
Code and results for "Revisiting RaBitQ and TurboQuant: a symmetric comparison of methods, theory, and experiments".
- 14
- Cuda
- Apache-2.0
- 4 mo ago

TurboQuant on Consumer GPUs — 100K Context on RTX 3090, 64K on RTX 4070
Runs in the browser on Hugging Face
- 15
- cc-by-4.0
- 8 mo ago
gemma-4-E2B-Heretic-Uncensored-mlx-4bit
Image text to text model, used with mlx.
- 24
- 2.8k
- apache-2.0
- 8 mo ago
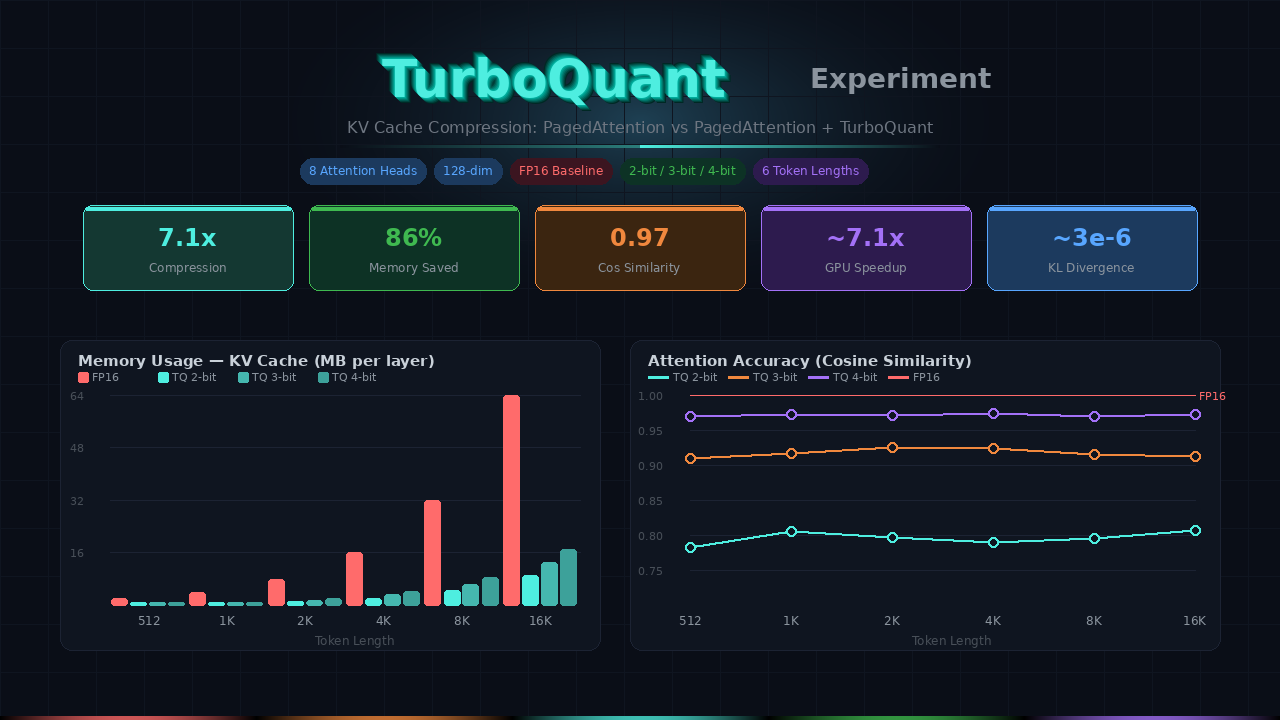
turboquant-experiment
KV Cache with PagedAttention vs PagedAttention + TurboQuant - experiments across token sizes comparing memory, latency, and accuracy.
- 5
- Python
- MIT
- 8 mo ago

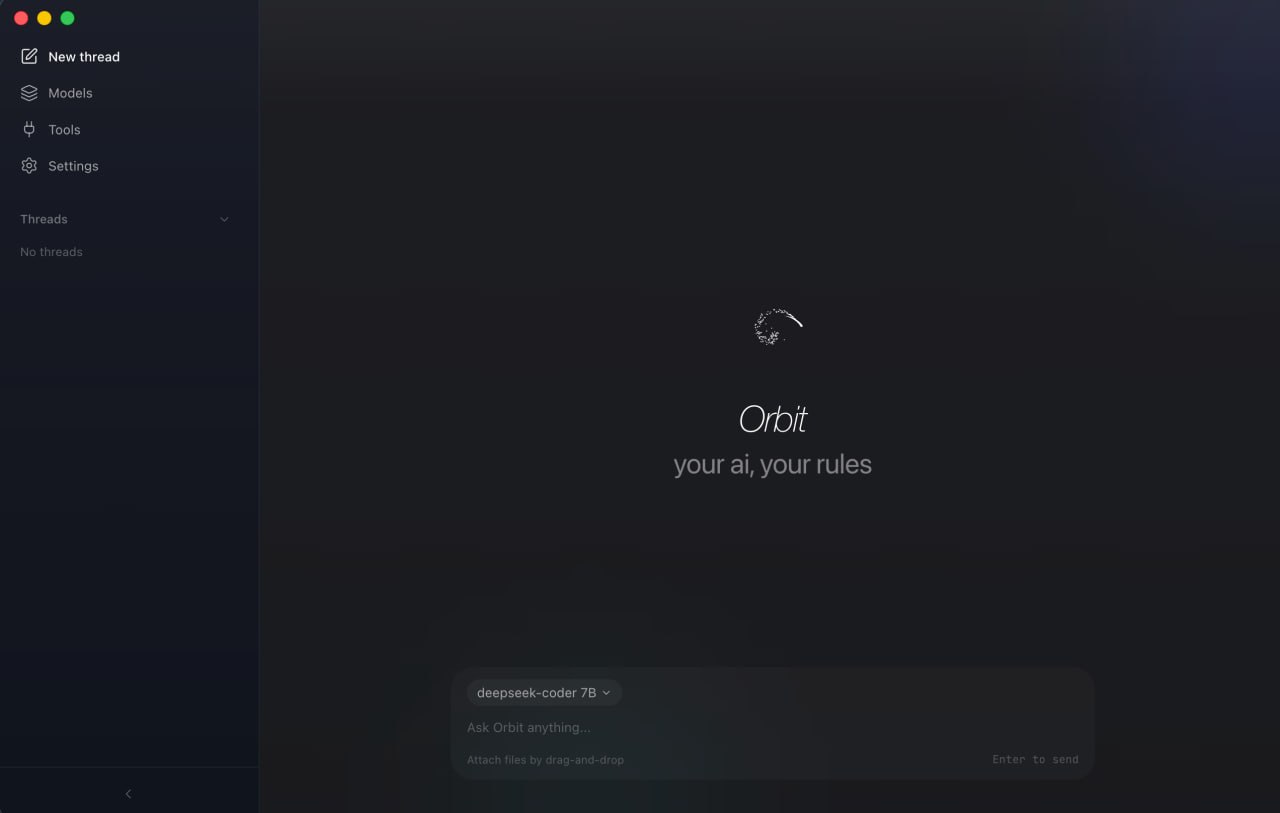
orbit
your ai, your rules. — local AI desktop app with hardware-aware model matching, threaded conversations, and TurboQuant integration. no cloud, no subscription, no data leaving your device.
- 4
- TypeScript
- 8 mo ago

qwen3.5-0.8b-custom-packed-1bit
Image text to text model, used with transformers.
- 1
- 18
- apache-2.0
- 8 mo ago

Step-3.5-Flash-Distill-MolmoWeb-8B-TQ-Mixed
- 1
- 0
- apache-2.0
- 8 mo ago
qwen3.5-0.8b-custom-packed-4bit
Image text to text model, used with transformers.
- 0
- 20
- apache-2.0
- 8 mo ago
qwen3.5-0.8b-custom-packed-8bit
Image text to text model, used with transformers.
- 0
- 13
- apache-2.0
- 8 mo ago
